See your options side by side
Choose one task and 2–4 tools. Compare pricing, output, test results and trust.
Test scope & comparison notes
These are recorded facts, not a unified ranking. Tested tiers and scope are not consistently recorded. Read pricing with its date and timing with its conditions. Privacy observations reflect visible flows and statements, not a security audit.
Cross-task capability coverage across selected products
Each product is scored independently per task edge; switch tasks below while keeping shared products selected| Task edge | ocr.space | hipdf.com | Switch / compare |
|---|---|---|---|
| PDF to Word | Not tested in topic | 70/100 DOCX · Output attached | Compare in task topic → |
| PDF compression | Not tested in topic | 86/100 PDF · Output attached | Compare in task topic → |
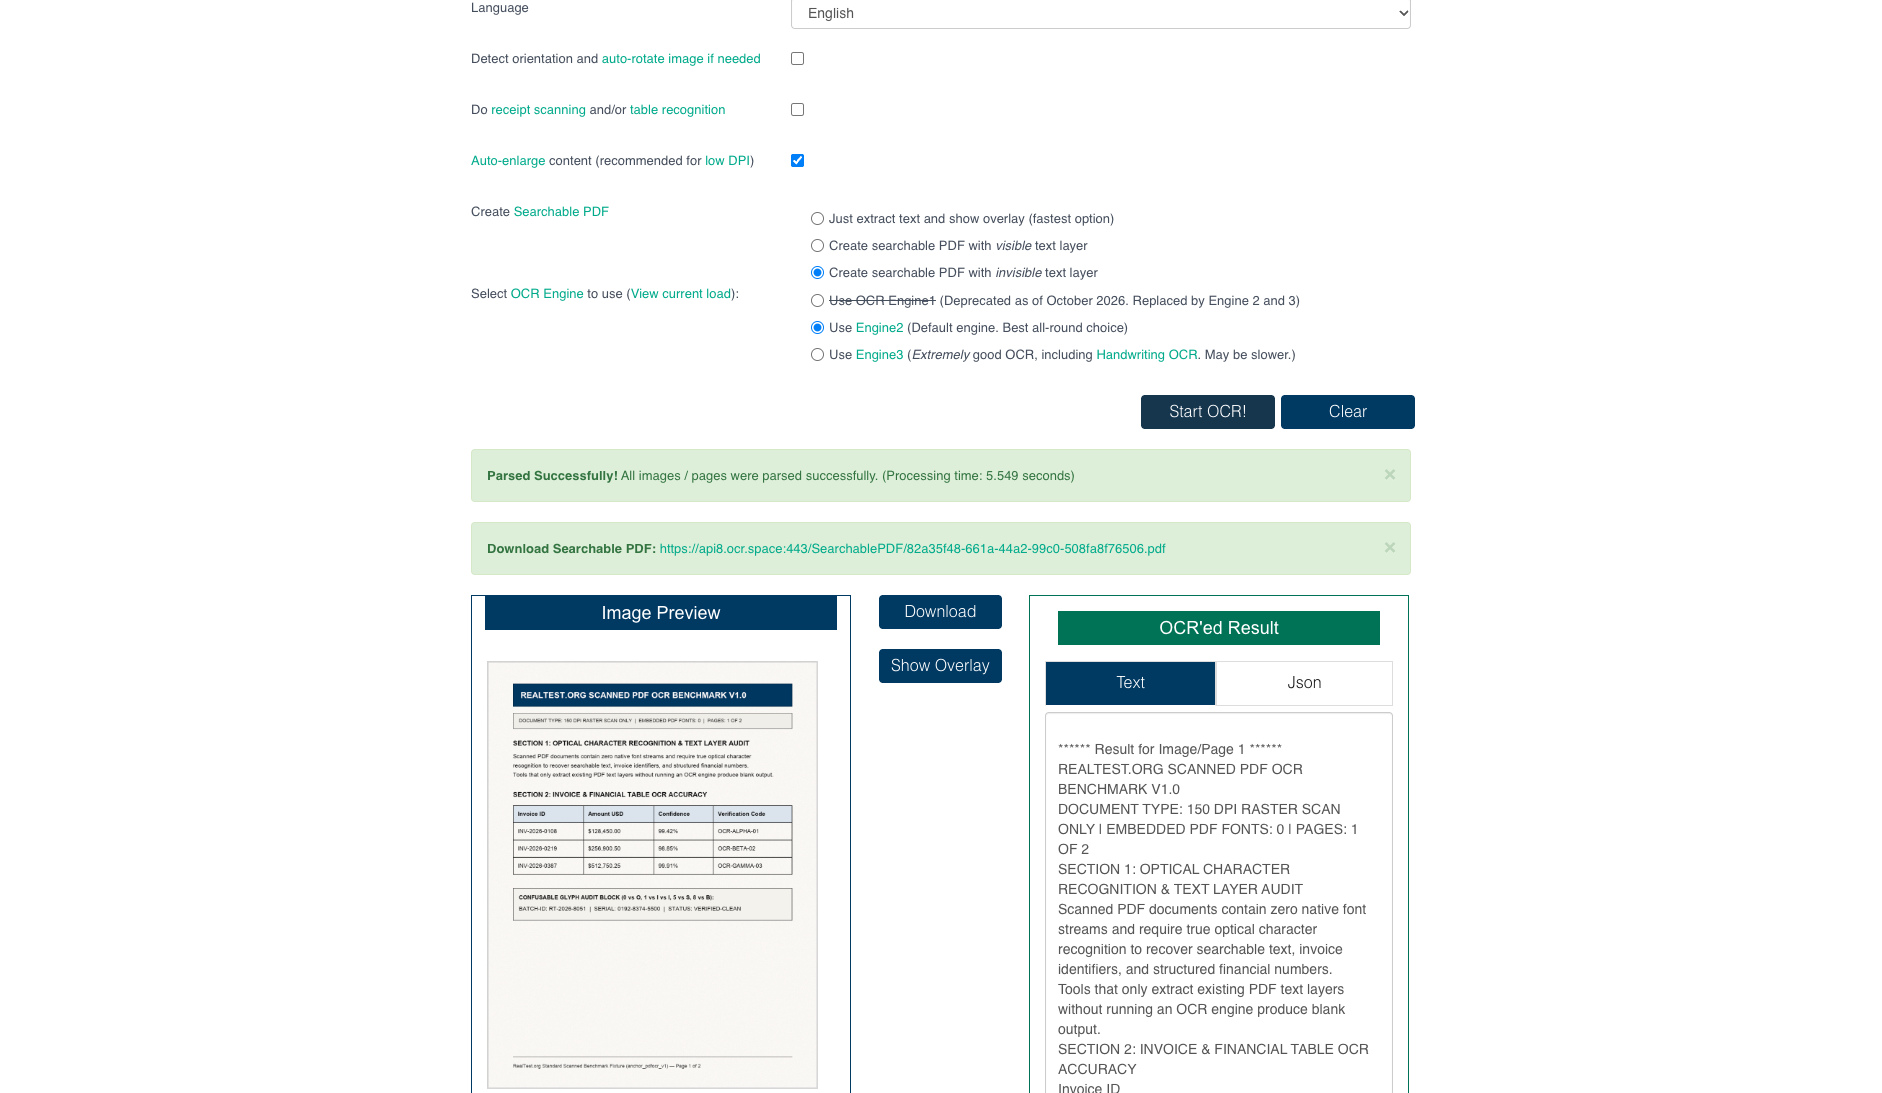
| Scanned PDF OCR | 97/100 PDF · Output attached | 77/100 DOCX · Output attached | Active task |
| PDF merge & split | Not tested in topic | 89/100 PDF · Output attached | Compare in task topic → |
Select at least 2 tools to compare
You can also filter a task page first, then compare your shortlist.
Browse this task →| Criterion | OCR.space Scanned PDF OCR 97/100 Seven-aspect task score OCR.space Scanned PDF OCR delivered outstanding benchmark results on the 2-page 150 DPI raster scan anchor, achieving a perfect 100.0% recall across headings and financial table cells while fully preserving page 2, exporting a 667.1 KB watermark-free searchable PDF in 9.01s server processing, earning an overall score of 97 (Capability 96 / Honesty 98). Tested export PDF · Output attached Historical test · 2026-11-02 | Wondershare HiPDF Scanned PDF OCR 77/100 Seven-aspect task score Blocks unauthenticated downloads after OCR completes with a mandatory login gate; signing into a free account exports an 8.3 KB 2-page `.docx` (19.75s server wait, not a searchable PDF) with 100% accuracy across all 12 confusable invoice table cells and the Page 2 token (77.8% strict substring recall due to Word auto-numbering on headings). Tested export DOCX · Output attached Historical test · 2026-10-25 |
|---|---|---|
| Pricing & rules | ||
| Pricing plans | OCR.space free web tier, free API, PRO, and PRO PDF monthly subscriptions · 2026-10-31 Plan · source date Monthly / one-time Annual bill / period Quota & limits Free Plan (Web & API)2026-10-31 ↗ Free Free Free Web tool 5 MB file cap; API provides 25,000 calls/mo (1 MB file limit, 3 pages per PDF) Engine 2 & 3, receipt/table extraction, searchable PDF creation with watermark;API rate-limited to 500 requests/day per IP; searchable PDFs contain watermark PRO Plan (Monthly)2026-10-31 ↗ USD 30/month — Monthly 300,000 API requests/month, 5 MB file size limit, 3 pages per PDF Dedicated high-performance cluster, watermark-free searchable PDFs, 100% uptime SLA;Auto-renews monthly; 3 pages per PDF cap; longer documents require PRO PDF PRO PDF Plan (Monthly)2026-10-31 ↗ USD 60/month — Monthly 300,000 API requests/month, 100 MB+ file size limit, 999+ pages per PDF Fastest response, full multi-page PDF processing (999+ pp), watermark-free PDF, 100% SLA;Auto-renews monthly; cancellable anytime 3 plan / billing-period records, all listed; — means that period is not recorded. Free web OCR supports up to 5MB without login; free API tier includes 25,000 calls/mo (1MB, 3pp); PRO is $30/month (300k calls, 5MB); PRO PDF is $60/month (300k calls, 100MB+, 999+ pages). Cancellation, sources & verification recordCancellation and refund terms unverified OCR.space Plans & Pricing ↗ · 2026-10-31 Capture 1 ↗ | HiPDF web online PDF to Word tool (former /pricing page now returns 404) · 2026-10-21 Plan · source date Monthly / one-time Annual bill / period Quota & limits Web free account2026-10-21 ↗ Free Free Free Convert and download DOCX after signing in to a free Wondershare account; numeric daily and file-size limits are not listed on the page (uploaded files deleted within 60 minutes) 1 plan / billing-period records, all listed; — means that period is not recorded. The official tool page advertises free online conversion while /pricing returns 404 and header buttons promote desktop PDFelement; downloading the converted DOCX requires signing in to a free Wondershare account, and numeric daily or file-size limits are not published on the page. Verification has gaps; unknown prices and quotas are not inferred. Cancellation, sources & verification recordCancellation and refund terms follow official checkout and help policies. HiPDF official PDF to Word tool page ↗ · 2026-10-21 Capture 1 ↗ |
| Free & trial allowance on the test date | Free web conversion up to 5MB without login; free API tier includes 25,000 calls/month | Post-OCR Mandatory Login Gate + Wondershare Pro Subscription |
| Cancellation & refunds | Not verified | Cancellation and refund terms follow official checkout and help policies. |
| Disclosure of costs & limits | Web page publicly displays all engine options and output configurations | Prompts for free account login before or upon download |
| Task quality | ||
| Measured fixture results | OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes | OCR text recall: 77.8% · Table cell accuracy: 100% · Page 2 preserved: Yes |
| Fixture findings | Injected invisible text streams across both pages (243 BT / 245 TJ operators) with 100% precision on table figures and page 2 verification codes. | Exported an 8.3 KB 2-page `.docx` document (not a searchable PDF) with 100% accuracy across 12/12 confusable invoice table cells, 2/2 body phrases, and the Page 2 token; section prefixes `1.` / `2.` were converted to Word `<w:numPr>` auto-lists and `V1.0` became `VI .0` (77.8% strict substring match). |
| Original historical observation | OCR.space processed the 644.4 KB 2-page raster PDF anchor (anchor_pdfocr_v1) via cloud Engine 2 in 9.01s with Searchable PDF mode enabled, achieving 100% recall on headings and financial table cells while fully preserving the page 2 verification code without watermarks (01_landing.png, 02_result.png, 03_download.png). | Exported an 8.3 KB 2-page `.docx` document (not a searchable PDF) with 100% accuracy across 12/12 confusable invoice table cells, 2/2 body phrases, and the Page 2 token; section prefixes `1.` / `2.` were converted to Word `<w:numPr>` auto-lists and `V1.0` became `VI .0` (77.8% strict substring match). |
| Suitable uses · historical assessment | Archivists, financial professionals, and researchers needing fast conversion of scanned PDFs into searchable PDFs or text extraction | Users needing to extract scanned PDFs into editable .docx text with 100% financial table number accuracy |
| Result & output evidence | ||
| Delivery capabilities | ||
| Recorded export specifications | PDF · Output attached · No watermark in test | DOCX · Output attached · No watermark in test |
| Historical specification note · not an official maximum | Full 2-page dual-layer searchable PDF (667.1 KB · 243 BT / 245 TJ · zero watermarks) | Full 2-page editable Word .docx (8.3 KB · not searchable PDF) |
| Watermark observation | None | Watermark-free |
| Batch & API | Not verified | Single-file OCR on free tier; batch processing per plan quota |
| Recorded free-tier dimensions | Not verified | Not verified |
| Attached file dimensions | Not verified | Not verified |
| Speed & reliability | ||
| Timing observation | Network-observed server wait: 9.01s · End-to-end reference: 10.96s | Network-observed server wait: 19.75s · End-to-end reference: 28.14s |
| Date & fixture | 2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914) | 2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914) |
| Repeated tests & reliability | No standardized repetition count, success rate or variability range is recorded. | No standardized repetition count, success rate or variability range is recorded. |
| Interaction experience | ||
| Account requirements | No login in this test | Account required in this test |
| Sign-in methods | Direct web upload without login; instant free API key access | Mandatory Wondershare Account Login at Download Step |
| Manual adjustment | Not verified | Not verified |
| Interaction observations | Not verified | Uses a post-OCR login wall at the final Download step after guests wait through upload and recognition, and only exports `.docx` / `.xlsx` / `.pptx` / `.txt` rather than an overlaid searchable `.pdf`. |
| Background & reputation | ||
| Service lifecycle notice | Not verified | Not verified |
| Operator | a9t9 software GmbH | Wondershare Online PDF Suite |
| Recorded origin | Not verified | Jurisdiction not publicly specified |
| Domain history record | Not verified | Publicly operating online service |
| Background & reputation assessment | Not verified | Developed and operated by Wondershare Technology (creator of PDFelement). |
| External reputation record | Not verified | Not verified |
| Engineering & privacy | ||
| Processing location | Uploaded for cloud processing | Uploaded for cloud processing |
| Third-party tracking record | Cloudflare · Stripe | No third-party services listed in this record; this is not proof that none exist. |
| Engineering & privacy assessment | Not verified | Processes files via `eus-storage.pdfelement.io` and `web-api.hipdf.com` async queues, requiring a Wondershare account and `pdf-equity` quota deduction to download. |
| Retention statement | Explicit retention period unconfirmed; inspect policy record | Explicit retention period unconfirmed; inspect policy record |
| Evaluation basis | ||
| Pricing transparency | 19 / 35 Allows unauthenticated guests to upload our 644.4 KB 2-page raster scan and wait for 100% cloud OCR completion, then blocks the Download button with "You need to log in to download the file" (01_landing.png, 02_workspace.png, 02_result.png, 04_download.png); signing into a free Wondershare account exports the 8.3 KB `.docx` result. | |
| Interaction restraint | 18 / 30 Uses a post-OCR login wall at the final Download step after guests wait through upload and recognition, and only exports `.docx` / `.xlsx` / `.pptx` / `.txt` rather than an overlaid searchable `.pdf`. | |
| Background & reputation | 18 / 20 Developed and operated by Wondershare Technology (creator of PDFelement). | |
| Engineering & privacy | 12 / 15 Processes files via `eus-storage.pdfelement.io` and `web-api.hipdf.com` async queues, requiring a Wondershare account and `pdf-equity` quota deduction to download. | |
| Task quality | 65 / 65 OCR Text Recall: 100% · Financial Table Cell Accuracy: 100% (12/12) · Headings Recognized: 4/4 · Page 2 Preserved: Yes | 57.3 / 65 Deterministic OCR text & table inspection: exports a 8.3 KB .docx file (rather than an overlaid searchable PDF), recovering 0/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 77.8% overall text recall) with the Page 2 verification token intact (57.3/65) |
| Deliverable specifications | 20 / 20 Clean unwatermarked export (8/8); Export spec: Full 2-page dual-layer searchable PDF (667.1 KB · 243 BT / 245 TJ · zero watermarks) | 15 / 20 Exports a 2-page watermark-free .docx file (8.3 KB) with a free account rather than a layout-preserving searchable PDF (15/20) |
| Processing speed | 11 / 15 Network-observed server wait: 9.01s (API mode: sync_json_verified; network upload 0.1s / end-to-end 10.96s shown for reference only, never penalized) | 9.5 / 15 Upload took 8.39s and cloud OCR server processing completed in 19.75s (28.14s end-to-end) (9.5/15) |