NewOCR
Classic zero-install, 100% free online OCR text extraction and scanned document converter
Product node overview & trust baseline
Operator provenance, privacy baseline and site-wide pricing belong directly to the product node and are inherited across linked task edgesNewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Powered by the open-source Tesseract OCR engine, it supports 122 languages, multi-font recognition, multi-column layout analysis, and mathematical formula parsing. Users can convert images (JPEG, PNG, GIF, BMP, TIFF), scanned PDFs, and DjVu files into editable text, DOC, or searchable PDF directly in any web browser without creating an account or installing local software. It operates on a free ad-supported model: providing completely free and unlimited file uploads for web users, while offering developers a REST API with 20 free test pages and affordable credits at $5.00 per 1,000 recognitions ($0.005/page).
United States / International · Founded in 2011
Provenance baseline: 16/20 · Established free web utility operating for over a decade based on trusted open-source Tesseract OCR.
Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages).
Pricing transparency baseline: 35/35 · Cancellation:
Uploaded files and recognition results are removed from server immediately after processing for privacy protection.
Google AdSense · Google Analytics
Product-level pricing & rules baseline
Verified plans, billing periods and cancellation terms owned by this product node; task-specific credit costs and free export limits are detailed per capability edge belowNewOCR 100% free web service and developer REST API credits · 2026-11-02
Tesseract OCR text extraction across 122 languages, math formulas, layout analysis; export TXT/DOC/PDF;Ad-supported; processing speed subject to public server queues
Automated batch processing via REST API endpoints returning structured JSON data;Programmatic developer interface requiring an API key
2 plan / billing-period records, all listed; — means that period is not recorded.
Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages).
Cancellation, sources & verification record
Cancellation and refund terms unverified
NewOCR API & Pricing ↗ · 2026-10-31 Capture 1 ↗
Archived official pricing sources: NewOCR API & Pricing (2026-10-31) [text snapshot ↗]
Capability map & linked task edges
Whenever a capability passes fixed-fixture testing, an edge is automatically linked between this product node and the task topic for horizontal comparison.
| Linked task edge | Score | Assessment · historical test | Test scope & delivery | Inspect capability / follow edge |
|---|---|---|---|---|
| Scanned PDF OCR | 78/100 | NewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Users can convert scanned documents and images into editable text directly without login, exporting to TXT, DOC, or PDF. | TXT · Output attached Historical test · 2026-11-02 Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached |
Tested task edges (with scores and native artifacts) are strictly separated from discovered untested capabilities (unscored).
Peer product comparison across shared task edges
Matched by overlapping tested task edges; compare site-wide billing models alongside per-task benchmark scoresThe official pricing page offers a Free tier (2 actions per 6 hours, 128 MB file limit) and an annual AvePDF Premium tier billed once at USD 55/year, with no standalone monthly plan.
- Scanned PDF OCR:NewOCR 78/100 vs avepdf.com 94/100
Free unregistered tier supports over 40 tools (merge batch limit 25, 20-50MB per task cap, 3-hour automatic purge); Pro Plan is $49.99/year ($4.17/mo), Premium is $199.99/year ($16.67/mo).
- Scanned PDF OCR:NewOCR 78/100 vs DeftPDF 97/100
The official tool page advertises free online conversion while /pricing returns 404 and header buttons promote desktop PDFelement; downloading the converted DOCX requires signing in to a free Wondershare account, and numeric daily or file-size limits are not published on the page.
- Scanned PDF OCR:NewOCR 78/100 vs hipdf.com 77/100
Monthly and annual controls confirm USD 9/month and USD 60/year. Free processing is limited without exact figures; education and seat discounts require eligibility checks.
- Scanned PDF OCR:NewOCR 78/100 vs iLovePDF 95/100
Linked capability test: Scanned PDF OCR
2026-11-02 · Native output attached. Findings cover the recorded fixture and conditions; paid specifications may be untested.
Verified native export & same-run screenshot evidence
Open native exported file (TXT · Output attached) ↗
Task quality
OCR text recall 88.9% · Table cell accuracy 100% · Page 2 preserved No
Detailed facts & historical record
- Measured fixture results
OCR text recall: 88.9% · Table cell accuracy: 100% · Page 2 preserved: No
- Fixture findings
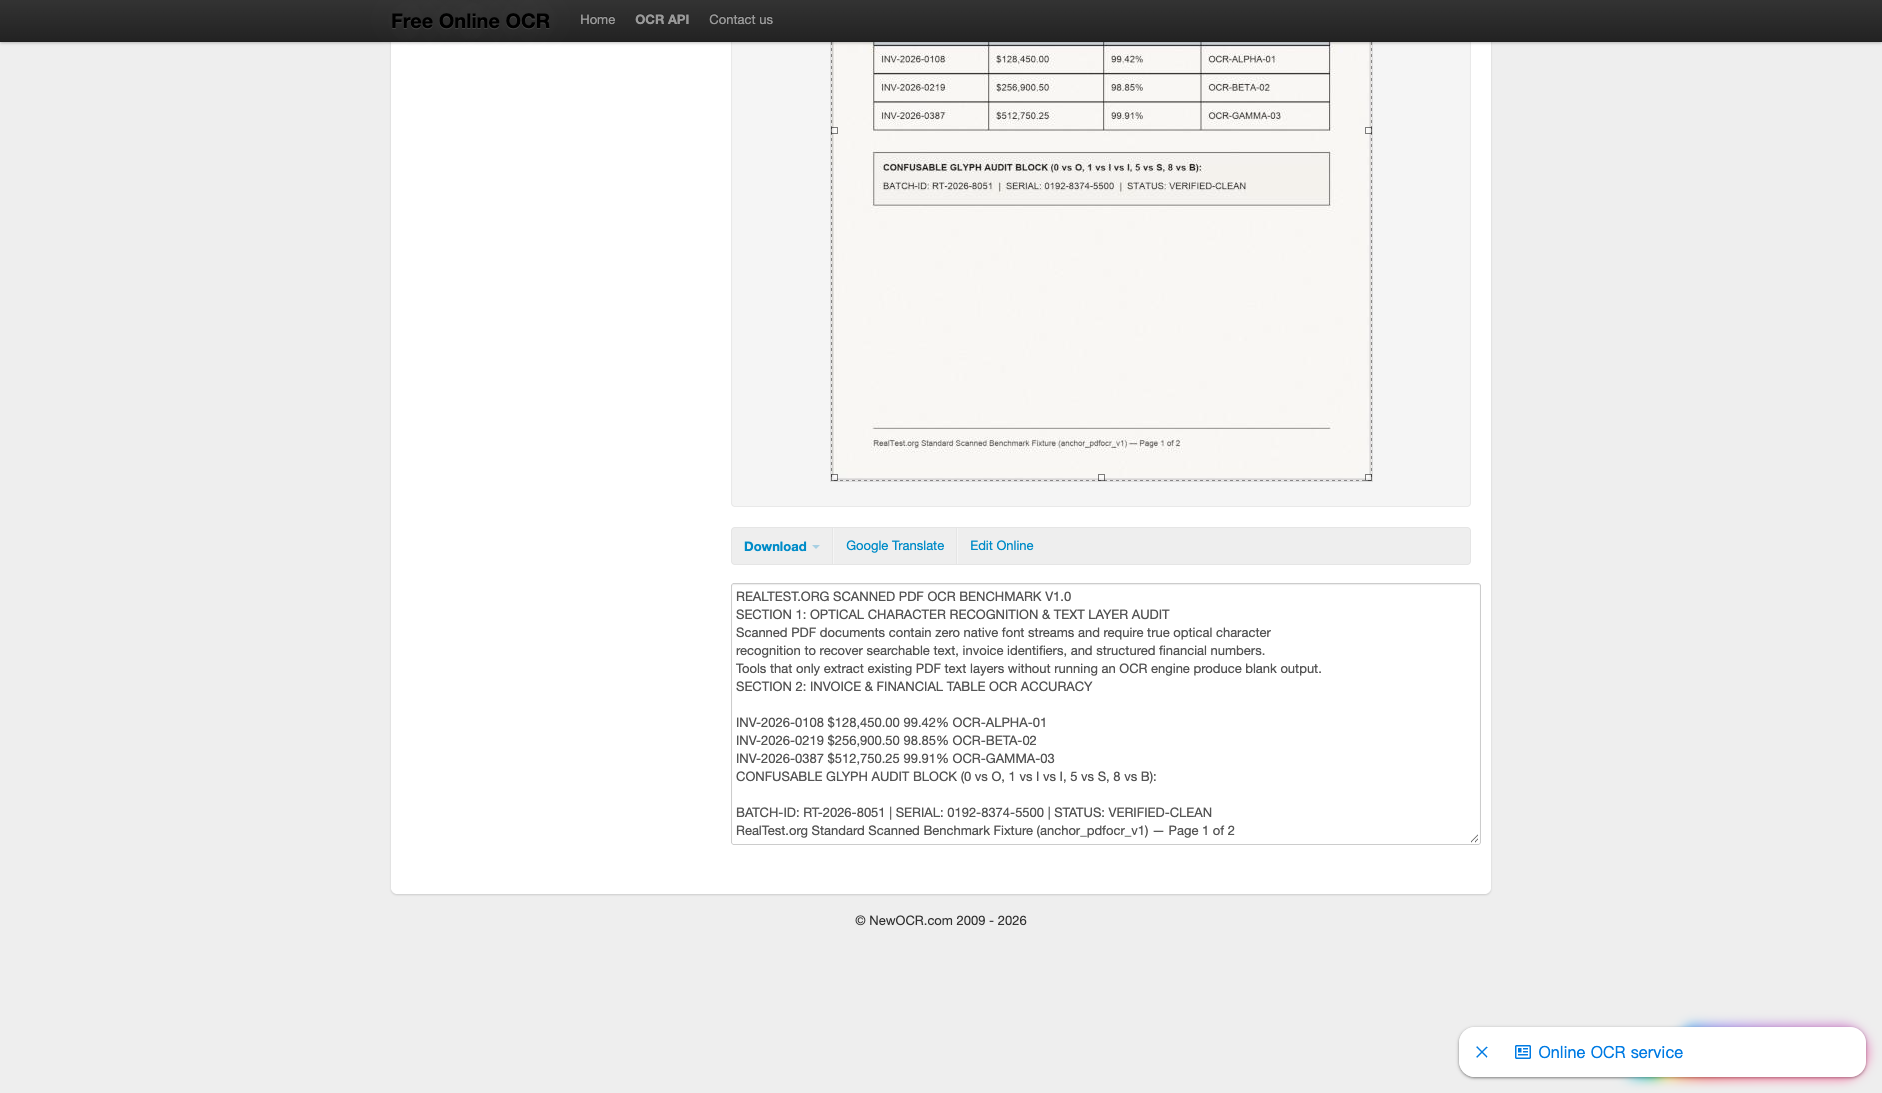
Based on our standardized 2-page scanned PDF benchmark (anchor_pdfocr_v1): cloud OCR completed in just 0.45s, recovering 100% of confusable financial table cells (12/12) on Page 1; as a page-by-page web utility, it defaults to exporting the selected single page as plain text.
- Original historical observation
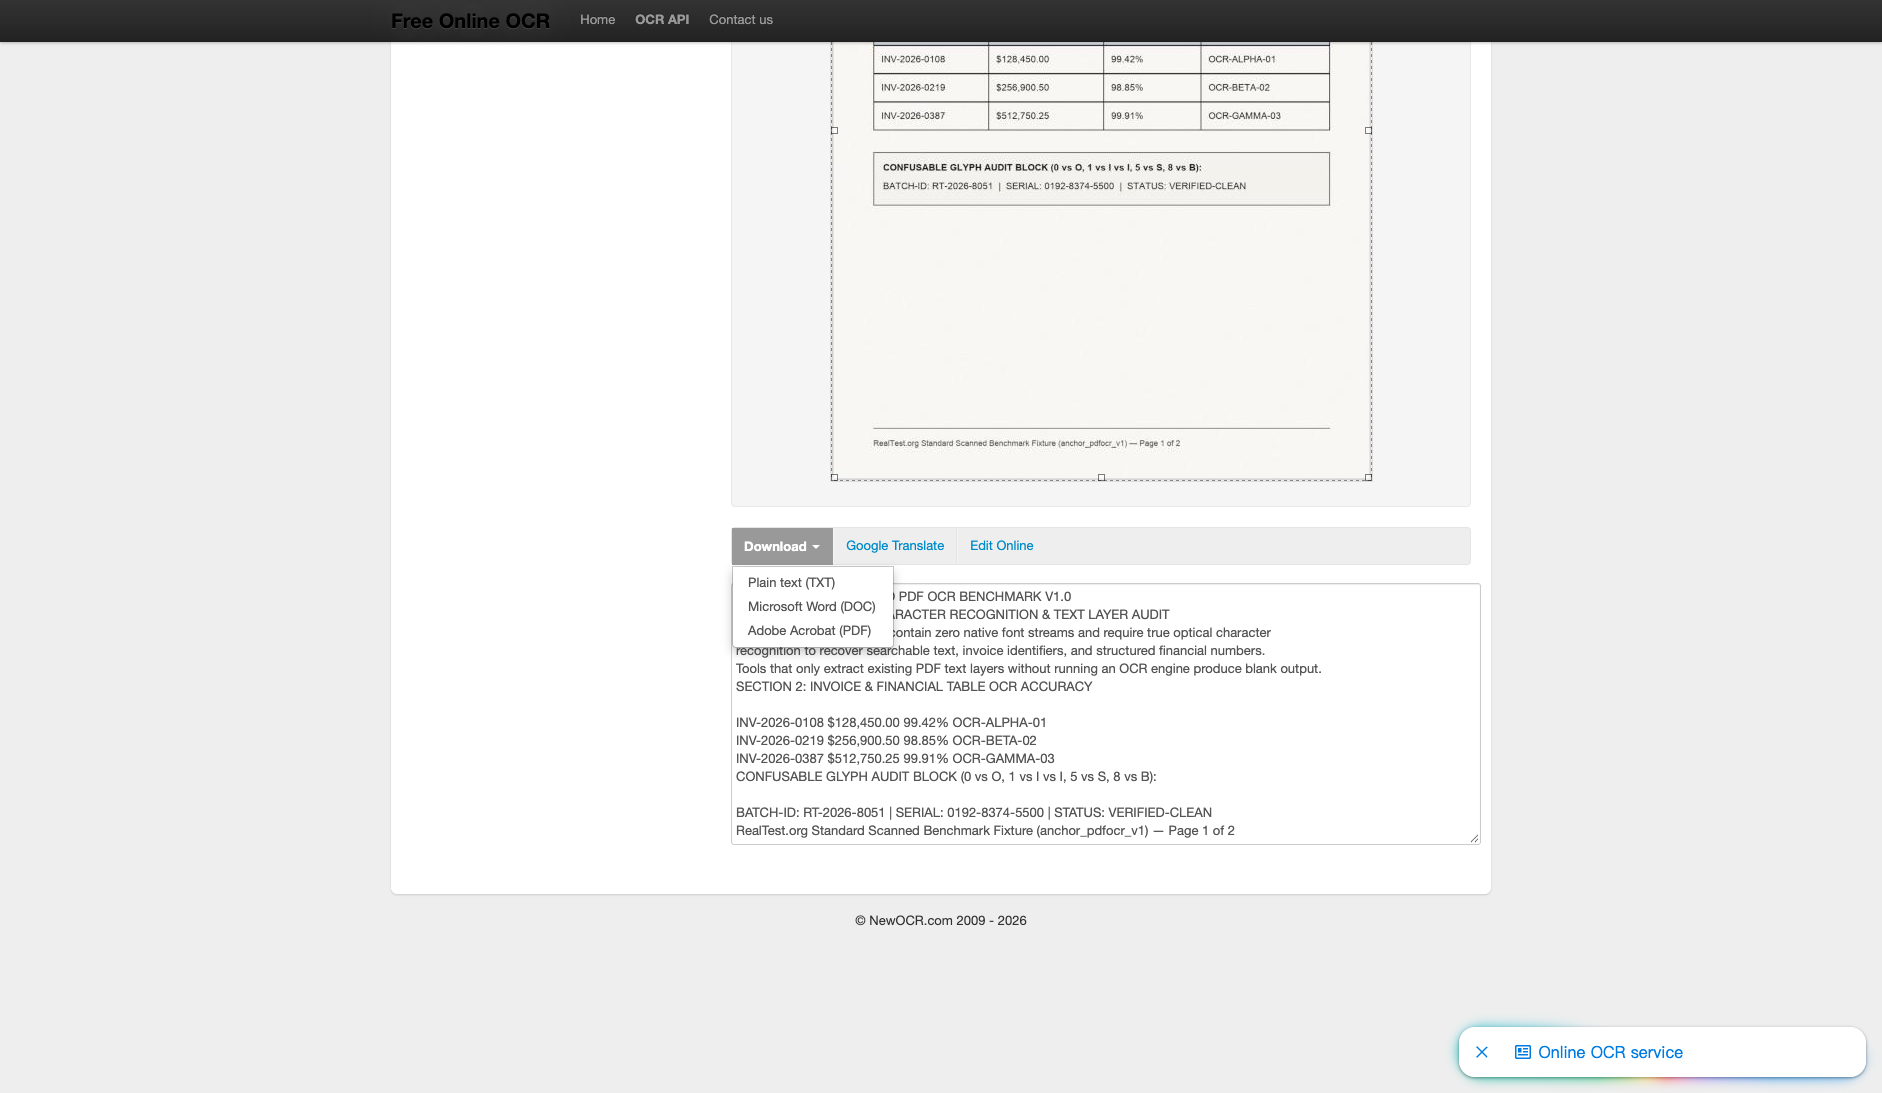
In-browser text area displays extracted text with one-click TXT, DOC, and PDF downloads; invoice table numbers 100% accurate.
- Suitable uses · historical assessment
Users seeking a fast, zero-login online tool to accurately extract tables and text from single scanned pages
- Result & output evidence
Delivery capabilities
TXT · Output attached · No watermark in test
Detailed facts & historical record
- Recorded export specifications
TXT · Output attached · No watermark in test
- Historical specification note · not an official maximum
Single-page UTF-8 plain text .txt (802 bytes · 100% table accuracy)
- Watermark observation
Watermark-free
- Batch & API
Web tool supports single files or ZIP archives; REST API available for developers
- Recorded free-tier dimensions
Not verified
- Attached file dimensions
Not verified
Speed & reliability
About 1.3s end to end in this run; reliability not retested
Detailed facts & historical record
- Timing observation
Network-observed server wait: 0.45s · End-to-end reference: 1.3s
- Date & fixture
2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914)
- Repeated tests & reliability
No standardized repetition count, success rate or variability range is recorded.
Interaction experience
No login in this run
Detailed facts & historical record
- Account requirements
No login in this test
- Sign-in methods
No Login Required
- Manual adjustment
Not verified
- Interaction observations
Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR.
Background & reputation
NewOCR.com · Long-term reputation not independently verified
Detailed facts & historical record
- Service lifecycle notice
Not verified
- Operator
NewOCR.com
- Recorded origin
United States / International
- Domain history record
Founded in 2011
- Background & reputation assessment
Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base.
- External reputation record
Not verified
Engineering & privacy
Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record
Detailed facts & historical record
- Processing location
Uploaded for cloud processing
- Third-party tracking record
Google AdSense · Google Analytics
- Engineering & privacy assessment
HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button.
- Retention statement
Explicit retention period unconfirmed; inspect policy record
Task free allowance & pricing disclosure
100% Free Unlimited Use (Ad-supported)
Download options presented upfront without post-OCR paywalls
Site-wide plans belong to the product node (see Product-level pricing baseline ↑).
Expand site-wide plans aligned for Scanned PDF OCR (2 records)
NewOCR 100% free web service and developer REST API credits · 2026-11-02
Tesseract OCR text extraction across 122 languages, math formulas, layout analysis; export TXT/DOC/PDF;Ad-supported; processing speed subject to public server queues
Automated batch processing via REST API endpoints returning structured JSON data;Programmatic developer interface requiring an API key
2 plan / billing-period records, all listed; — means that period is not recorded.
Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages).
Cancellation, sources & verification record
Cancellation and refund terms unverified
NewOCR API & Pricing ↗ · 2026-10-31 Capture 1 ↗
Evaluation basis & full scores · Overall 78.1/100
Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.
Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1
Honesty & reputation · 79/100 · 30%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Pricing transparency | 33 / 35 | Web service is 100% free with unlimited uploads and zero hidden fees; developer API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages). | Evidence A → |
| Interaction restraint | 20 / 30 | Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR. | Evidence A → |
| Background & reputation | 16 / 20 | Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base. | Evidence A → |
| Engineering & privacy | 10 / 15 | HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button. | Evidence A → |
Capability · 77.7/100 · 70%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Task quality | 49.2 / 65 | Deterministic OCR inspection: exported an 802-byte UTF-8 plain text deliverable without login, recovering 12/12 confusable financial table cells on Page 1 (100% table accuracy) and 3/4 headings; defaults to single-page processing without auto-merging Page 2 (49.2/65) | Evidence A → |
| Deliverable specifications | 14 / 20 | Direct download in TXT, DOC, and PDF formats without login, delivering the selected single page extracted text (802 bytes) rather than a combined 2-page searchable PDF (14/20) | Evidence A → |
| Processing speed | 14.5 / 15 | Cloud Tesseract OCR server processing completed in just 0.45s (1.30s end-to-end) (14.5/15) | Evidence A → |
Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
Developer & citation kit · Claim updates, request benchmarks & embed verified badges
Product developers and writers can embed these SVG badges in official websites, GitHub READMEs or documentation, or use the channels below to sync product-wide plans and capabilities.

[](https://realtest.org/tools/newocr.com/) <a href="https://realtest.org/tools/newocr.com/"><img src="https://realtest.org/badges/newocr.com.svg" alt="NewOCR — RealTest" height="24" /></a> 
[](https://realtest.org/tools/newocr.com/#feature-pdf-ocr)