See your options side by side
Choose one task and 2–4 tools. Compare pricing, output, test results and trust.
Test scope & comparison notes
These are recorded facts, not a unified ranking. Tested tiers and scope are not consistently recorded. Read pricing with its date and timing with its conditions. Privacy observations reflect visible flows and statements, not a security audit.
Cross-task capability coverage across selected products
Each product is scored independently per task edge; switch tasks below while keeping shared products selected| Task edge | everytool4u.com | newocr.com | Switch / compare |
|---|---|---|---|
| Background removal | 73/100 1600 × 1600 · PNG | Not tested in topic | Compare in task topic → |
| PDF to Word | 81/100 DOCX · Output attached | Not tested in topic | Compare in task topic → |
| PDF compression | 81/100 PDF · Output attached | Not tested in topic | Compare in task topic → |
| Scanned PDF OCR | 96/100 PDF · Output attached | 78/100 TXT · Output attached | Active task |
| PDF merge & split | 97/100 PDF · Output attached | Not tested in topic | Compare in task topic → |
Select at least 2 tools to compare
You can also filter a task page first, then compare your shortlist.
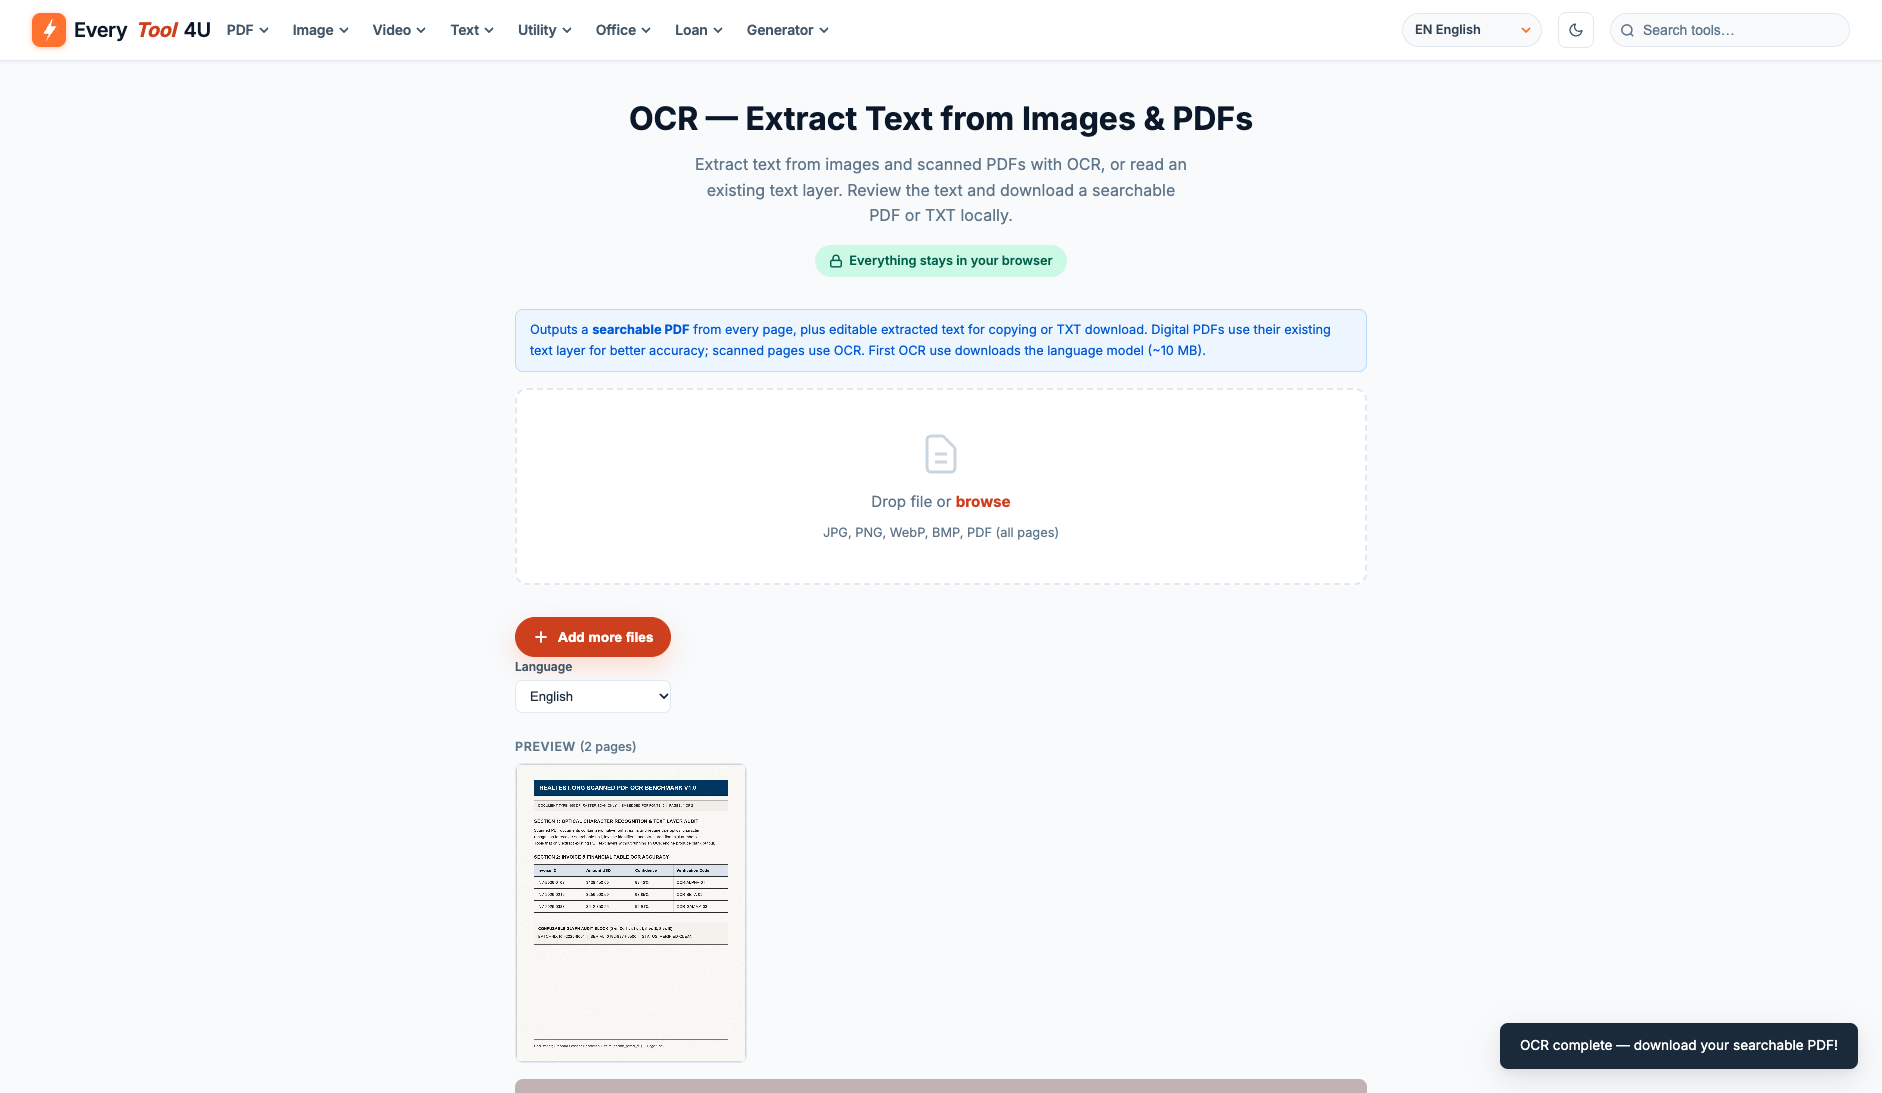
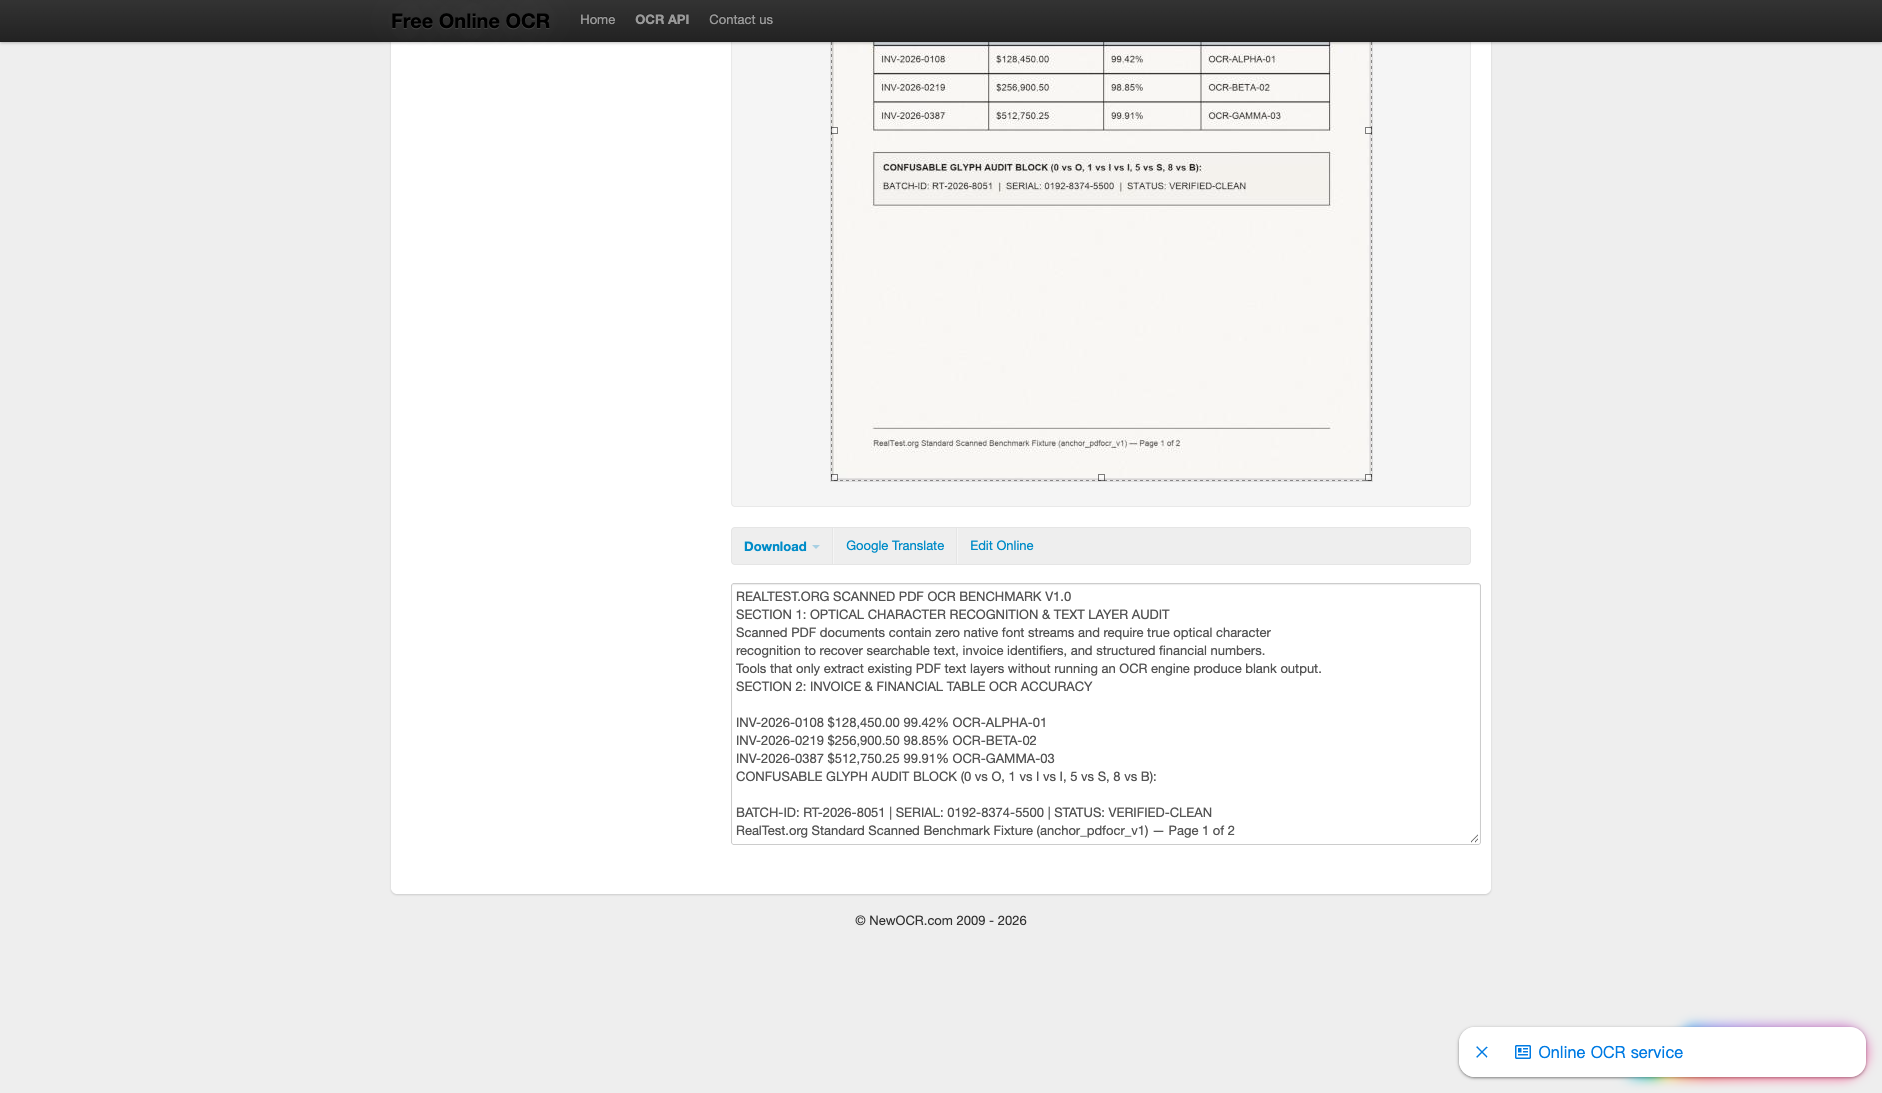
Browse this task →| Criterion | EveryTool4U Scanned PDF OCR 96/100 Seven-aspect task score EveryTool4U provides a 100% login-free client-side searchable PDF OCR tool running entirely in the browser, injecting text layers in 20.97s with zero uploads. Tested export PDF · Output attached Historical test · 2026-11-05 | NewOCR Scanned PDF OCR 78/100 Seven-aspect task score NewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Users can convert scanned documents and images into editable text directly without login, exporting to TXT, DOC, or PDF. Tested export TXT · Output attached Historical test · 2026-11-02 |
|---|---|---|
| Pricing & rules | ||
| Pricing plans | EveryTool4U platform tool authorization and service pricing · 2026-11-01 Plan · source date Monthly / one-time Annual bill / period Quota & limits Free Tier2026-11-01 ↗ Free Free Free Unlimited usage across 109 online tools with no daily quota or queue limits Includes PDF merge, split, compression, Word conversion, OCR, image compression, background removal, and office utilities;Client-side processing; performance on large files depends on local device RAM and browser limits;No account registration or renewal required;Permanent access 1 plan / billing-period records, all listed; — means that period is not recorded. All tools are completely free indefinitely without registration or subscriptions; most tasks execute entirely on-device. Cancellation, sources & verification recordCancellation and refund terms unverified EveryTool4U Official Homepage ↗ · 2026-11-01 Capture 1 ↗ EveryTool4U About and Privacy Architecture Page ↗ · 2026-11-01 Capture 1 ↗ | NewOCR 100% free web service and developer REST API credits · 2026-11-02 Plan · source date Monthly / one-time Annual bill / period Quota & limits Free Web Service2026-10-31 ↗ Free Free Free Zero login required, unlimited file uploads, supports single and multi-page documents and ZIP archives Tesseract OCR text extraction across 122 languages, math formulas, layout analysis; export TXT/DOC/PDF;Ad-supported; processing speed subject to public server queues Developer API Credits2026-10-31 ↗ USD 5 · one-time payment Usage / one-time Usage / one-time 1,000 OCR API recognition calls ($0.005 per call) Automated batch processing via REST API endpoints returning structured JSON data;Programmatic developer interface requiring an API key 2 plan / billing-period records, all listed; — means that period is not recorded. Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages). Cancellation, sources & verification recordCancellation and refund terms unverified NewOCR API & Pricing ↗ · 2026-10-31 Capture 1 ↗ |
| Free & trial allowance on the test date | Entire platform free without task limits or quotas | 100% Free Unlimited Use (Ad-supported) |
| Cancellation & refunds | Not verified | Not verified |
| Disclosure of costs & limits | Immediate processing with confidence badge, editable text box, and direct download button | Download options presented upfront without post-OCR paywalls |
| Task quality | ||
| Measured fixture results | OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes | OCR text recall: 88.9% · Table cell accuracy: 100% · Page 2 preserved: No |
| Fixture findings | Under anchor_pdfocr_v1 image-only scanned PDF, it exported a 1.4 MB searchable PDF with 226 text operators, 100% recall across headings and tables. | Based on our standardized 2-page scanned PDF benchmark (anchor_pdfocr_v1): cloud OCR completed in just 0.45s, recovering 100% of confusable financial table cells (12/12) on Page 1; as a page-by-page web utility, it defaults to exporting the selected single page as plain text. |
| Original historical observation | EveryTool4U processed the scanned PDF in 20.97s using in-browser Tesseract.js, producing a 1.4 MB searchable PDF with 100% text recall and zero watermarks. | In-browser text area displays extracted text with one-click TXT, DOC, and PDF downloads; invoice table numbers 100% accurate. |
| Suitable uses · historical assessment | Users needing searchable Ctrl+F PDFs from scanned documents while ensuring complete file confidentiality | Users seeking a fast, zero-login online tool to accurately extract tables and text from single scanned pages |
| Result & output evidence | ||
| Delivery capabilities | ||
| Recorded export specifications | PDF · Output attached · No watermark in test | TXT · Output attached · No watermark in test |
| Historical specification note · not an official maximum | Full 2-Page Watermark-Free Searchable PDF (1,400.6 KB · 226 Operators) | Single-page UTF-8 plain text .txt (802 bytes · 100% table accuracy) |
| Watermark observation | Watermark-free | Watermark-free |
| Batch & API | Multi-page local PDF processing, multi-language dictionary selector, and TXT export | Web tool supports single files or ZIP archives; REST API available for developers |
| Recorded free-tier dimensions | Not verified | Not verified |
| Attached file dimensions | Not verified | Not verified |
| Speed & reliability | ||
| Timing observation | Recorded local processing time: 0s · End-to-end reference: 20.97s | Network-observed server wait: 0.45s · End-to-end reference: 1.3s |
| Date & fixture | 2026-11-05 · anchor_pdfocr_v1 · Client-Side (WASM / Browser Local) | 2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914) |
| Repeated tests & reliability | No standardized repetition count, success rate or variability range is recorded. | No standardized repetition count, success rate or variability range is recorded. |
| Interaction experience | ||
| Account requirements | No login in this test | No login in this test |
| Sign-in methods | 100% login-free local execution and export | No Login Required |
| Manual adjustment | Not verified | Not verified |
| Interaction observations | Clean utility UI with OCR confidence badges, editable text review area, and instant searchable PDF download (02_result.png, 03_download.png). | Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR. |
| Background & reputation | ||
| Service lifecycle notice | Not verified | Not verified |
| Operator | EveryTool4U | NewOCR.com |
| Recorded origin | United States / Independent Developer | United States / International |
| Domain history record | Launched in 2026 | Founded in 2011 |
| Background & reputation assessment | Independent developer platform launched in 2026 disclosing open-source libraries transparently. | Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base. |
| External reputation record | Not verified | Not verified |
| Engineering & privacy | ||
| Processing location | On-device processing | Uploaded for cloud processing |
| Third-party tracking record | Google AdSense · Google Tag Manager | Google AdSense · Google Analytics |
| Engineering & privacy assessment | 100% client-side Tesseract.js and jsPDF execution; zero document upload to external servers. | HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button. |
| Retention statement | This flow runs locally; post-close deletion not independently verified | Explicit retention period unconfirmed; inspect policy record |
| Evaluation basis | ||
| Pricing transparency | 35 / 35 100% free with no login, subscription, or paywall traps (01_landing.png). | 33 / 35 Web service is 100% free with unlimited uploads and zero hidden fees; developer API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages). |
| Interaction restraint | 28 / 30 Clean utility UI with OCR confidence badges, editable text review area, and instant searchable PDF download (02_result.png, 03_download.png). | 20 / 30 Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR. |
| Background & reputation | 13 / 20 Independent developer platform launched in 2026 disclosing open-source libraries transparently. | 16 / 20 Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base. |
| Engineering & privacy | 15 / 15 100% client-side Tesseract.js and jsPDF execution; zero document upload to external servers. | 10 / 15 HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button. |
| Task quality | 65 / 65 Client-side Tesseract.js / WASM searchable PDF reconstruction: injected 226 BT/TJ operators over 2 pages, achieving 100% text recall (4/4 headings, 2/2 body phrases) and 100% table accuracy (12/12 cells) with Page 2 token intact (65.0/65) | 49.2 / 65 Deterministic OCR inspection: exported an 802-byte UTF-8 plain text deliverable without login, recovering 12/12 confusable financial table cells on Page 1 (100% table accuracy) and 3/4 headings; defaults to single-page processing without auto-merging Page 2 (49.2/65) |
| Deliverable specifications | 20 / 20 Free export of full 2-page watermark-free searchable PDF with invisible text layer overlay (20.0/20) | 14 / 20 Direct download in TXT, DOC, and PDF formats without login, delivering the selected single page extracted text (802 bytes) rather than a combined 2-page searchable PDF (14/20) |
| Processing speed | 13.5 / 15 Client-side multi-threaded WASM OCR finished 2 pages in 20.97s (13.5/15) | 14.5 / 15 Cloud Tesseract OCR server processing completed in just 0.45s (1.30s end-to-end) (14.5/15) |