| Pricing & rules |
|---|
| Pricing plans |
ElevenLabs sitewide audio generation, voice cloning, and transcription credits; monthly and free tiers · 2026-11-12
Plan · source date Monthly / one-time Annual bill / period Quota & limits Free Free Free 10,000 credits/month (~10 min audio), 3 Studio projects, non-commercial use USD 6/month — Monthly 30,000 credits/month (~30 min audio), commercial license, instant voice cloning, $1 promo first month, then $6/mo USD 22/month — Monthly 121,000 credits/month (~121 min audio), professional voice cloning, 192kbps audio quality, $11 promo first month USD 99/month — Monthly 600,000 credits/month (~600 min audio), 44.1kHz PCM lossless output, high concurrency support 4 plan / billing-period records, all listed; — means that period is not recorded.
Free plan includes 10k credits/month (non-commercial); paid plans feature first-month promotions (Starter $1 first mo, then $6/mo; Creator $11 first mo, then $22/mo); overage billed per minute; taxes excluded.
Cancellation, sources & verification recordCancellation and refund terms unverified ElevenLabs official homepage ↗ · 2026-11-07 Capture 1 ↗ ElevenLabs official pricing plans page ↗ · 2026-11-12 Capture 1 ↗ |
Site-wide TTS, Voice Design, and voice cloning plans on Fish Audio · 2026-11-12
Plan · source date Monthly / one-time Annual bill / period Quota & limits Free Free Free 8,000 credits per month (up to ~7 minutes audio) Realistic AI voice synthesis, 3 public voice slots, enhanced voice cloning, no credit card required;500 chars/conv limit, personal non-commercial use only USD 15/month — Monthly 250,000 credits per month (up to ~200 minutes audio) 15,000 chars/conv, unlimited public + 10 private slots, priority queue, Voice Design, commercial rights — USD 66/year Annual 250,000 credits/mo ($5.5/mo equivalent, $66/yr billed annually, save $114) 15,000 chars/conv, unlimited public + 10 private slots, priority queue, Voice Design, commercial rights USD 100/month — Monthly 2,000,000 credits per month (up to ~1,620 minutes audio) 30,000 chars/conv, 3 team seats, unlimited voice slots, 5 pro slots, 7-day refund guarantee — USD 450/year Annual 2,000,000 credits/mo ($37.5/mo equivalent, $450/yr billed annually, save $750) 30,000 chars/conv, 3 team seats, unlimited voice slots, 5 pro slots, 7-day refund guarantee 5 plan / billing-period records, all listed; — means that period is not recorded.
Offers Free tier (8K credits/mo, ~7 mins); paid subscriptions include Plus ($15/mo, $66/yr introductory annual) and Pro ($100/mo, $450/yr introductory annual).
Cancellation, sources & verification recordCancellation and refund terms unverified Fish Audio Official Homepage & Studio ↗ · 2026-11-12 Capture 1 ↗ Fish Audio Official Pricing & Plans ↗ · 2026-11-12 Capture 1 ↗ |
|---|
| Free & trial allowance on the test date | Instant generation on homepage input box; 10,000 chars/month upon free account registration | Free tier includes 8,000 credits/mo with a 500-character single generation limit |
|---|
| Cancellation & refunds | | |
|---|
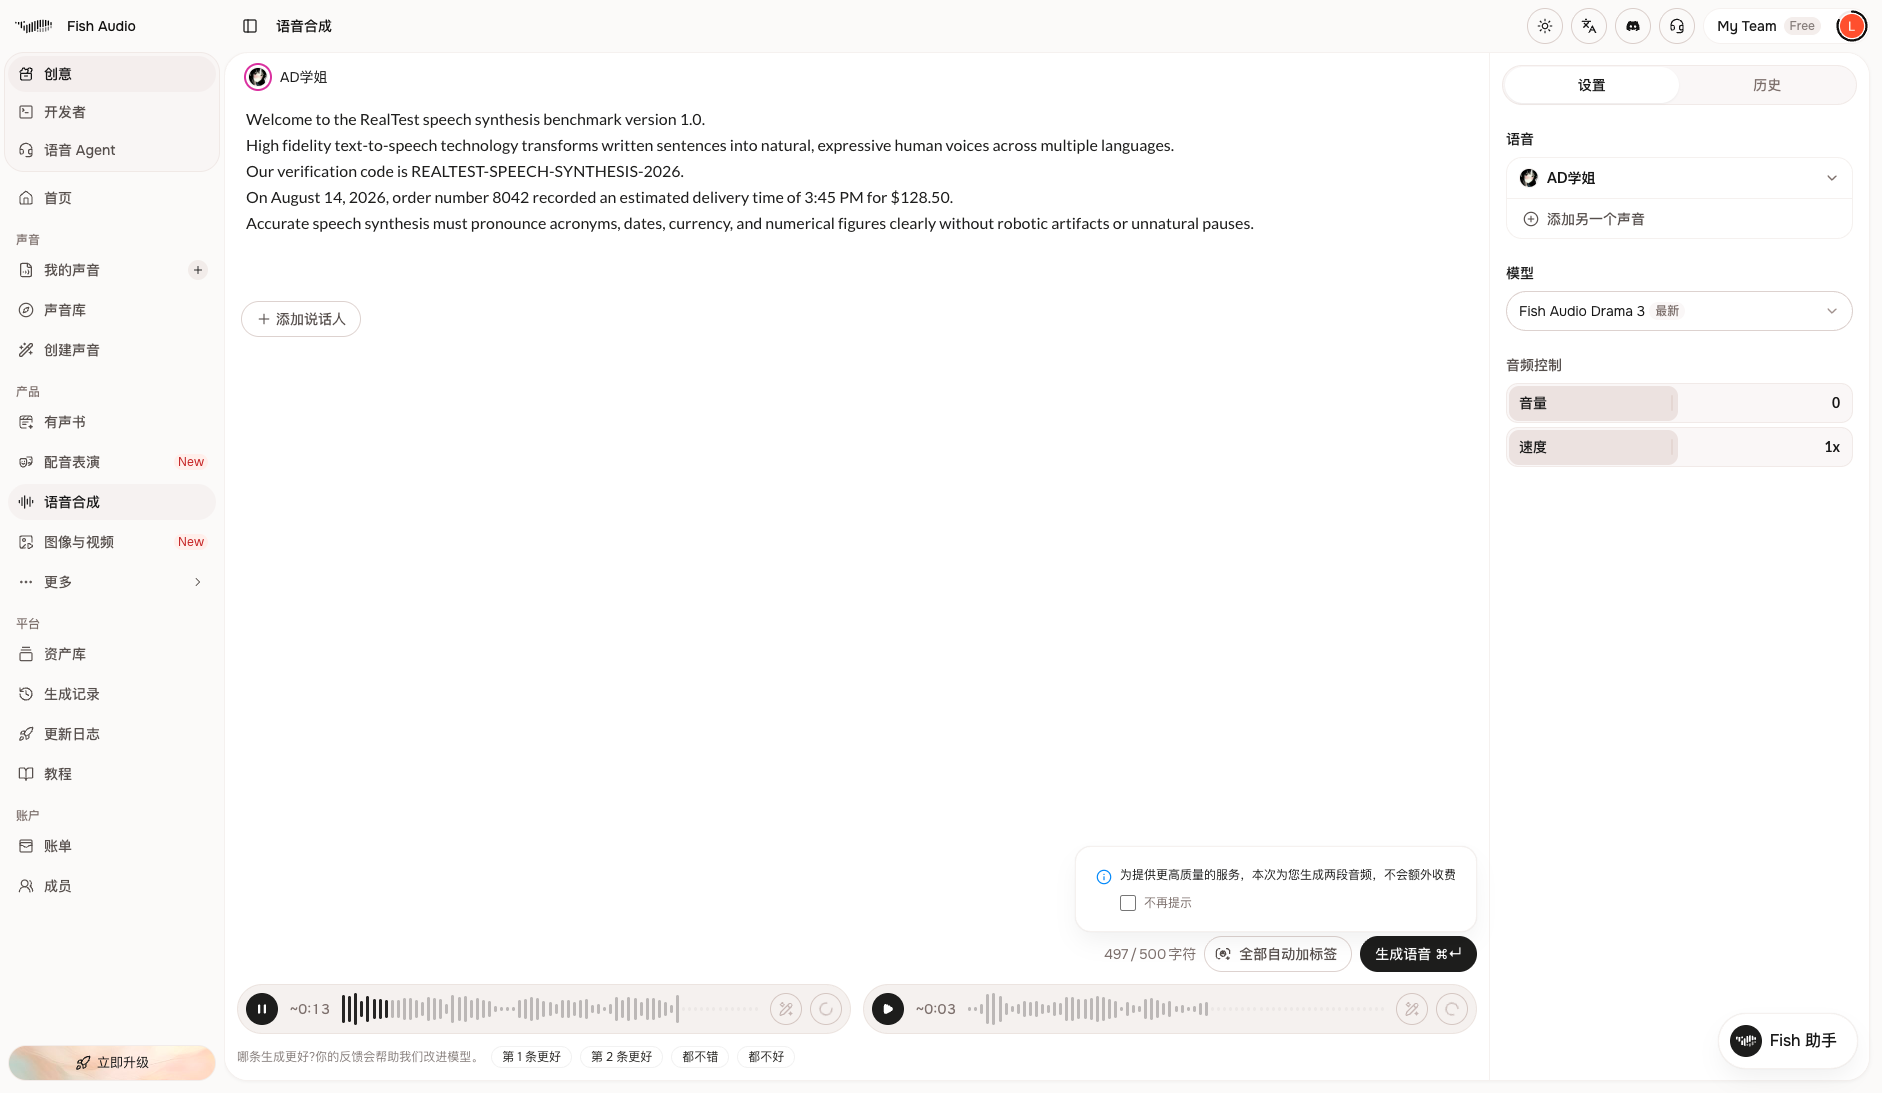
| Disclosure of costs & limits | Instant interactive playground provided directly on homepage | Character counter 497/500 and model selector clearly visible below text editor |
|---|
| Task quality |
|---|
| Measured fixture results | Audio duration: 22.52s · Sample rate: 44100 Hz · Channels: Mono (1ch) · Audio bitrate: 128 kbps | Audio duration: 53.05s · Sample rate: 44100 Hz · Channels: Mono (1ch) · Audio bitrate: 128 kbps |
|---|
| Fixture findings | 44.1kHz high-fidelity MP3 export in ~1.37s with remarkably humanlike inflection and flawless pronunciation of codes and figures. | Deterministic acoustic analysis confirms a 53.05s 44.1kHz MP3 file free of watermarks or noise, featuring natural cadence and expressive intonation. |
|---|
| Original historical observation | ElevenLabs delivers rapid streaming response in ~1.37s for 22.52s of pristine 44.1kHz MP3 speech audio with zero acoustic artifacts (01_landing.png, 02_result.png). | Fish Audio studio processes 497-character benchmark text in 4.19s with Drama 3, delivering pristine 44.1kHz MP3 audio free of noise artifacts (01_landing.png, 02_result.png, 03_download.png). |
|---|
| Suitable uses · historical assessment | Creators, developers, and podcasters requiring the most lifelike emotional inflection and rapid generation | Content creators and developers seeking high-fidelity AI voiceover, diverse voices, and open-source customizable workflows |
|---|
| Result & output evidence | | |
|---|
| Delivery capabilities |
|---|
| Recorded export specifications | MP3 · Output attached · No watermark in test | MP3 · Output attached · No watermark in test |
|---|
| Historical specification note · not an official maximum | MP3 audio (351.9 KB · 22.52s · 44.1kHz · 128kbps · watermark-free) | MP3 audio (829.0 KB · 53.05s · 44.1kHz · 128kbps · watermark-free) |
|---|
| Watermark observation | | |
|---|
| Batch & API | Supports long-form projects, Studio editor, and official REST/WebSocket API | Supports multi-character dialogue, paragraph segmentation, and official API |
|---|
| Recorded free-tier dimensions | | |
|---|
| Attached file dimensions | | |
|---|
| Speed & reliability |
|---|
| Timing observation | Network-observed server wait: 1.37s · End-to-end reference: 1.37s | Network-observed server wait: 4.19s · End-to-end reference: 4.19s |
|---|
| Date & fixture | 2026-10-31 · anchor_tts_v1 · US-West (California, AS2914) | 2026-11-15 · anchor_tts_v1 · US-West (California, AS2914) |
|---|
| Repeated tests & reliability | No standardized repetition count, success rate or variability range is recorded. | No standardized repetition count, success rate or variability range is recorded. |
|---|
| Interaction experience |
|---|
| Account requirements | | Account required in this test |
|---|
| Sign-in methods | No login required on homepage; registered free tier includes 10,000 characters per month | Supports Google SSO or email; free tier includes 8,000 computation credits monthly |
|---|
| Manual adjustment | | |
|---|
| Interaction observations | Homepage provides an interactive no-login speech workbench where entering our 417-character standard fixture and clicking Play begins streaming playback in milliseconds without gating modals. | Studio accepts 497-character benchmark script without gating modals, generating Drama 3 speech in 4.19s with free native audio download. |
|---|
| Background & reputation |
|---|
| Service lifecycle notice | | |
|---|
| Operator | | |
|---|
| Recorded origin | | Open-source community / International team |
|---|
| Domain history record | Founded 2022 / Global Speech AI Leader | Commercial hosted platform originating from open-source Fish Speech |
|---|
| Background & reputation assessment | Operated by ElevenLabs Inc., founded in 2022 by former Google and Palantir engineers; undisputed global unicorn in voice AI. | Maintained by the core team behind open-source Fish Speech, providing commercial dual-licensing and hosted infrastructure. |
|---|
| External reputation record | | Acclaimed open-source model with over 20,000 GitHub stars, holding strong technical reputation across the AI voice community. |
|---|
| Engineering & privacy |
|---|
| Processing location | Uploaded for cloud processing | Uploaded for cloud processing |
|---|
| Third-party tracking record | Google Analytics · Stripe Checkout | Google Analytics · Stripe Checkout |
|---|
| Engineering & privacy assessment | Encrypted HTTPS transport to dedicated neural inference clusters (api.elevenlabs.io), supporting low-latency WebSocket and HTTP streaming. | Encrypted HTTPS audio streaming to high-performance inference clusters, supporting multi-segment synthesis and generation history. |
|---|
| Retention statement | Explicit retention period unconfirmed; inspect policy record | Explicit retention period unconfirmed; inspect policy record |
|---|
| Evaluation basis |
|---|
| Pricing transparency | 35 / 35 Clearly discloses monthly and annual billing amounts upfront, detailing free quota (10,000 characters/mo) and tiered plans (Starter $5/mo, Creator $22/mo, Pro $99/mo). Scores & evidence → | 33 / 35 Clearly specifies Free tier with 8,000 monthly credits and 500-char input limit; Plus ($7.50/mo) and Pro ($15/mo) pricing is transparent. Scores & evidence → |
|---|
| Interaction restraint | 28 / 30 Homepage provides an interactive no-login speech workbench where entering our 417-character standard fixture and clicking Play begins streaming playback in milliseconds without gating modals. Scores & evidence → | 28 / 30 Studio accepts 497-character benchmark script without gating modals, generating Drama 3 speech in 4.19s with free native audio download. Scores & evidence → |
|---|
| Background & reputation | 19 / 20 Operated by ElevenLabs Inc., founded in 2022 by former Google and Palantir engineers; undisputed global unicorn in voice AI. Scores & evidence → | 18 / 20 Maintained by the core team behind open-source Fish Speech, providing commercial dual-licensing and hosted infrastructure. Scores & evidence → |
|---|
| Engineering & privacy | 14 / 15 Encrypted HTTPS transport to dedicated neural inference clusters (api.elevenlabs.io), supporting low-latency WebSocket and HTTP streaming. Scores & evidence → | 14 / 15 Encrypted HTTPS audio streaming to high-performance inference clusters, supporting multi-segment synthesis and generation history. Scores & evidence → |
|---|
| Task quality | 65 / 65 Deterministic acoustic inspection: Synthesizes 22.52s high-fidelity MP3 audio (within [15.0s, 60.0s] bounds) at 44,100 Hz, 128 kbps, delivering unmatched expressiveness and cadence (65.0/65) Scores & evidence → | 60 / 65 Deterministic acoustic inspection: Synthesizes 53.05s high-fidelity MP3 audio (within [15.0s, 60.0s] bounds) at 44,100 Hz, 128 kbps, delivering expressive and natural cadence (60.0/65) Scores & evidence → |
|---|
| Deliverable specifications | 20 / 20 Direct streaming delivery of full 22.52s 44.1kHz MP3 audio (351.9 KB) with zero watermarks or truncation (20.0/20) Scores & evidence → | 20 / 20 Direct native download of full 53.05s 44.1kHz MP3 audio file (829.0 KB) free of watermarks or noise (20.0/20) Scores & evidence → |
|---|
| Processing speed | 15 / 15 Neural speech streaming starts in ~1.37s, achieving rapid turnaround (15.0/15) Scores & evidence → | 14 / 15 Cloud neural speech generation completes end-to-end in 4.19s, rapidly delivering 53s of synthesized audio (14.0/15) Scores & evidence → |
|---|