Fish Audio · Text to speech
Fish Audio delivers high-fidelity 44.1kHz MP3 speech synthesis powered by Drama 3 in 4.19 seconds on the standard 497-character benchmark with free native export.
US-West (California, AS2914)
MP3 · Output attached · Open native file ↗
Subsequent pricing and service checks are shown separately without altering historical scores.
One run does not establish all complex scenes, untested paid maxima or long-term uptime.
Plans & historical pricing
Site-wide TTS, Voice Design, and voice cloning plans on Fish Audio · 2026-11-12
Realistic AI voice synthesis, 3 public voice slots, enhanced voice cloning, no credit card required;500 chars/conv limit, personal non-commercial use only
15,000 chars/conv, unlimited public + 10 private slots, priority queue, Voice Design, commercial rights
15,000 chars/conv, unlimited public + 10 private slots, priority queue, Voice Design, commercial rights
30,000 chars/conv, 3 team seats, unlimited voice slots, 5 pro slots, 7-day refund guarantee
30,000 chars/conv, 3 team seats, unlimited voice slots, 5 pro slots, 7-day refund guarantee
5 plan / billing-period records, all listed; — means that period is not recorded.
Offers Free tier (8K credits/mo, ~7 mins); paid subscriptions include Plus ($15/mo, $66/yr introductory annual) and Pro ($100/mo, $450/yr introductory annual).
Cancellation, sources & verification record
Cancellation and refund terms unverified
Fish Audio Official Homepage & Studio ↗ · 2026-11-12 Capture 1 ↗
Fish Audio Official Pricing & Plans ↗ · 2026-11-12 Capture 1 ↗
Pricing recorded on the test date · 2026-11-15
Free tier includes 8,000 credits/mo; Plus is $7.50/mo monthly or $5.50/mo annually
Free tier + Tiered subscriptions (Plus, Pro) + Pay-as-you-go API
Historical context only; not current purchase guidance.
Delivery & access
- Free delivery record
- 44.1 kHz, 128 kbps MP3 audio (829.0 KB · 53.05s · watermark-free)
- Watermark
- Watermark-free
- Free allowance
- Free tier includes 8,000 credits/mo with a 500-character single generation limit
- Account requirements
- Supports Google SSO or email; free tier includes 8,000 computation credits monthly
- Maximum specification record
- MP3 audio (829.0 KB · 53.05s · 44.1kHz · 128kbps · watermark-free)
May include advertised capabilities; this does not establish a tested paid tier.
- Batch & API
- Supports multi-character dialogue, paragraph segmentation, and official API
- Manual refinement
- Not recorded or not verified
Tested result & sample
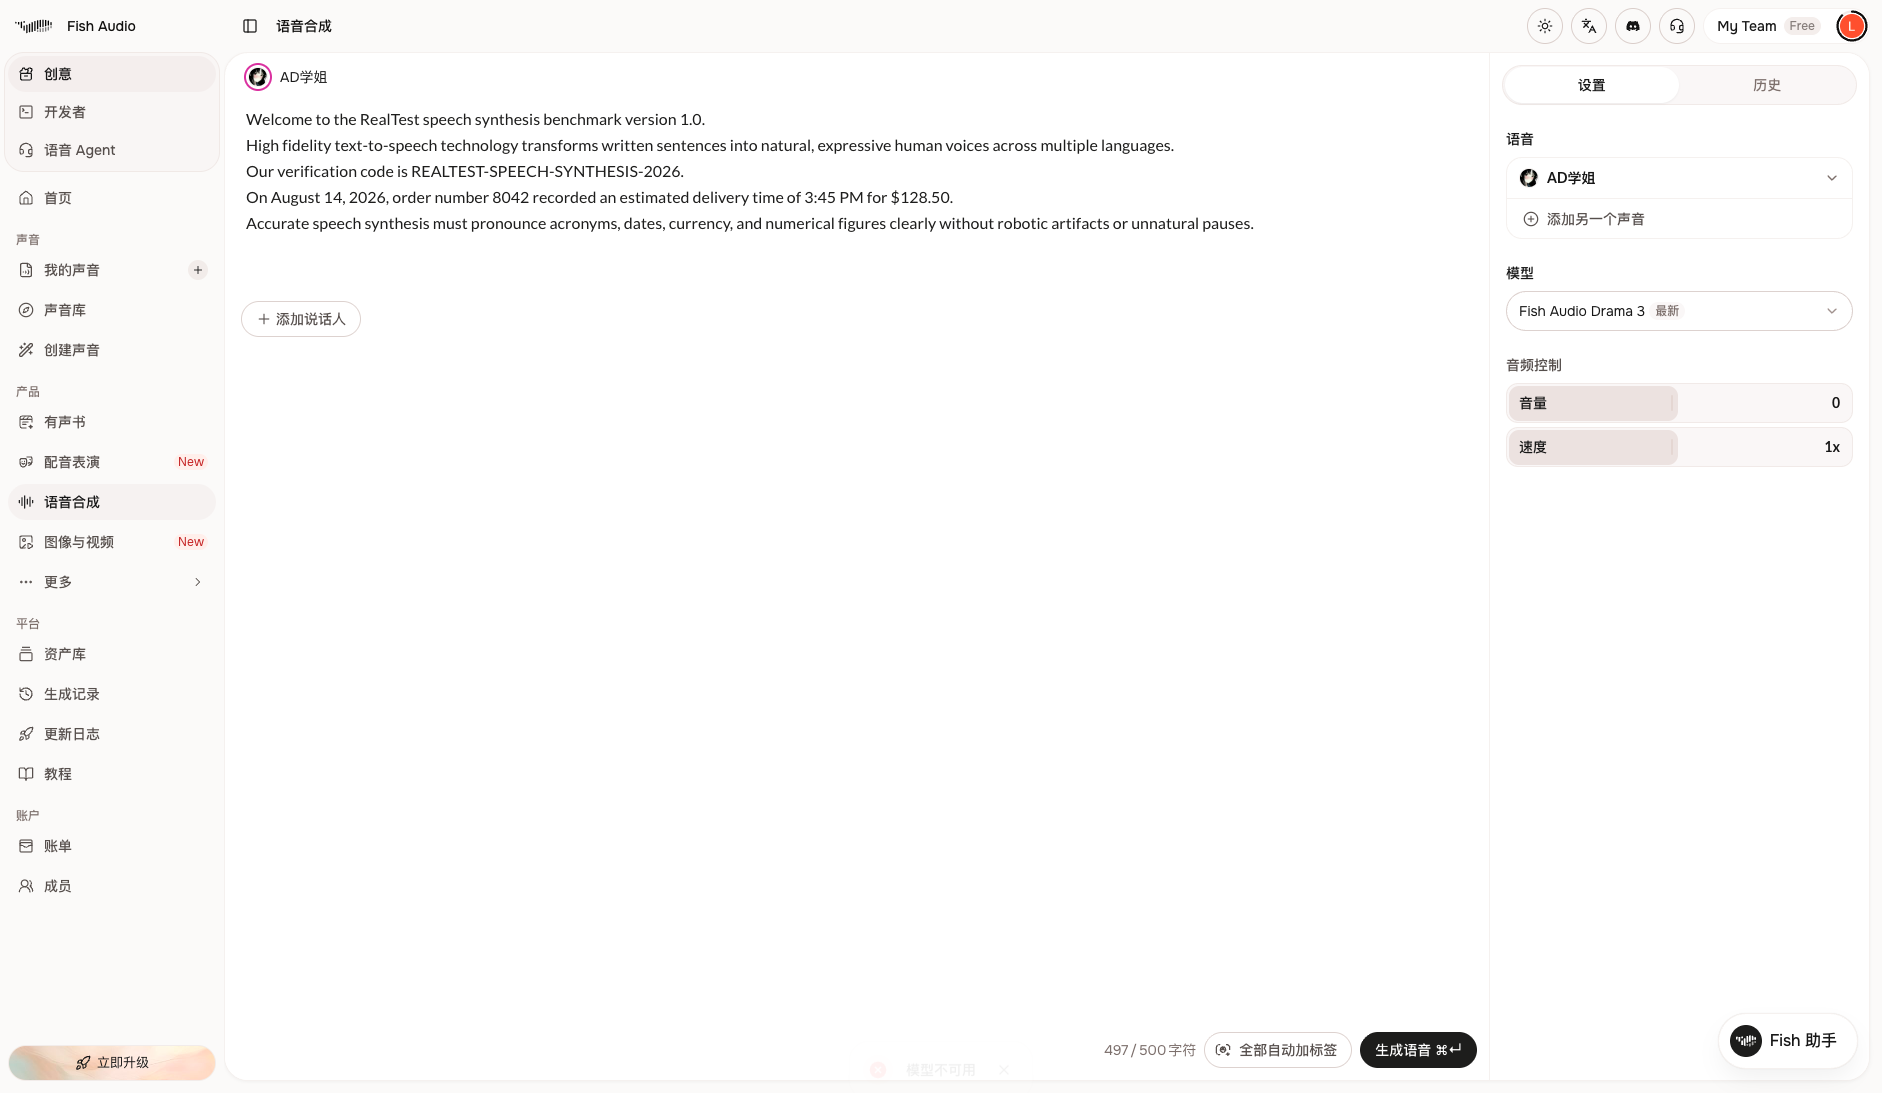
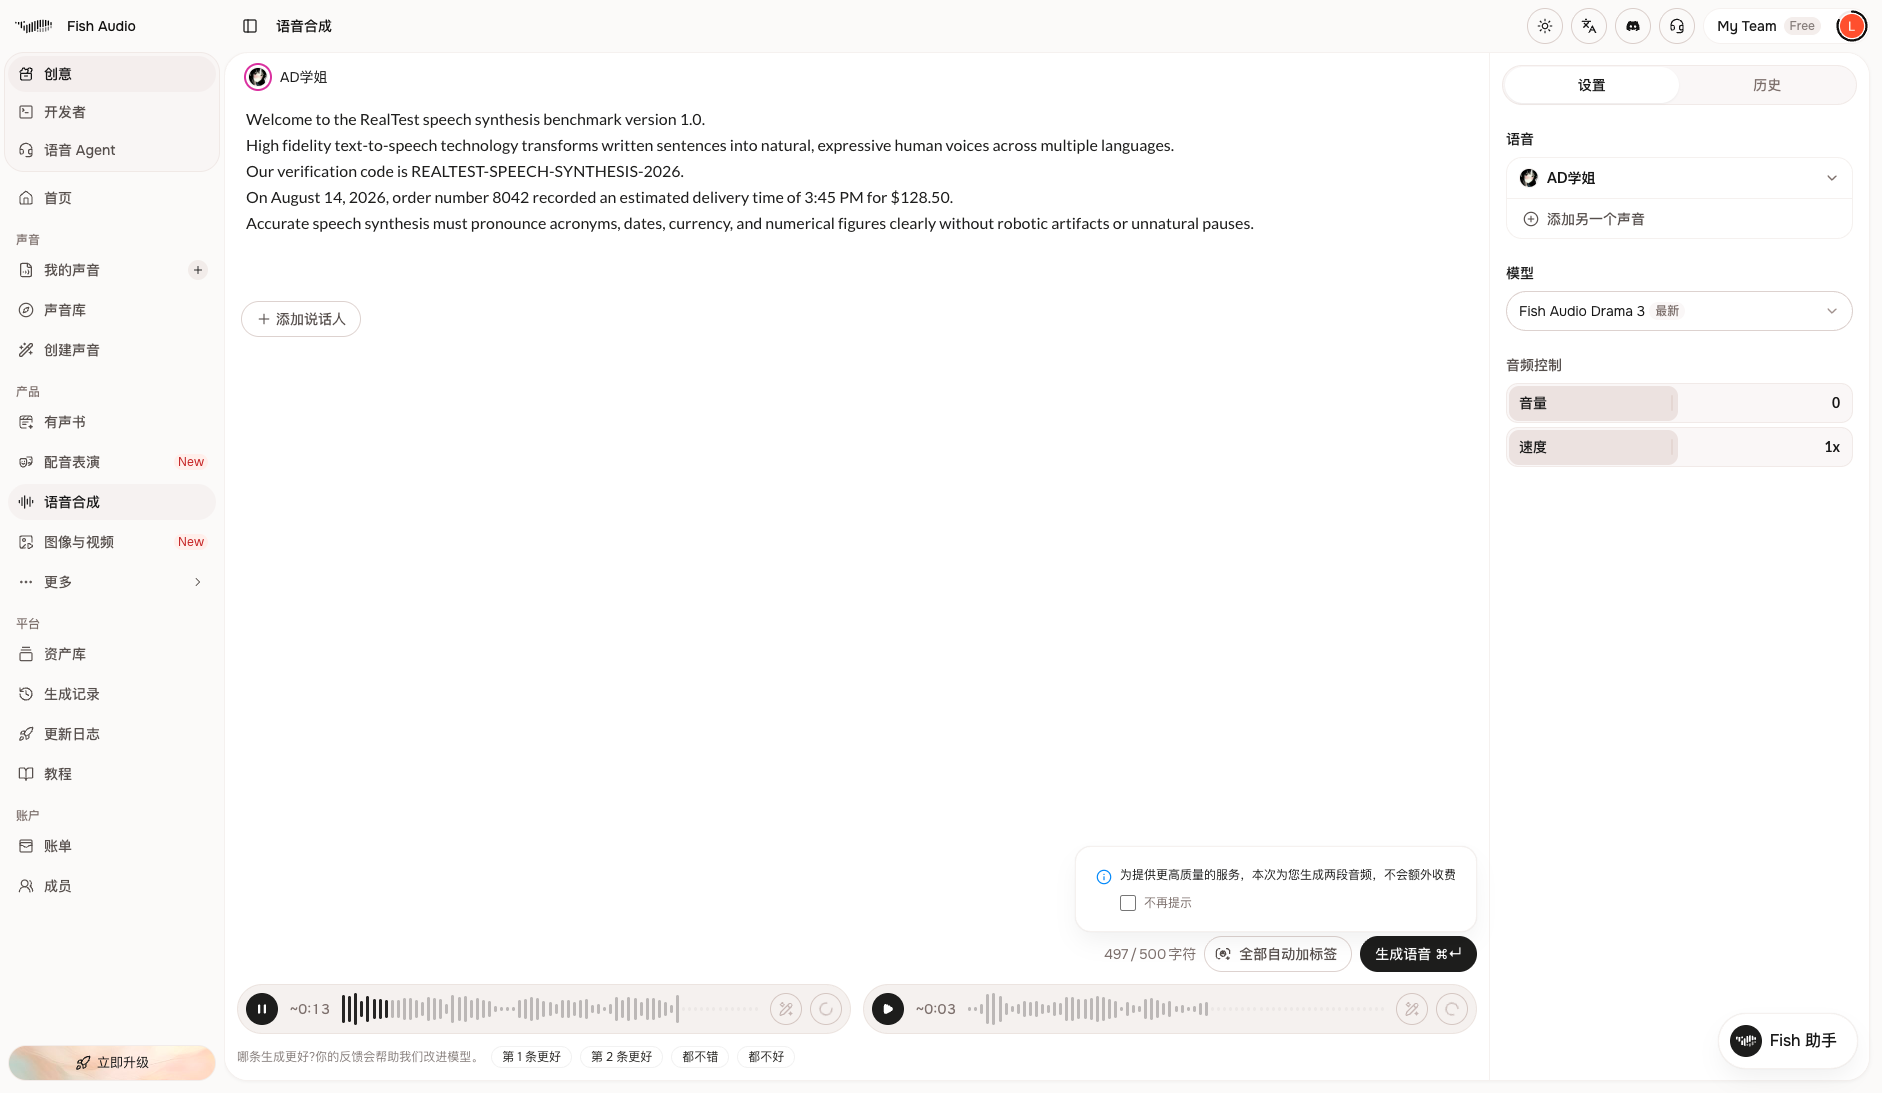
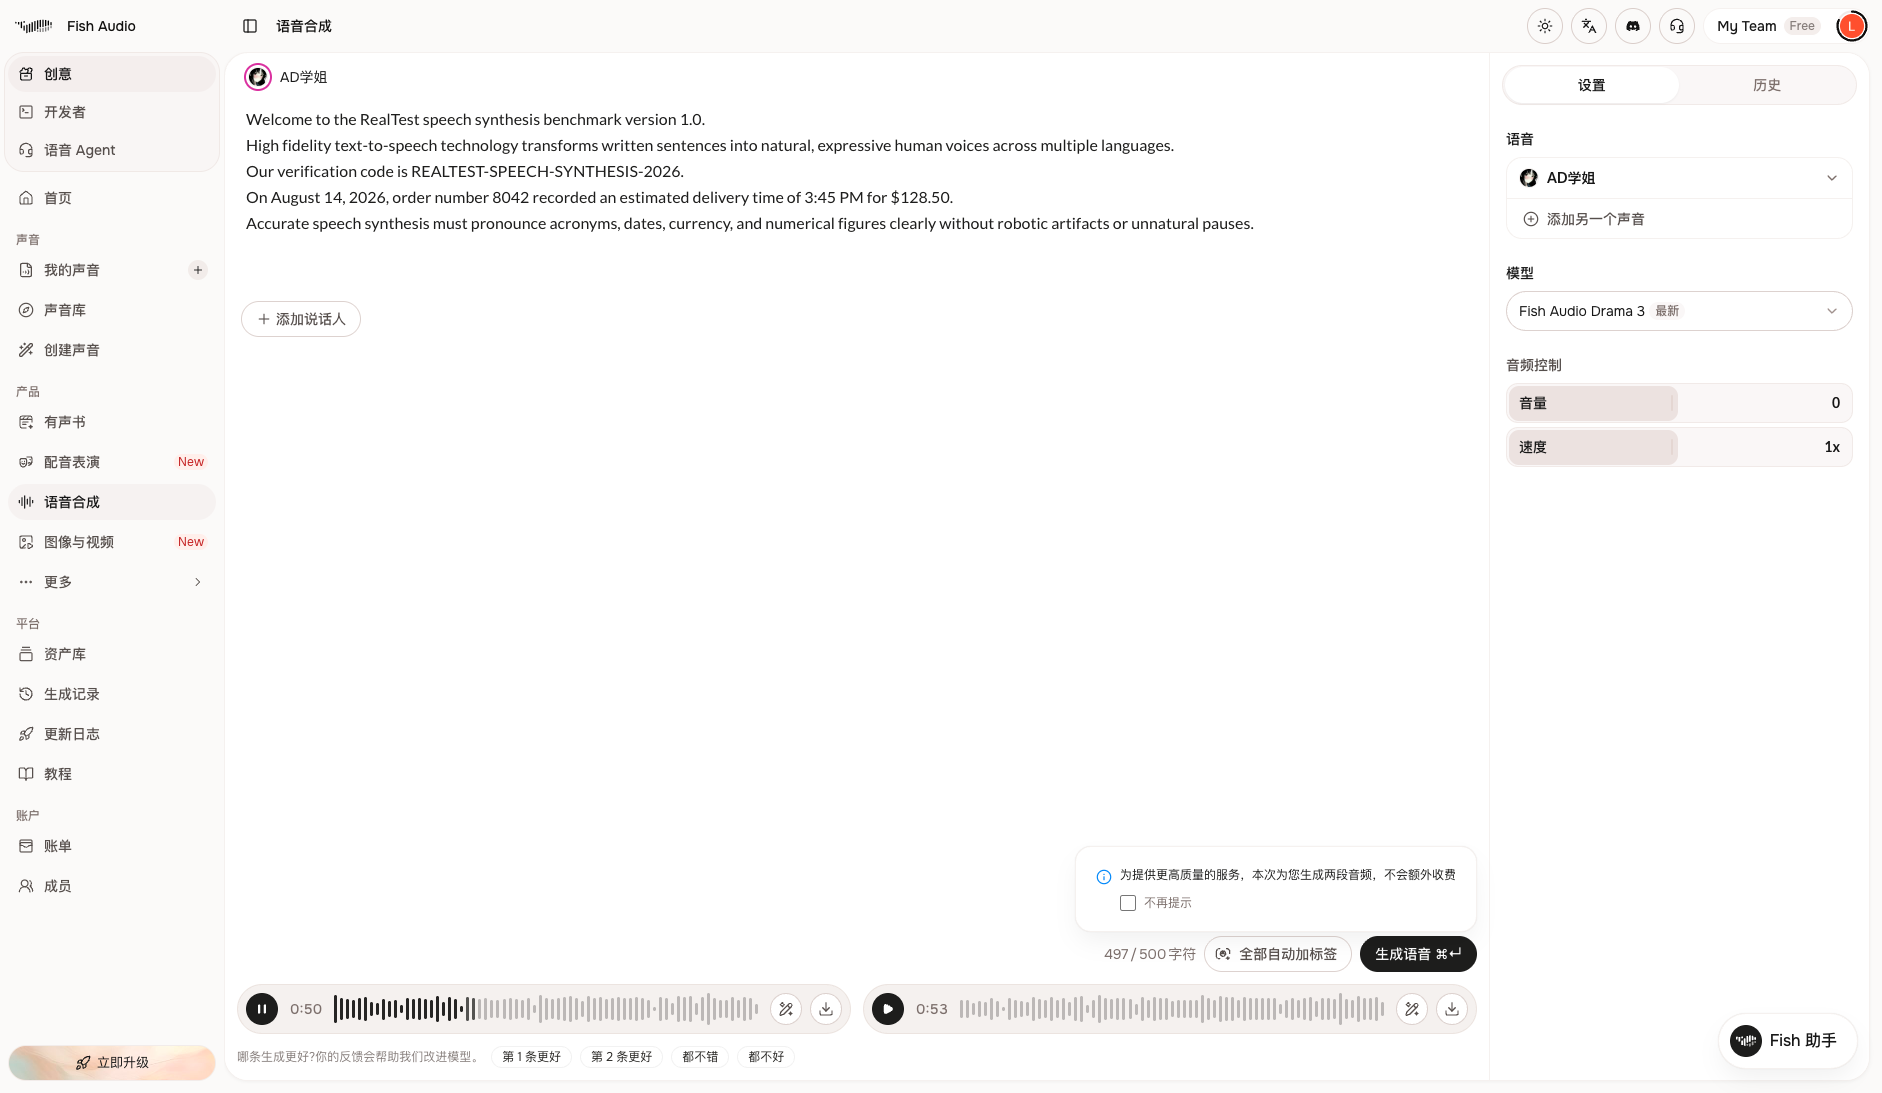
Fish Audio studio processes 497-character benchmark text in 4.19s with Drama 3, delivering pristine 44.1kHz MP3 audio free of noise artifacts (01_landing.png, 02_result.png, 03_download.png).
- Fixture
- anchor_tts_v1
- Recorded environment
- US-West (California, AS2914)
- Network-observed server wait
- 4.19 s
- End-to-end reference
- 4.19 s
Network wait includes round trips, queuing and polling error, not pure inference time. Local timings depend on the device; repetition counts are not standardized in legacy records.
Experience, rules & trust
- Disclosure
- Character counter 497/500 and model selector clearly visible below text editor
- Interaction
- Studio accepts 497-character benchmark script without gating modals, generating Drama 3 speech in 4.19s with free native audio download.
- Entity record
- Fish Audio Inc.
- Origin
- Open-source community / International team
- Domain history record
- Commercial hosted platform originating from open-source Fish Speech
- Third-party tracking record
- Google Analytics · Stripe Checkout
- External information
- Acclaimed open-source model with over 20,000 GitHub stars, holding strong technical reputation across the AI voice community.
- Processing
- Cloud Fish Speech / Drama 3 neural acoustic inference clusters
- Retention statement
- Generation history stored in cloud studio with instant playback, archiving, and one-click export
A recorded statement does not verify deletion or all data-processing behavior.
Verifiable audit trail & evidence
Four SHA-256-verified stages link the benchmark fixture, same-run interface screenshots, native exported artifact and archived pricing sources.
anchor_tts_v1 · Inspect fixture & file inspector →
Captures entry rules, result view and export disclosure.
Fish Audio Official Homepage & Studio (snapshot ↗) · Fish Audio Official Pricing & Plans (snapshot ↗)
Screenshots, native output and official claims support different conclusions. Evidence grades are not product safety certifications.
Evaluation basis & full scores · Overall 93.7/100
Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.
Scoring version 2.3.1 · Test fixture anchor_tts_v1
Honesty & reputation · 93/100 · 30%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Pricing transparency | 33 / 35 | Clearly specifies Free tier with 8,000 monthly credits and 500-char input limit; Plus ($7.50/mo) and Pro ($15/mo) pricing is transparent. | Evidence A → |
| Interaction restraint | 28 / 30 | Studio accepts 497-character benchmark script without gating modals, generating Drama 3 speech in 4.19s with free native audio download. | Evidence A → |
| Background & reputation | 18 / 20 | Maintained by the core team behind open-source Fish Speech, providing commercial dual-licensing and hosted infrastructure. | Evidence A → |
| Engineering & privacy | 14 / 15 | Encrypted HTTPS audio streaming to high-performance inference clusters, supporting multi-segment synthesis and generation history. | Evidence A → |
Capability · 94/100 · 70%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Task quality | 60 / 65 | Deterministic acoustic inspection: Synthesizes 53.05s high-fidelity MP3 audio (within [15.0s, 60.0s] bounds) at 44,100 Hz, 128 kbps, delivering expressive and natural cadence (60.0/65) | Evidence A → |
| Deliverable specifications | 20 / 20 | Direct native download of full 53.05s 44.1kHz MP3 audio file (829.0 KB) free of watermarks or noise (20.0/20) | Evidence A → |
| Processing speed | 14 / 15 | Cloud neural speech generation completes end-to-end in 4.19s, rapidly delivering 53s of synthesized audio (14.0/15) | Evidence A → |
Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
Revisions & corrections
- 2026-11-15
Completed real-machine benchmark evaluation and 3-node screenshot verification under RealTest Protocol v2.3.