Choose by task

Scanned PDF OCR tools compared

Read the assessment, then compare prices, capabilities and constraints.

This topic covers 15 published scanned pdf ocr assessments: 13 support guest export without login or watermarks, 15 deliver watermark-free files, and 0 offer sourced commercial-use plans, with 1 verified for local browser processing. All scores are bound to fixed benchmark fixtures and dated native exports.

Quick scenarios:
More requirements & budget

15 published assessments

Plus 6 tested tools withheld from ranking due to free-tier paywalls (B1) or backend errors (B2) View blocked records ↓

Test scope & pricing dates
Pricing shows its own verification date and scope; tests retain their original dates. Vendor claims and test results are separate; paid specifications may be untested. About the scope →

Scan the candidates

Select 2–4 tools to compare. Pricing links jump to every recorded plan; scores cover seven aspects and assessments highlight key trade-offs; complete facts follow below.

ToolOverall score & assessmentTested export & sampleKnown price & all plans

98/100 100% free and unlimited without login, converting our 2-page raster scan into a 567.5 KB searchable PDF in 6.24s with 100% recall across all 4 headings and 12 confusable invoice table cells.

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Ad-supported free · Free

The page states free access without limits; numeric page or file-size limits are not stated.

1 plan / period records ↓

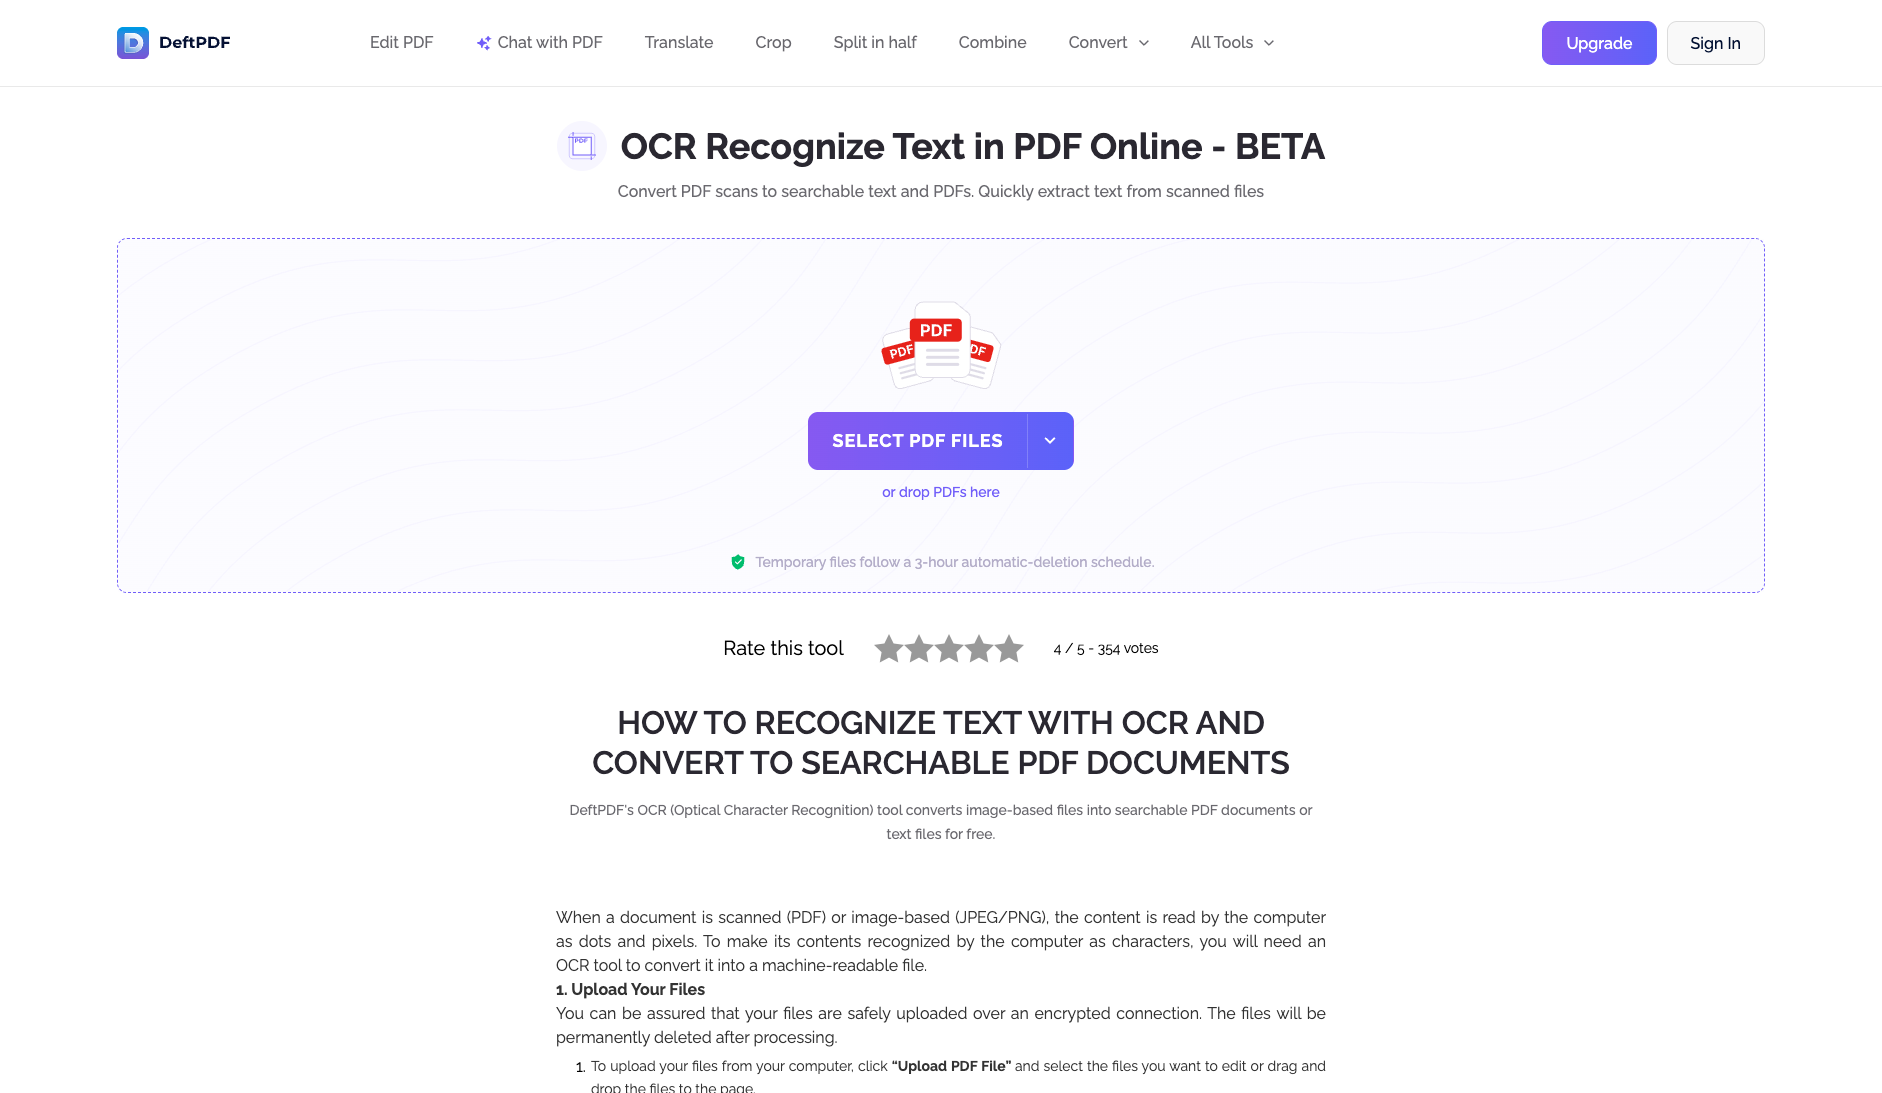
97/100 DeftPDF provides account-free, character-precise online OCR for scanned PDFs. In our 2-page pure scan benchmark, it completed processing in 5.3 seconds to deliver a 666.3 KB Searchable PDF, injecting 241 underlying text operators with 100.0% recall across invoice tables and headings, backed by an upfront 3-hour deletion guarantee.

Guest flow · 2026-10-31

PDF · Output attached · Native file ↗

Free Plan · Free

Free per-tool limits across 40+ tools; merge up to 25 files, 20-50MB task limit, 3-hour scheduled deletion

3 plan / period records ↓

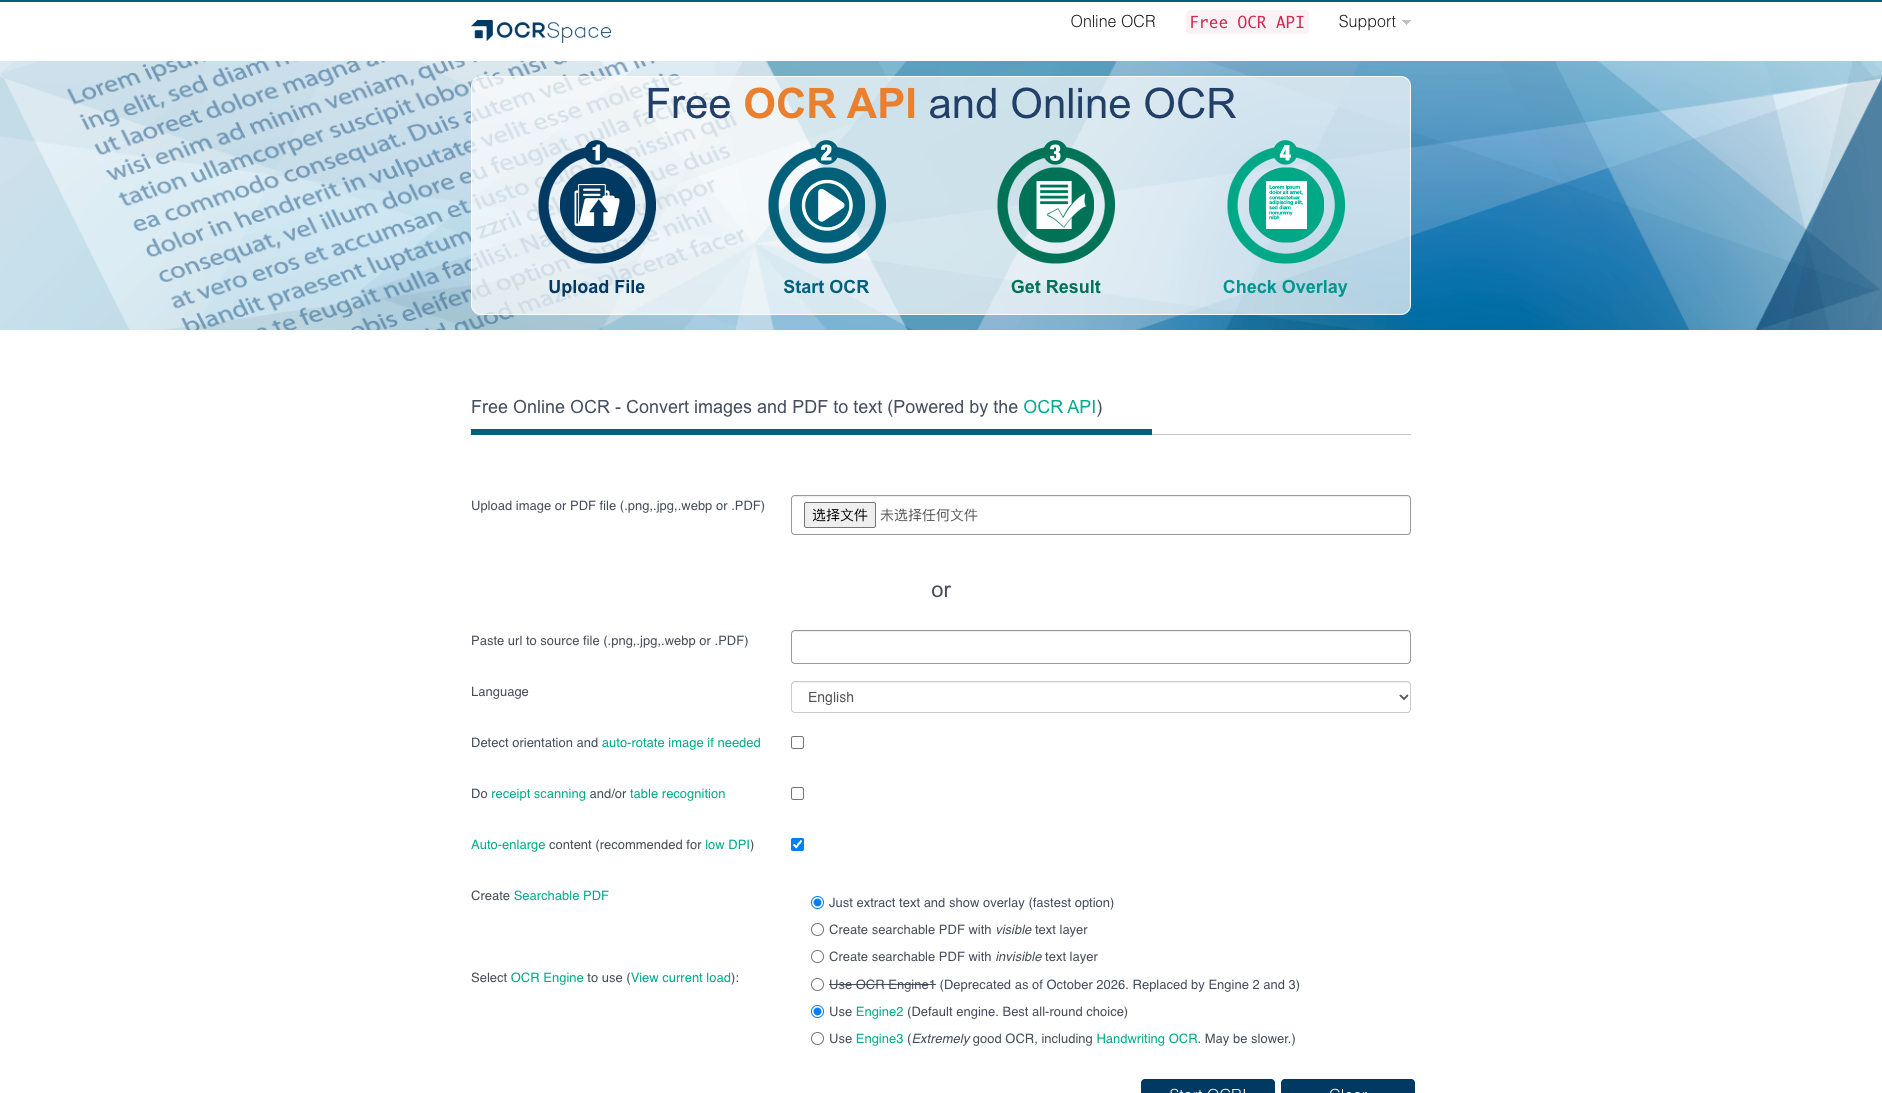
97/100 OCR.space Scanned PDF OCR delivered outstanding benchmark results on the 2-page 150 DPI raster scan anchor, achieving a perfect 100.0% recall across headings and financial table cells while fully preserving page 2, exporting a 667.1 KB watermark-free searchable PDF in 9.01s server processing, earning an overall score of 97 (Capability 96 / Honesty 98).

Guest flow · 2026-11-02

PDF · Output attached · Native file ↗

Free Plan (Web & API) · Free

Web tool 5 MB file cap; API provides 25,000 calls/mo (1 MB file limit, 3 pages per PDF)

3 plan / period records ↓

95/100 Completes scanned PDF OCR without login in just 3.45s and auto-downloads an unwatermarked 2-page searchable PDF with 100% accuracy across all 12 confusable invoice table cells, clipping only the trailing word of the Page 2 white-on-navy banner (94.4% overall text recall).

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Basic · Free

Basic tools; limited documents, batching and file size, without numeric limits.

5 plan / period records ↓

95/100 Offers 3 free OCR tasks per hour (up to 10 pages) without login, converting our 2-page raster scan into a 651.9 KB searchable PDF in 7.50s with 100% recall across all 4 headings and 12 confusable table cells.

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Free · Free

No account required; documents up to 50 pages or 50 MB and up to 3 tasks per hour; files automatically deleted after 2 hours.

4 plan / period records ↓

94/100 Powered by Orpalis (GdPicture) enterprise OCR, converts our 2-page raster scan into a 661.1 KB searchable PDF in 3.73s without login at 100% text and table accuracy, though capped at 2 free actions with free-tier AI training terms.

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

AvePDF Free · Free

Maximum 2 processing actions per 6 hours; max file size 128 MB, up to 10 files per processing across 50+ document tools

2 plan / period records ↓

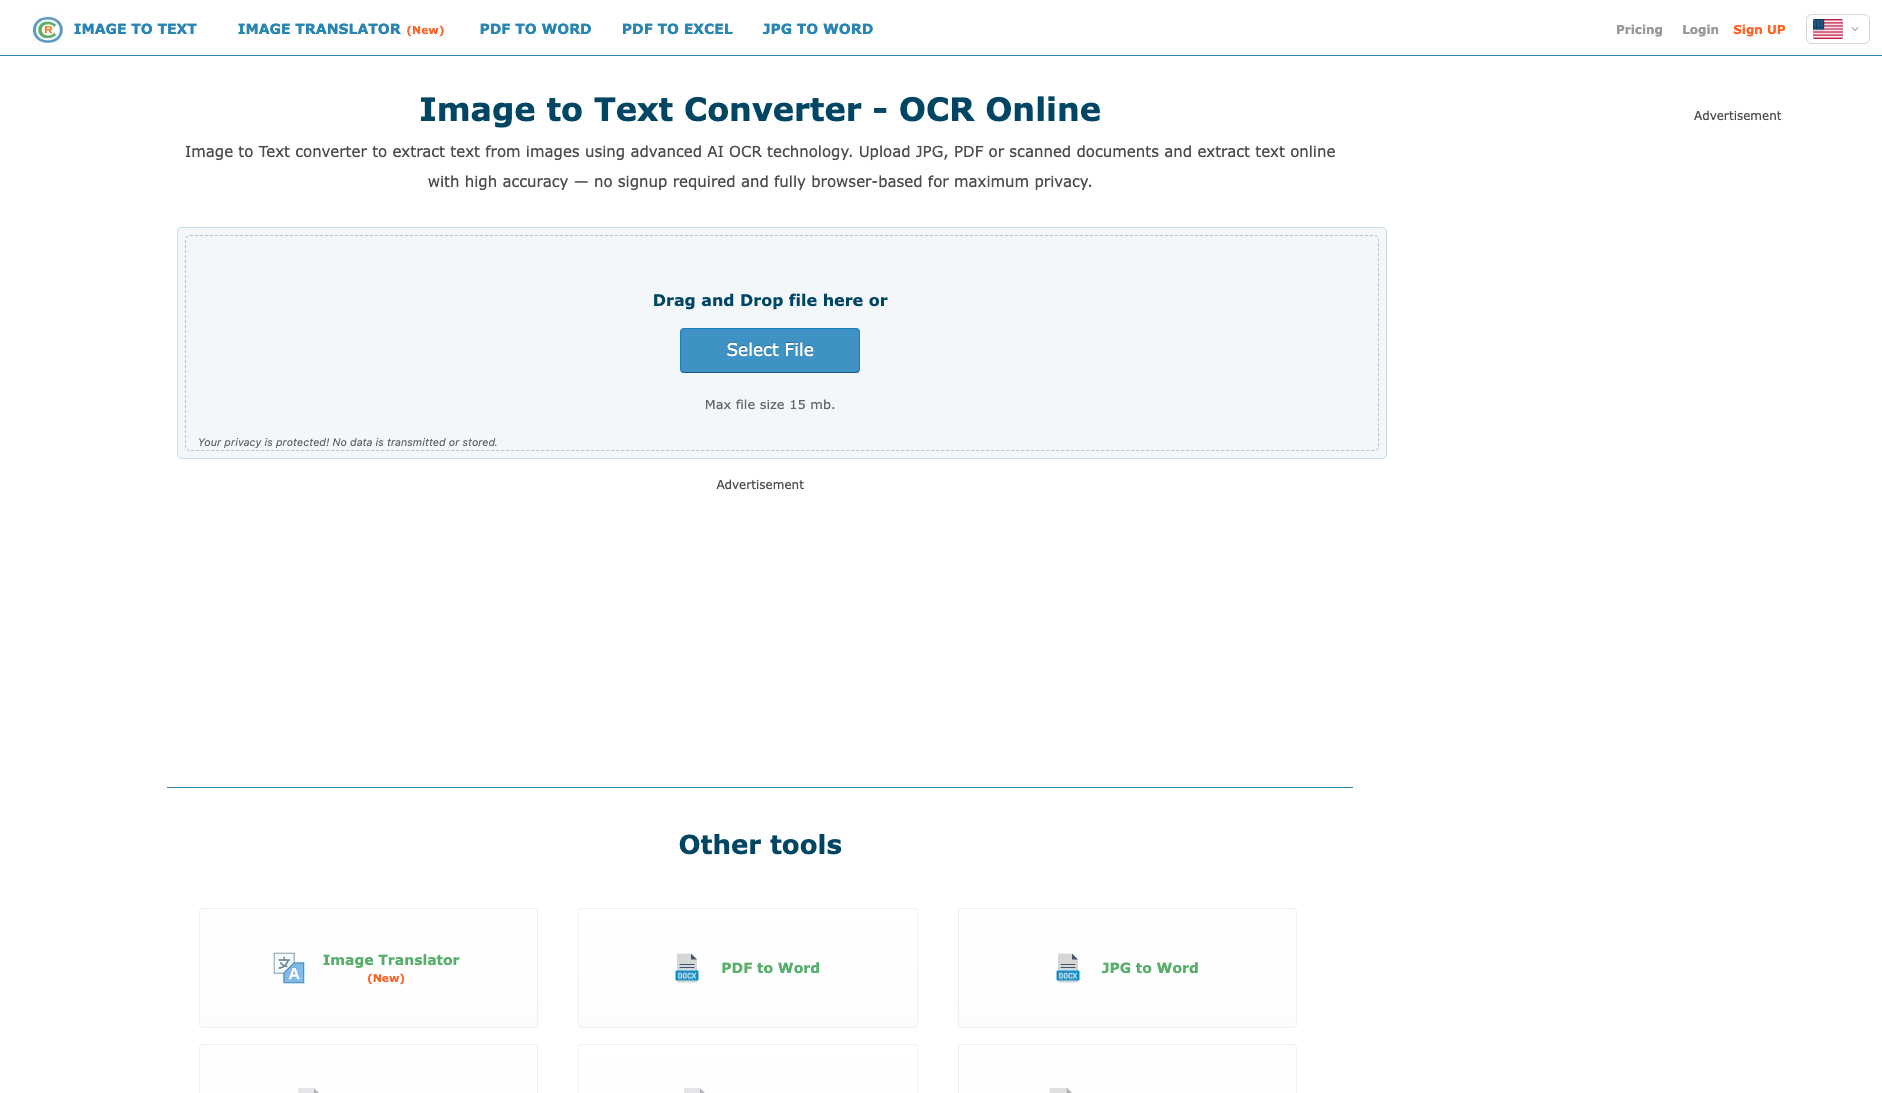
92/100 Classic guest-usable online OCR tool converting full 2-page scanned PDF to Word (.docx) with 100% text retention and 100% table accuracy in 19.97s server wait.

Guest flow · 2026-11-02

DOCX · Output attached · Native file ↗

Free Guest Mode · Free

Free OCR without login, max file size 15 MB, guest rate limit approx 15 pages/hour

4 plan / period records ↓

91/100 Converts our 2-page raster scan into a 2-page searchable PDF without login with 100% recall across all 4 headings and 12 confusable invoice table cells, though re-rendering inflates file size to 3,037.5 KB and takes 29.38s end-to-end (10.32s server OCR).

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Free · Free

Up to 50 MB without registration; limited processing, no batching; exact count not listed.

8 plan / period records ↓

90/100 Powered by Apryse (PDFTron) cloud OCR with 1 free daily task without login, exporting a 687.6 KB 2-page searchable PDF in 5.00s; achieves 100% accuracy on body text and all 12 confusable invoice table cells, though binarization skips the two white-on-navy top banners (88.9% overall text recall).

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Web free allowance · Free

1 action/day with limited access to web tools.

9 plan / period records ↓

89/100 Unlocks free PDF OCR without login, completing server OCR in 10.41s to export a 689.4 KB 2-page searchable PDF via its PDFTron OCR engine; achieves 100% accuracy across all 12 confusable invoice table cells and body text while skipping the two white-on-navy top header banners (88.9% overall text recall).

Guest flow · 2026-10-25

PDF · Output attached · Native file ↗

Free · Free

Daily downloads and file size are limited, without exact figures; PDF-to-Word OCR is a Pro feature.

7 plan / period records ↓

87/100 Offers 1 free OCR task per hour without login, recovering 100% of all 4 headings, 12 confusable invoice table cells, and the Page 2 verification token in 8.99s, but exports only a plain-text `.txt` file (1.6 KB) rather than a layout-preserving searchable `.pdf`.

Guest flow · 2026-10-25

TXT · Output attached · Native file ↗

Free · Free

No account; page, hourly and file-size limits; no batching. Numeric limits are not listed.

4 plan / period records ↓

82/100 Requires a free account login to run basic OCR exporting a 2-page `.docx` (11.3 MB, 26.61s server wait) with 100% recall across all 4 headings and 12 confusable invoice table cells, while Searchable `.pdf` export is locked behind VIP.

Signed-in flow; paid tier not standardized · 2026-10-25

DOCX · Output attached · Native file ↗

Free Plan · Free

Web only; max file size 10 MB, 1-year cloud storage for up to 5 files; downloading converted DOCX requires signing in to a free account

4 plan / period records ↓

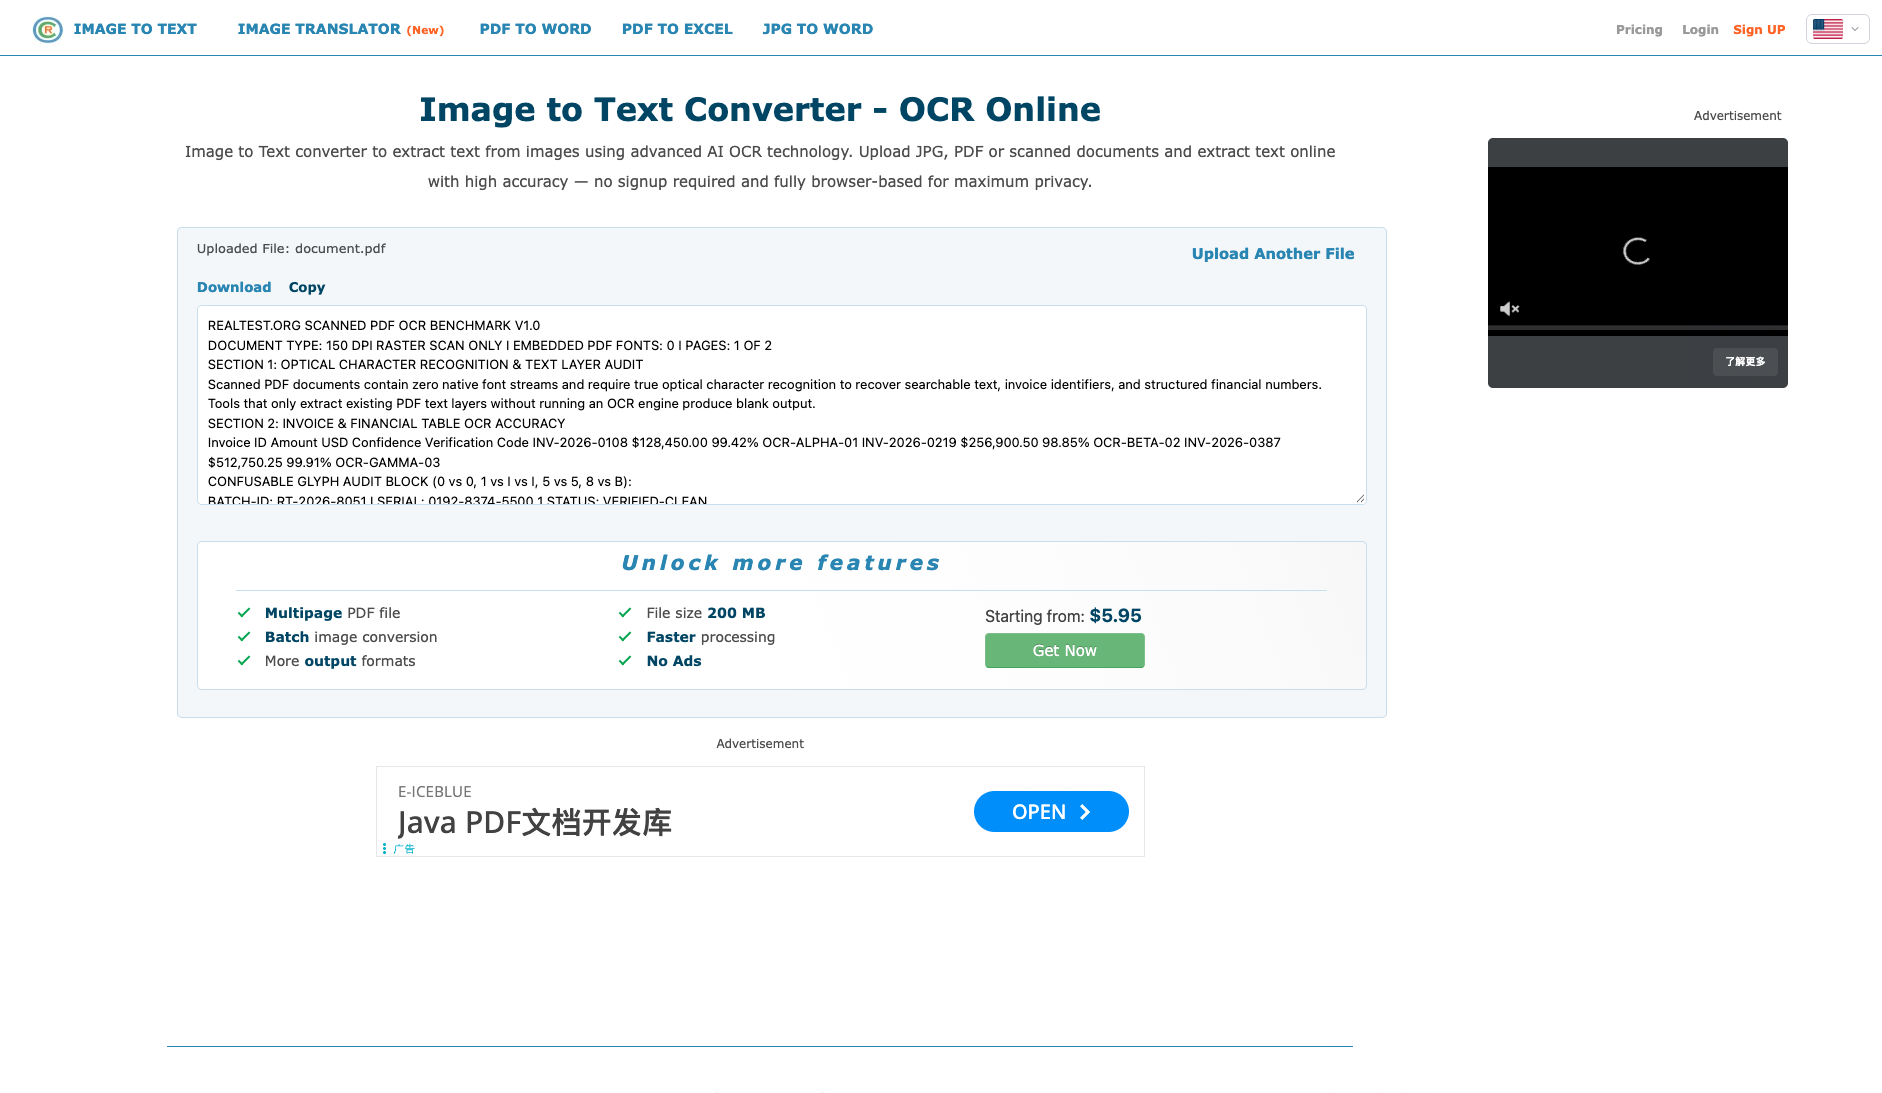
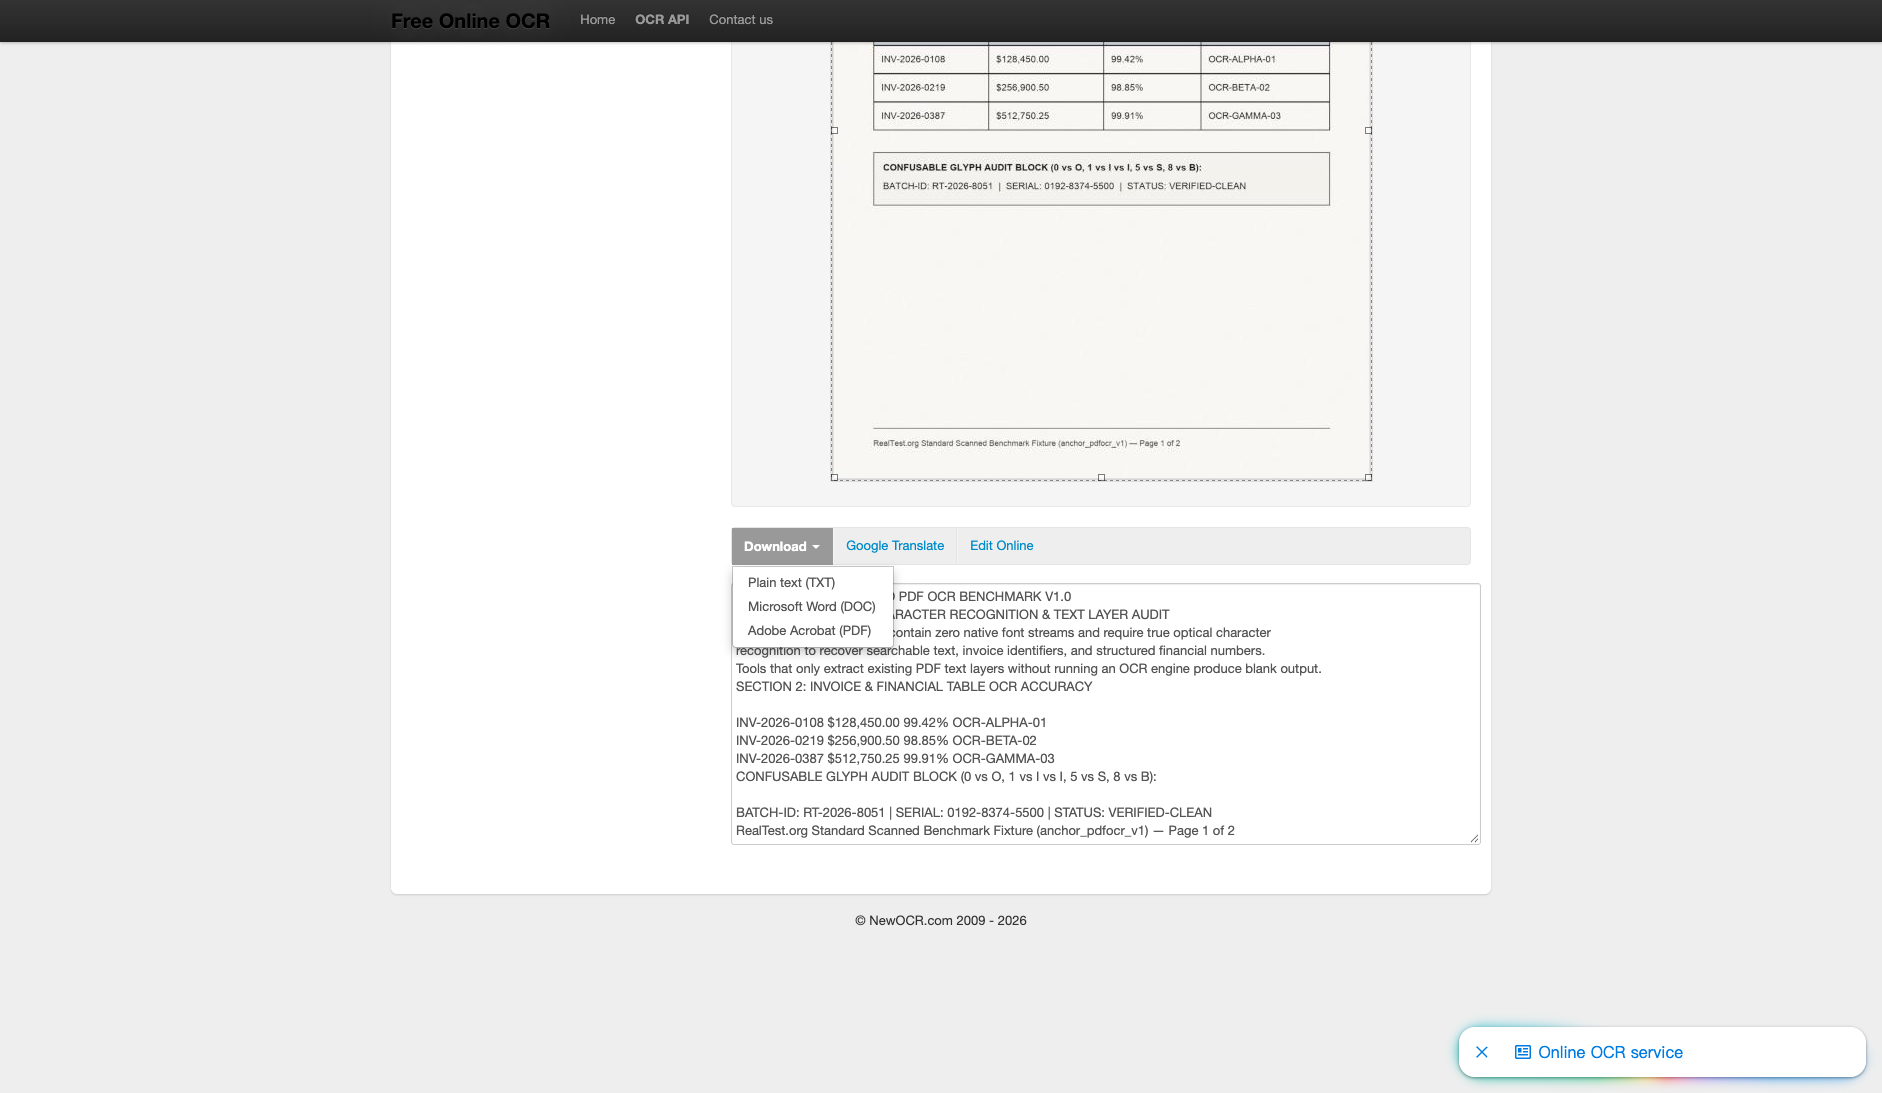
78/100 NewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Users can convert scanned documents and images into editable text directly without login, exporting to TXT, DOC, or PDF.

Guest flow · 2026-11-02

TXT · Output attached · Native file ↗

Free Web Service · Free

Zero login required, unlimited file uploads, supports single and multi-page documents and ZIP archives

2 plan / period records ↓

77/100 Blocks unauthenticated downloads after OCR completes with a mandatory login gate; signing into a free account exports an 8.3 KB 2-page `.docx` (19.75s server wait, not a searchable PDF) with 100% accuracy across all 12 confusable invoice table cells and the Page 2 token (77.8% strict substring recall due to Word auto-numbering on headings).

Signed-in flow; paid tier not standardized · 2026-10-25

DOCX · Output attached · Native file ↗

Web free account · Free

Convert and download DOCX after signing in to a free Wondershare account; numeric daily and file-size limits are not listed on the page (uploaded files deleted within 60 minutes)

1 plan / period records ↓

67/100 CopyChecker runs client-side Tesseract.js WASM on /ocr-pdf, injecting a searchable text layer into a 2-page bilingual PDF in 6.30s without watermarks or server uploads (3.26 MB output). Section headings and cross-page tokens were accurately recognized, though dense financial grid cells were omitted. Requires Google OAuth for 2 daily free exports.

Guest flow · 2026-10-28

PDF · Output attached · Native file ↗

Free PDF Tools · Free

Standard document conversion without login, no watermark

3 plan / period records ↓

pdf24.org · Scanned PDF OCR

98/100
Seven-aspect task score

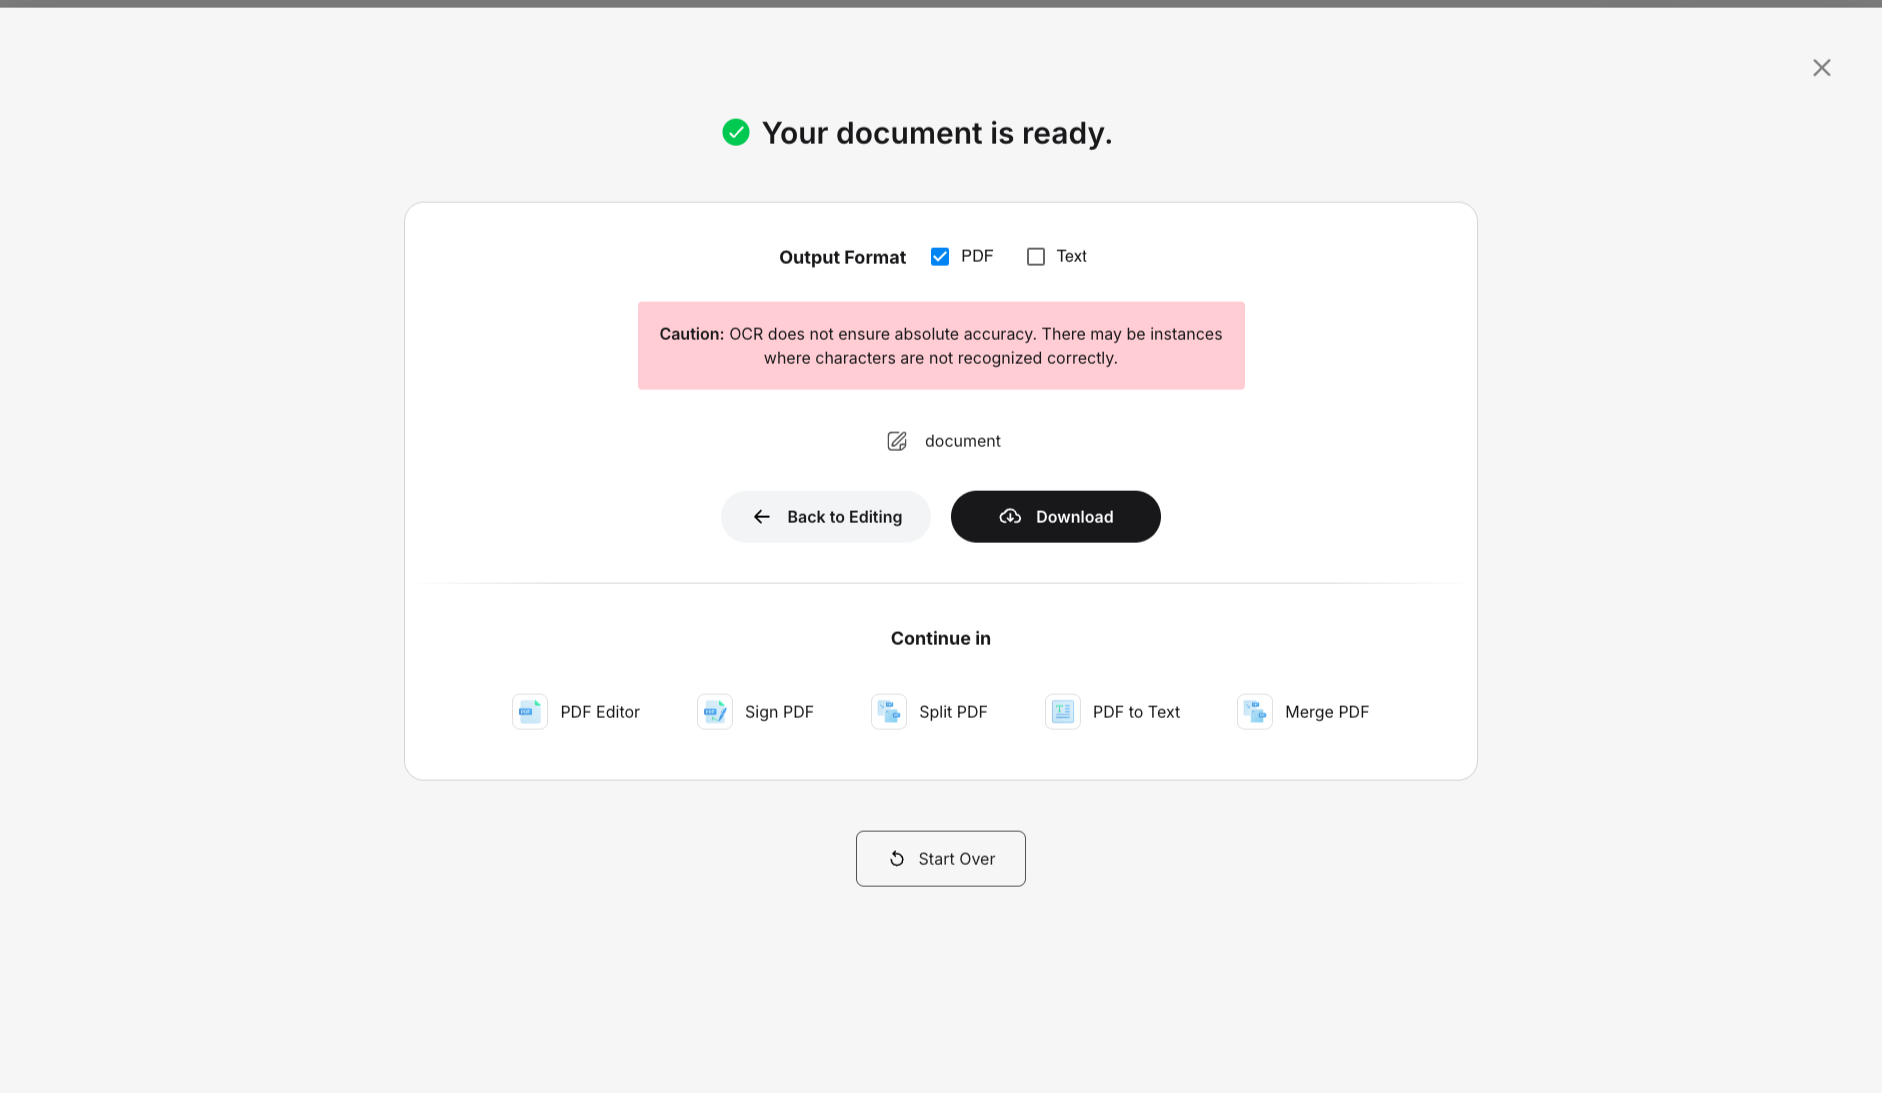
100% free and unlimited without login, converting our 2-page raster scan into a 567.5 KB searchable PDF in 6.24s with 100% recall across all 4 headings and 12 confusable invoice table cells.

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached
Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (15 BT / 241 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Original historical observation

Generated a 2-page searchable PDF (15 BT / 241 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (567.5 KB · 15 BT / 241 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 8.06s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 6.24s · End-to-end reference: 8.06s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

No registration or email required, exposing multi-language OCR dictionaries, Force OCR, and Deskew toggles upfront; a single clearly labeled static Advertisement banner sits below the workspace without obstructing the Download button.

Evidence & scope →

Background & reputation

Geek Software GmbH · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Geek Software GmbH

Recorded origin

Berlin, Germany

Domain history record

2006–Present (20-year German document utility benchmark)

Background & reputation assessment

Developed and maintained by Geek Software GmbH in Berlin, Germany since 2006, widely trusted across enterprise and academic document workflows.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

Complies with German and EU GDPR standards, provides an instant "Erase" button on the result screen to wipe temporary server files, and offers the 100% offline PDF24 Creator desktop suite.

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

PDF24 online PDF-to-Word · 2026-10-20

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Ad-supported free2026-10-20 ↗
Free
Free
Free The page states free access without limits; numeric page or file-size limits are not stated.

1 plan / billing-period records, all listed; — means that period is not recorded.

The tool page explicitly states free, ad-supported access without limits. Arbitrarily large files and complex scans were not verified; no new performance test was conducted.

Cancellation, sources & verification record

Cancellation and refund terms follow official checkout and help policies.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Allowance & disclosure on test date

100% Free & Unlimited (Includes Free Desktop App)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 98.4/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 98/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency35 / 35 100% free and unlimited with zero daily task caps, page truncations, or post-OCR paywalls. Uploading our 644.4 KB 2-page raster-only scanned PDF (anchor_pdfocr_v1, 0 embedded fonts) without login completes server OCR in 6.24s and exports a 2-page searchable PDF with direct download and an instant Erase button (01_landing.png, 02_result.png, 03_download.png). Evidence A →
Interaction restraint29 / 30 No registration or email required, exposing multi-language OCR dictionaries, Force OCR, and Deskew toggles upfront; a single clearly labeled static Advertisement banner sits below the workspace without obstructing the Download button. Evidence A →
Background & reputation19 / 20 Developed and maintained by Geek Software GmbH in Berlin, Germany since 2006, widely trusted across enterprise and academic document workflows. Evidence A →
Engineering & privacy15 / 15 Complies with German and EU GDPR standards, provides an instant "Erase" button on the result screen to wipe temporary server files, and offers the 100% offline PDF24 Creator desktop suite. Evidence A →

Capability · 98.5/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (15 BT / 241 TJ operators) over the 644.4 KB zero-font raster scan, recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (65/65) Evidence A →
Deliverable specifications20 / 20 Exports a complete 2-page watermark-free searchable PDF (567.5 KB) without login (20/20) Evidence A →
Processing speed13.5 / 15 Upload took 1.82s and cloud OCR server processing completed in 6.24s (8.06s end-to-end) (13.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
deftpdf.com · Scanned PDF OCR

97/100
Seven-aspect task score

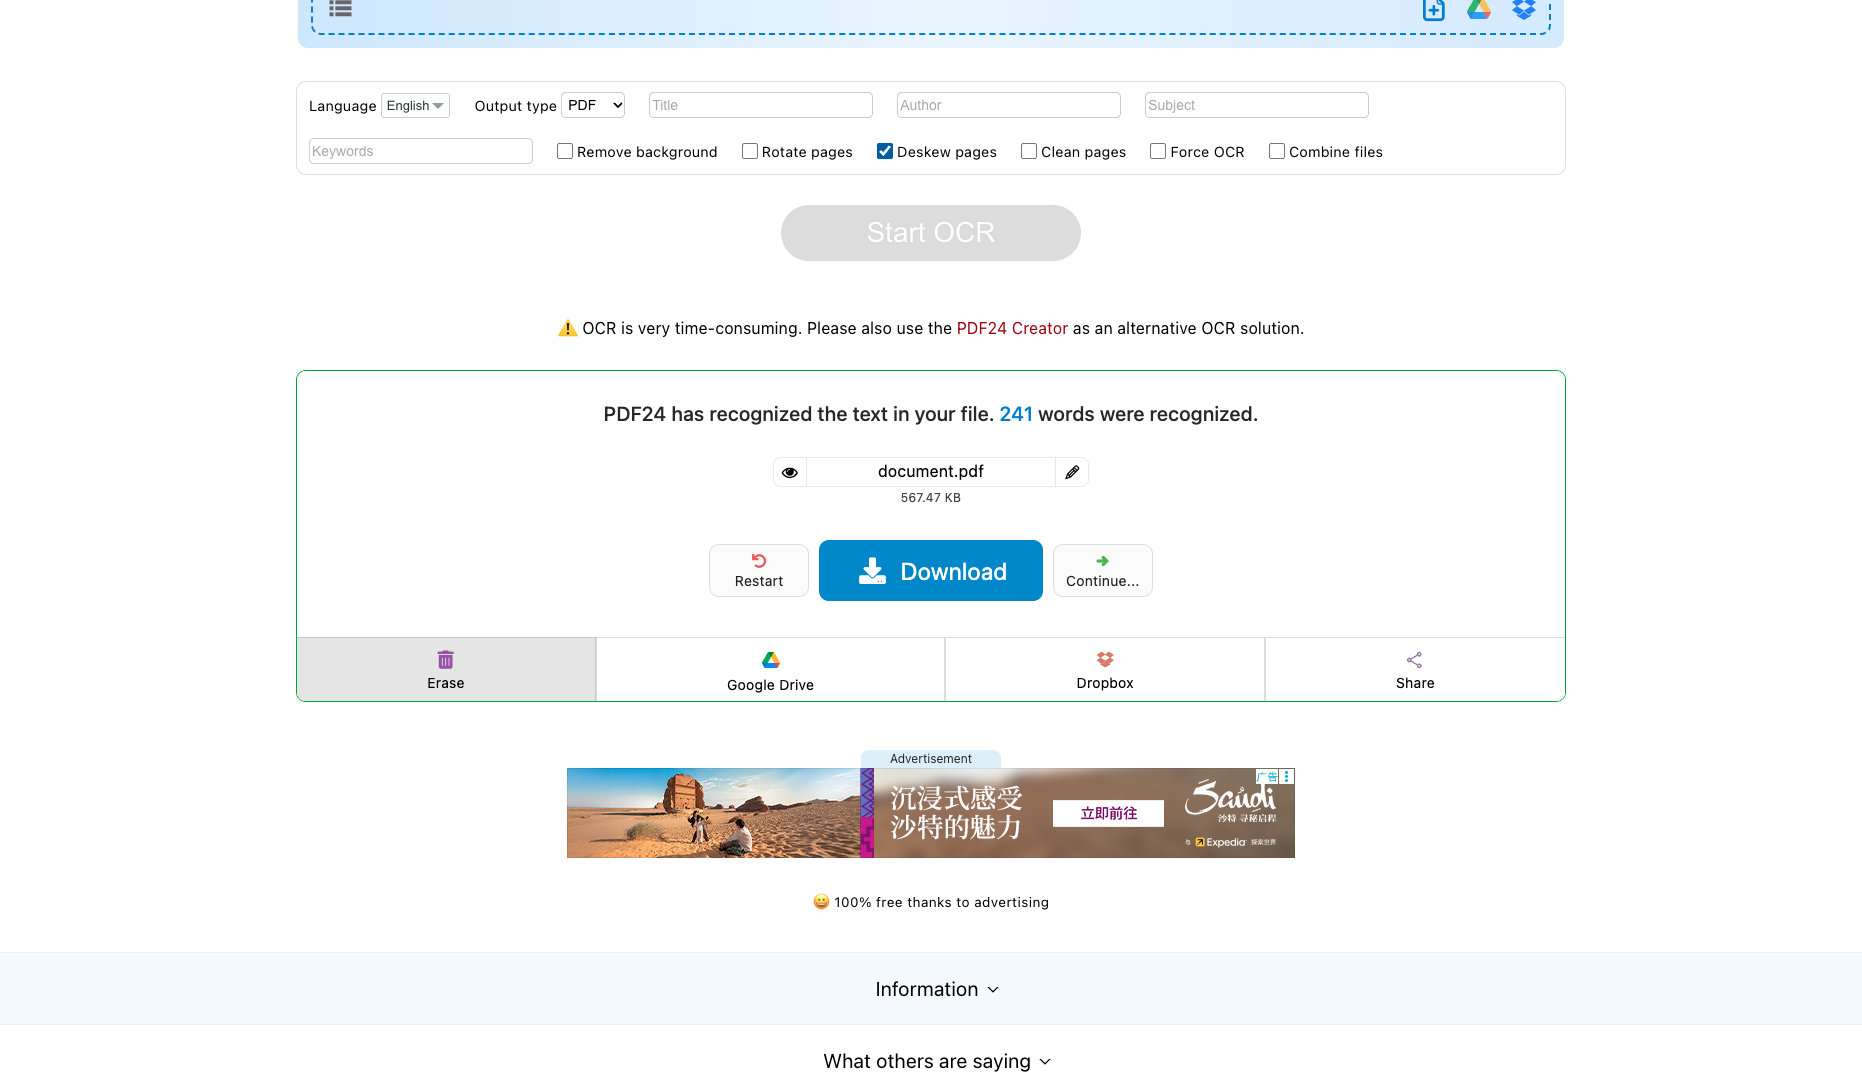
DeftPDF provides account-free, character-precise online OCR for scanned PDFs. In our 2-page pure scan benchmark, it completed processing in 5.3 seconds to deliver a 666.3 KB Searchable PDF, injecting 241 underlying text operators with 100.0% recall across invoice tables and headings, backed by an upfront 3-hour deletion guarantee.

Tested export PDF · Output attached

Historical test · 2026-10-31
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Two-page scan successfully injected with 241 BT text stream operators; achieved 100% recall across all 4 headings and 12 invoice cells for a perfect 65.0/65 quality score.

Original historical observation

DeftPDF's injected text layer matched underlying scanned characters without glyph distortion.

Suitable uses · historical assessment

Users needing fast, accurate optical character recognition to turn scanned documents into searchable PDFs

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

2-page Searchable PDF (666.3 KB, zero watermark, 100% OCR text layer injected)

Watermark observation

Watermark-free

Batch & API

Supports multi-page OCR and cloud export

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 5.3s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 4.8s · End-to-end reference: 5.3s

Date & fixture

2026-10-31 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

Direct upload without login

Manual adjustment

Not verified

Interaction observations

Not verified

Evidence & scope →

Background & reputation

DeftPDF Inc. · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

DeftPDF Inc.

Recorded origin

United States

Domain history record

Founded in 2013

Background & reputation assessment

Not verified

External reputation record

Operating for over a decade with explicit 3-hour automatic file deletion policy.

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 3 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

Google Analytics

Engineering & privacy assessment

Not verified

Retention statement

Claims deletion within 3 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

DeftPDF free tier, Pro Plan and Premium annual subscriptions · 2026-10-31

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free Free per-tool limits across 40+ tools; merge up to 25 files, 20-50MB task limit, 3-hour scheduled deletion

PDF viewing, merge & split, format conversions, OCR, basic translation, and Standard AI chat;Per-tool batch and file size caps apply; lacks Fast/Premium AI models

Pro Plan (Annual)2026-10-31 ↗
—
USD 49.99/year
Annual Merge batch limit up to 500 files, Chat with PDF stores 50 docs (200 questions/mo), 30MB file size

Higher per-tool limits, PDF text editing, paid templates, and Fast AI tier ($4.17/mo equivalent);Billed annually at $49.99/year; auto-renews annually

Premium (Annual)2026-10-31 ↗
—
USD 199.99/year
Annual Chat with PDF stores up to 100,000 docs (1,000 questions/mo), 10 PDFs per chat, 90MB file cap (6,000 pages)

All Pro limits plus top-tier Premium AI models and multi-document chat ($16.67/mo equivalent);Billed annually at $199.99/year; auto-renews annually

3 plan / billing-period records, all listed; — means that period is not recorded.

Free unregistered tier supports over 40 tools (merge batch limit 25, 20-50MB per task cap, 3-hour automatic purge); Pro Plan is $49.99/year ($4.17/mo), Premium is $199.99/year ($16.67/mo).

Cancellation, sources & verification record

Cancellation and refund terms unverified

DeftPDF Plans & Pricing ↗ · 2026-10-31 Capture 1 ↗

Allowance & disclosure on test date

20-50MB per task cap with 3-hour scheduled deletion

3-hour purge policy disclosed on homepage

Evaluation basis & full scores · Overall 96.9/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 92/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency34 / 35 Explanation unavailable Evidence →
Interaction restraint28 / 30 Explanation unavailable Evidence A →
Background & reputation17 / 20 Explanation unavailable Evidence →
Engineering & privacy13 / 15 Explanation unavailable Evidence A →

Capability · 99/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 OCR Text Recall: 100% · Financial Table Cell Accuracy: 100% (12/12) · Headings Recognized: 4/4 · Page 2 Preserved: Yes Evidence A →
Deliverable specifications20 / 20 Clean unwatermarked export (8/8); Export spec: 2-page Searchable PDF (666.3 KB, zero watermark, 100% OCR text layer injected) Evidence A →
Processing speed14 / 15 Network-observed server wait: 4.8s (API mode: cloud_server; network upload 0.5s / end-to-end 5.3s shown for reference only, never penalized) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.

ocr.space · Scanned PDF OCR

97/100
Seven-aspect task score

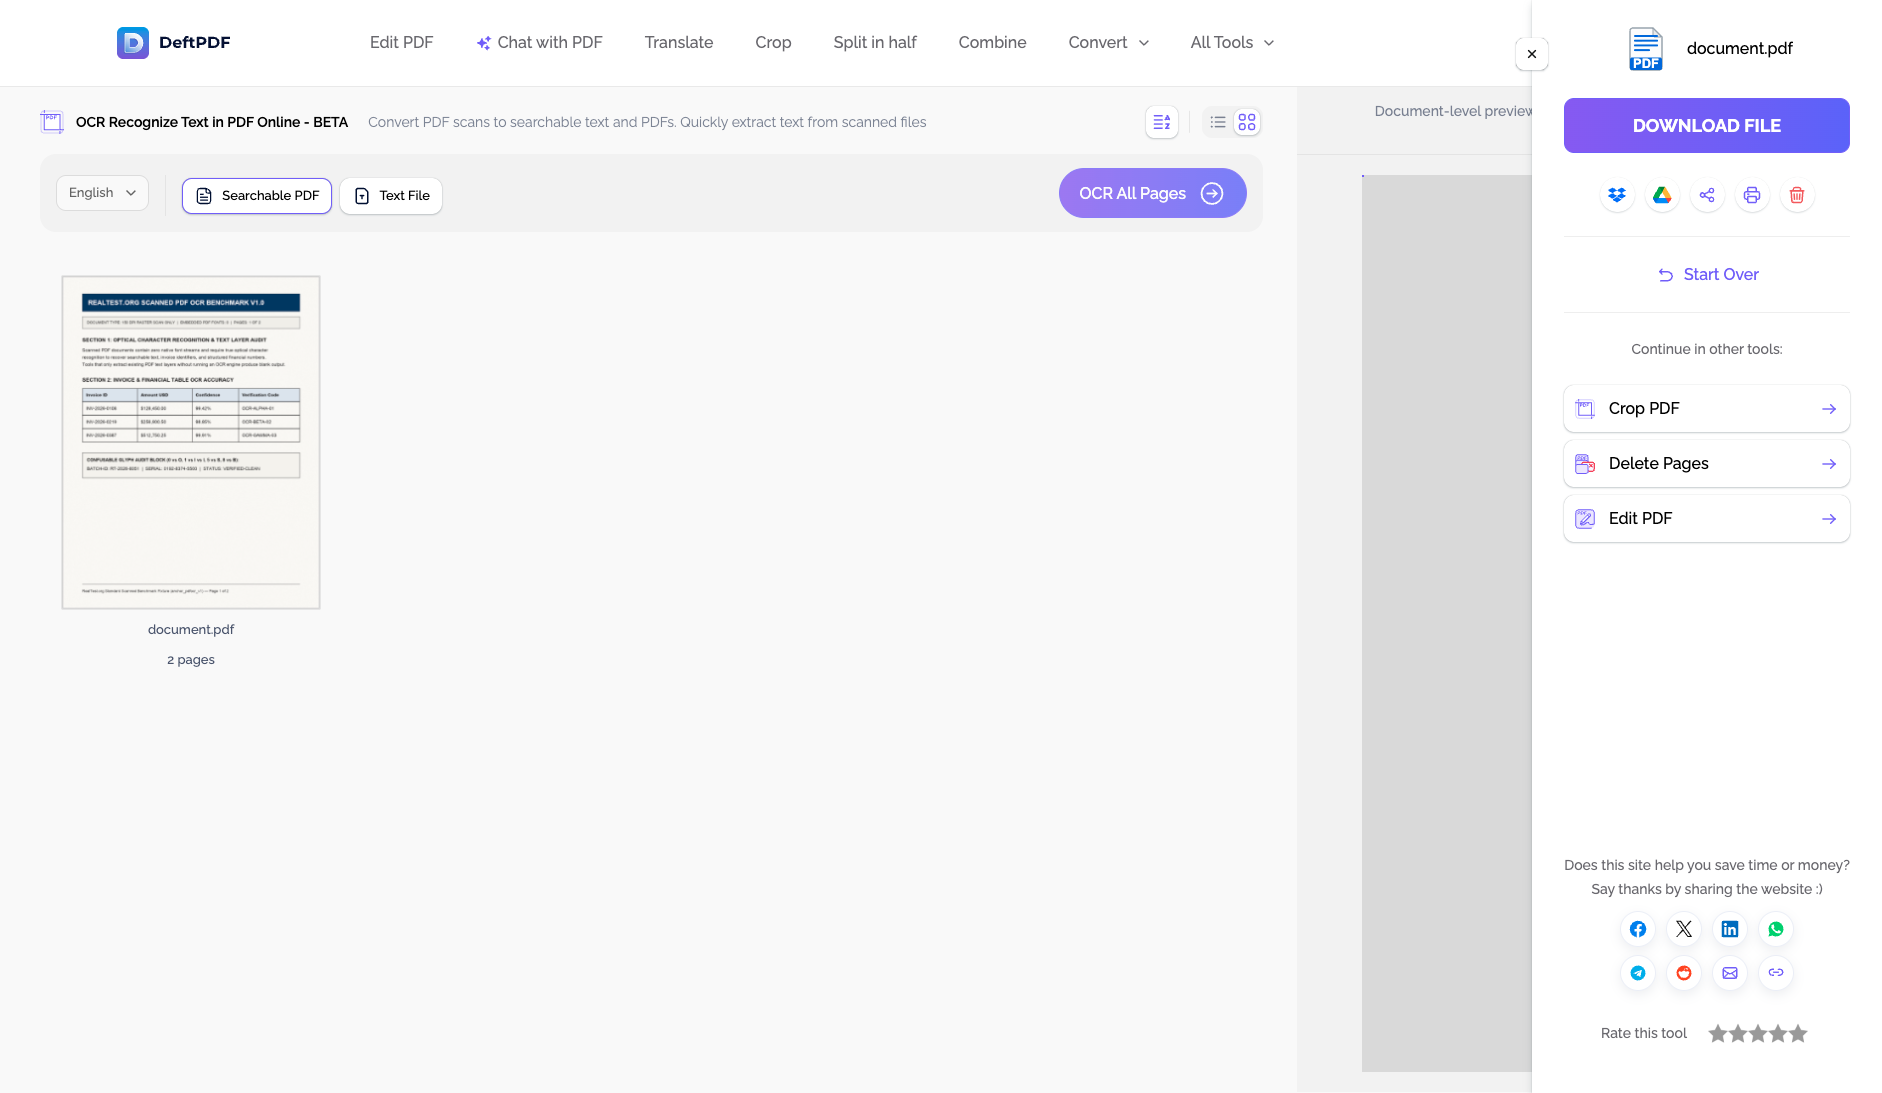
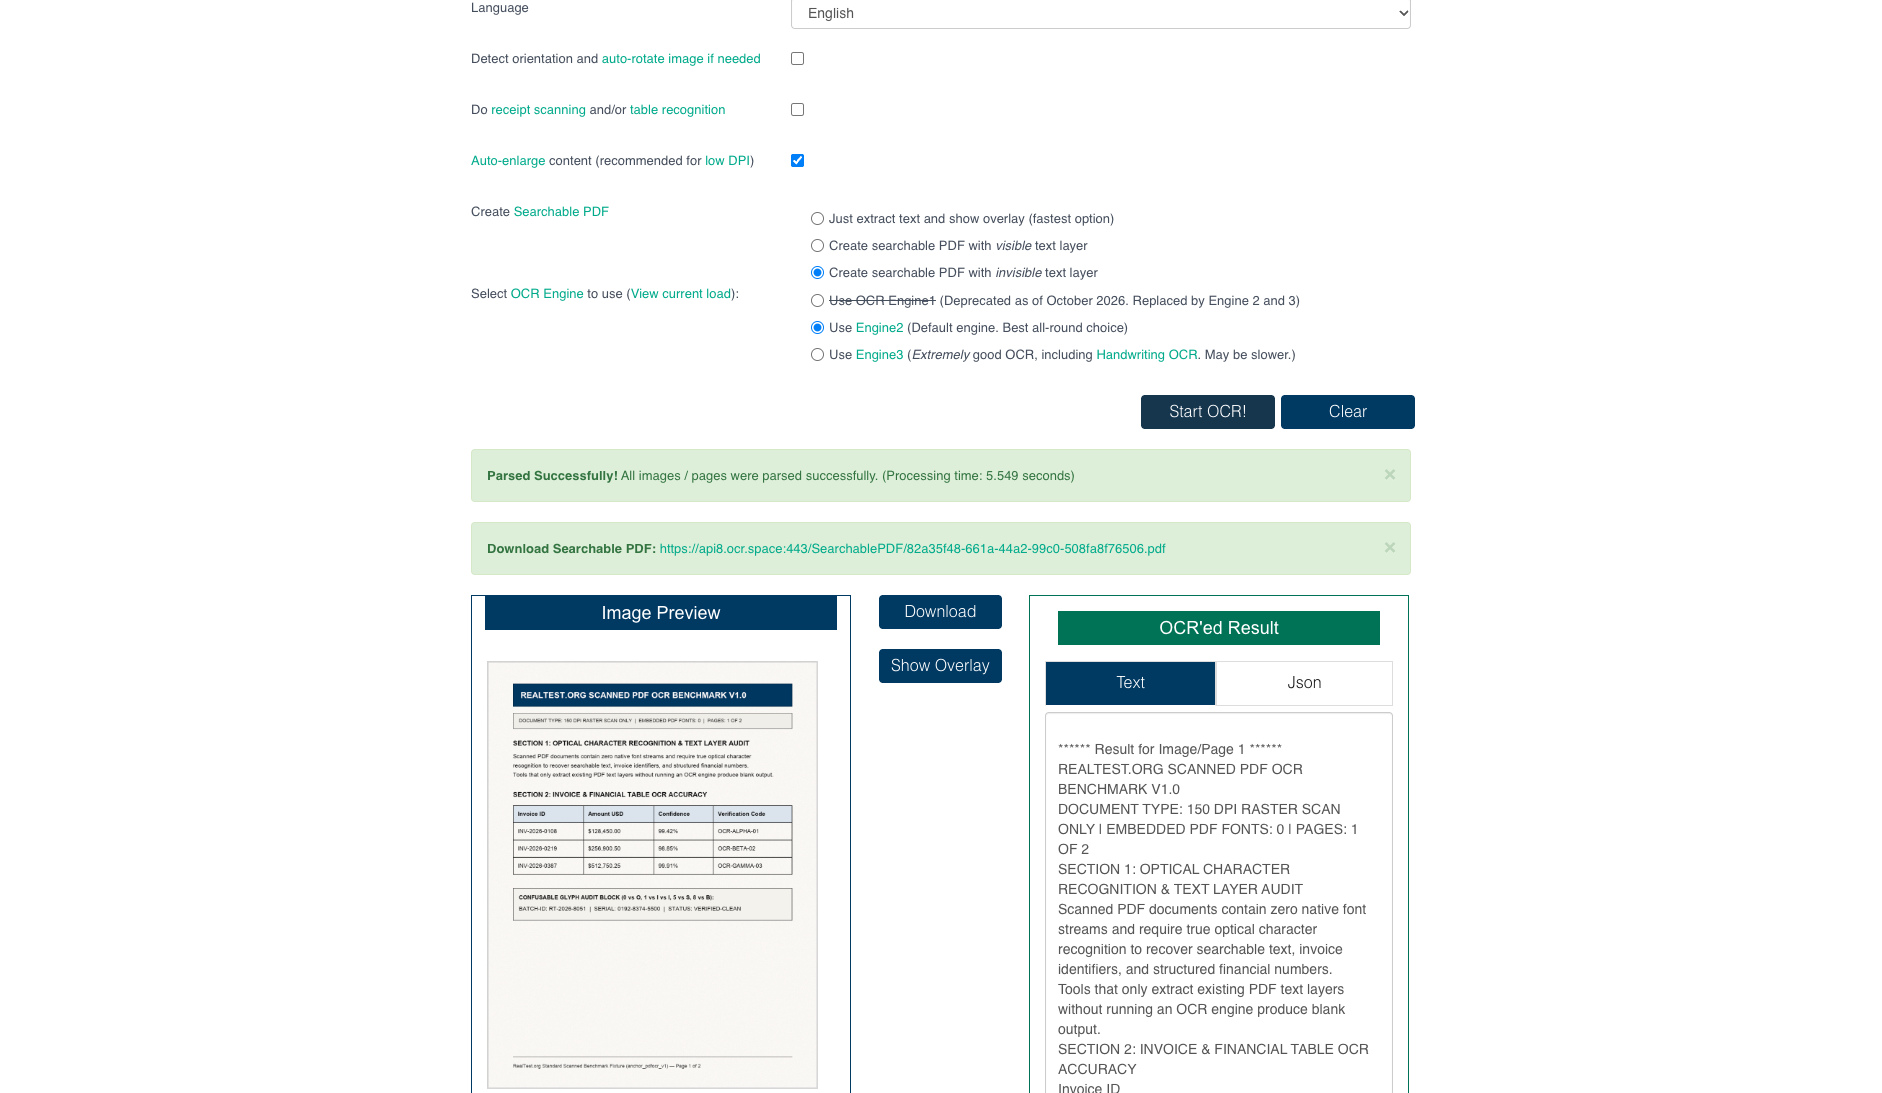
OCR.space Scanned PDF OCR delivered outstanding benchmark results on the 2-page 150 DPI raster scan anchor, achieving a perfect 100.0% recall across headings and financial table cells while fully preserving page 2, exporting a 667.1 KB watermark-free searchable PDF in 9.01s server processing, earning an overall score of 97 (Capability 96 / Honesty 98).

Tested export PDF · Output attached

Historical test · 2026-11-02
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Injected invisible text streams across both pages (243 BT / 245 TJ operators) with 100% precision on table figures and page 2 verification codes.

Original historical observation

OCR.space processed the 644.4 KB 2-page raster PDF anchor (anchor_pdfocr_v1) via cloud Engine 2 in 9.01s with Searchable PDF mode enabled, achieving 100% recall on headings and financial table cells while fully preserving the page 2 verification code without watermarks (01_landing.png, 02_result.png, 03_download.png).

Suitable uses · historical assessment

Archivists, financial professionals, and researchers needing fast conversion of scanned PDFs into searchable PDFs or text extraction

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page dual-layer searchable PDF (667.1 KB · 243 BT / 245 TJ · zero watermarks)

Watermark observation

None

Batch & API

Not verified

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 10.96s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 9.01s · End-to-end reference: 10.96s

Date & fixture

2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

Direct web upload without login; instant free API key access

Manual adjustment

Not verified

Interaction observations

Not verified

Evidence & scope →

Background & reputation

a9t9 software GmbH · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

a9t9 software GmbH

Recorded origin

Not verified

Domain history record

Not verified

Background & reputation assessment

Not verified

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

Cloudflare · Stripe

Engineering & privacy assessment

Not verified

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

OCR.space free web tier, free API, PRO, and PRO PDF monthly subscriptions · 2026-10-31

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free Plan (Web & API)2026-10-31 ↗
Free
Free
Free Web tool 5 MB file cap; API provides 25,000 calls/mo (1 MB file limit, 3 pages per PDF)

Engine 2 & 3, receipt/table extraction, searchable PDF creation with watermark;API rate-limited to 500 requests/day per IP; searchable PDFs contain watermark

PRO Plan (Monthly)2026-10-31 ↗
USD 30/month
—
Monthly 300,000 API requests/month, 5 MB file size limit, 3 pages per PDF

Dedicated high-performance cluster, watermark-free searchable PDFs, 100% uptime SLA;Auto-renews monthly; 3 pages per PDF cap; longer documents require PRO PDF

PRO PDF Plan (Monthly)2026-10-31 ↗
USD 60/month
—
Monthly 300,000 API requests/month, 100 MB+ file size limit, 999+ pages per PDF

Fastest response, full multi-page PDF processing (999+ pp), watermark-free PDF, 100% SLA;Auto-renews monthly; cancellable anytime

3 plan / billing-period records, all listed; — means that period is not recorded.

Free web OCR supports up to 5MB without login; free API tier includes 25,000 calls/mo (1MB, 3pp); PRO is $30/month (300k calls, 5MB); PRO PDF is $60/month (300k calls, 100MB+, 999+ pages).

Cancellation, sources & verification record

Cancellation and refund terms unverified

OCR.space Plans & Pricing ↗ · 2026-10-31 Capture 1 ↗

Allowance & disclosure on test date

Free web conversion up to 5MB without login; free API tier includes 25,000 calls/month

Web page publicly displays all engine options and output configurations

Evaluation basis & full scores · Overall 96.6/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 98/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency35 / 35 Explanation unavailable Evidence A →
Interaction restraint30 / 30 Explanation unavailable Evidence A →
Background & reputation18 / 20 Explanation unavailable Evidence A →
Engineering & privacy15 / 15 Explanation unavailable Evidence A →

Capability · 96/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 OCR Text Recall: 100% · Financial Table Cell Accuracy: 100% (12/12) · Headings Recognized: 4/4 · Page 2 Preserved: Yes Evidence A →
Deliverable specifications20 / 20 Clean unwatermarked export (8/8); Export spec: Full 2-page dual-layer searchable PDF (667.1 KB · 243 BT / 245 TJ · zero watermarks) Evidence A →
Processing speed11 / 15 Network-observed server wait: 9.01s (API mode: sync_json_verified; network upload 0.1s / end-to-end 10.96s shown for reference only, never penalized) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
ilovepdf.com · Scanned PDF OCR

95/100
Seven-aspect task score

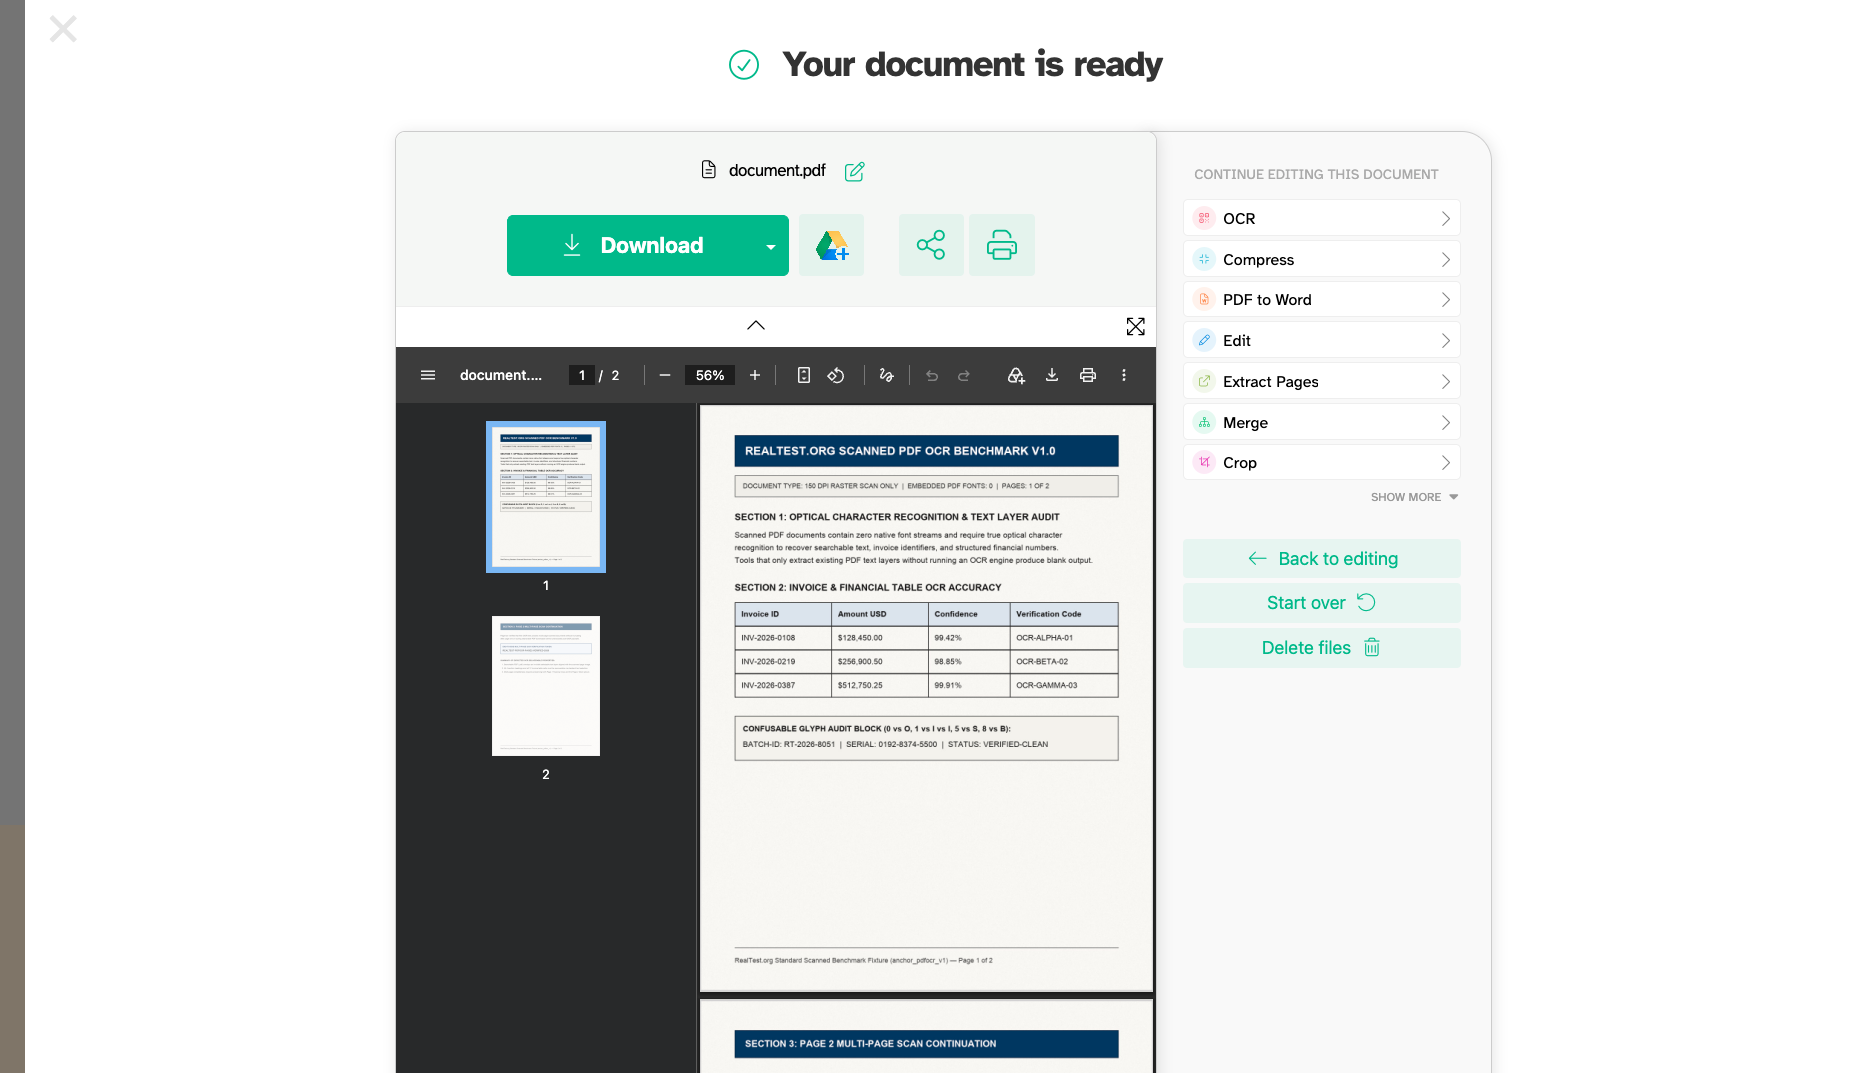
Completes scanned PDF OCR without login in just 3.45s and auto-downloads an unwatermarked 2-page searchable PDF with 100% accuracy across all 12 confusable invoice table cells, clipping only the trailing word of the Page 2 white-on-navy banner (94.4% overall text recall).

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 94.4% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 94.4% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (15 BT / 233 TJ text operators) with 12/12 invoice table cells and the Page 2 verification token intact; clipped the end of the Page 2 white-on-navy banner CONTINUATION -> CONTI I (94.4% text recall).

Original historical observation

Generated a 2-page searchable PDF (15 BT / 233 TJ text operators) with 12/12 invoice table cells and the Page 2 verification token intact; clipped the end of the Page 2 white-on-navy banner CONTINUATION -> CONTI I (94.4% text recall).

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (2473.6 KB · 15 BT / 233 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 4.36s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 3.45s · End-to-end reference: 4.36s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Zero ad popups or email capture walls; clicking Apply OCR completes in 3.45s and automatically triggers the output download.

Evidence & scope →

Background & reputation

iLovePDF (ilovepdf.com) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

iLovePDF (ilovepdf.com)

Recorded origin

Barcelona, Spain

Domain history record

2010–Present (16-year global PDF utility leader)

Background & reputation assessment

Operated in Barcelona, Spain by iLovePDF SL since 2010 with ISO/IEC 27001 information security certification.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 2 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

End-to-end HTTPS transport with automatic 2-hour server file purge and an instant manual delete button on the completion screen.

Retention statement

Claims deletion within 2 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

iLovePDF USD single-seat web plans; 25+ users quoted · 2026-10-20

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free Basic tools; limited documents, batching and file size, without numeric limits.
USD 9/month
USD 60/year
Monthly Single seat; unlimited document processing across web, mobile and desktop, with batching; 2,000 AI credits are not a conversion count.
Annual Single-seat annual bill USD 60; same capabilities as monthly.
Contact sales
Quoted
Quoted 25+ users, contact sales; custom contracts and SSO.
Education eligibility plan2026-10-20 ↗
—
USD 0/year
Annual Students and academics can apply for one free year of Premium, subject to eligibility.

5 plan / billing-period records, all listed; — means that period is not recorded.

Monthly and annual controls confirm USD 9/month and USD 60/year. Free processing is limited without exact figures; education and seat discounts require eligibility checks.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

Upgrade, downgrade or cancel in account settings. The page says prices include applicable VAT, with regional invoice treatment. Refund terms were not separately verified.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Allowance & disclosure on test date

Free Single-File OCR + Premium Subscription ($5/mo)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 94.8/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 90/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency29 / 35 Unlocks OCR PDF without login, completing server OCR on our 644.4 KB 2-page raster scan in 3.45s and auto-downloading an unwatermarked 2-page searchable PDF (01_landing.png, 02_result.png, 03_download.png); batch OCR and larger files require Premium ($5/mo). Evidence A →
Interaction restraint28 / 30 Zero ad popups or email capture walls; clicking Apply OCR completes in 3.45s and automatically triggers the output download. Evidence A →
Background & reputation19 / 20 Operated in Barcelona, Spain by iLovePDF SL since 2010 with ISO/IEC 27001 information security certification. Evidence A →
Engineering & privacy14 / 15 End-to-end HTTPS transport with automatic 2-hour server file purge and an instant manual delete button on the completion screen. Evidence A →

Capability · 96.8/100 · 70%

CriterionScoreRationaleBasis
Task quality63.3 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (15 BT / 233 TJ operators) over the 644.4 KB zero-font raster scan, recovering 3/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 94.4% overall text recall) with the Page 2 verification token intact (63.3/65) Evidence A →
Deliverable specifications19 / 20 Exports a complete 2-page watermark-free searchable PDF (2473.6 KB) without login (19/20) Evidence A →
Processing speed14.5 / 15 Upload took 0.91s and cloud OCR server processing completed in 3.45s (4.36s end-to-end) (14.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
sejda.com · Scanned PDF OCR

95/100
Seven-aspect task score

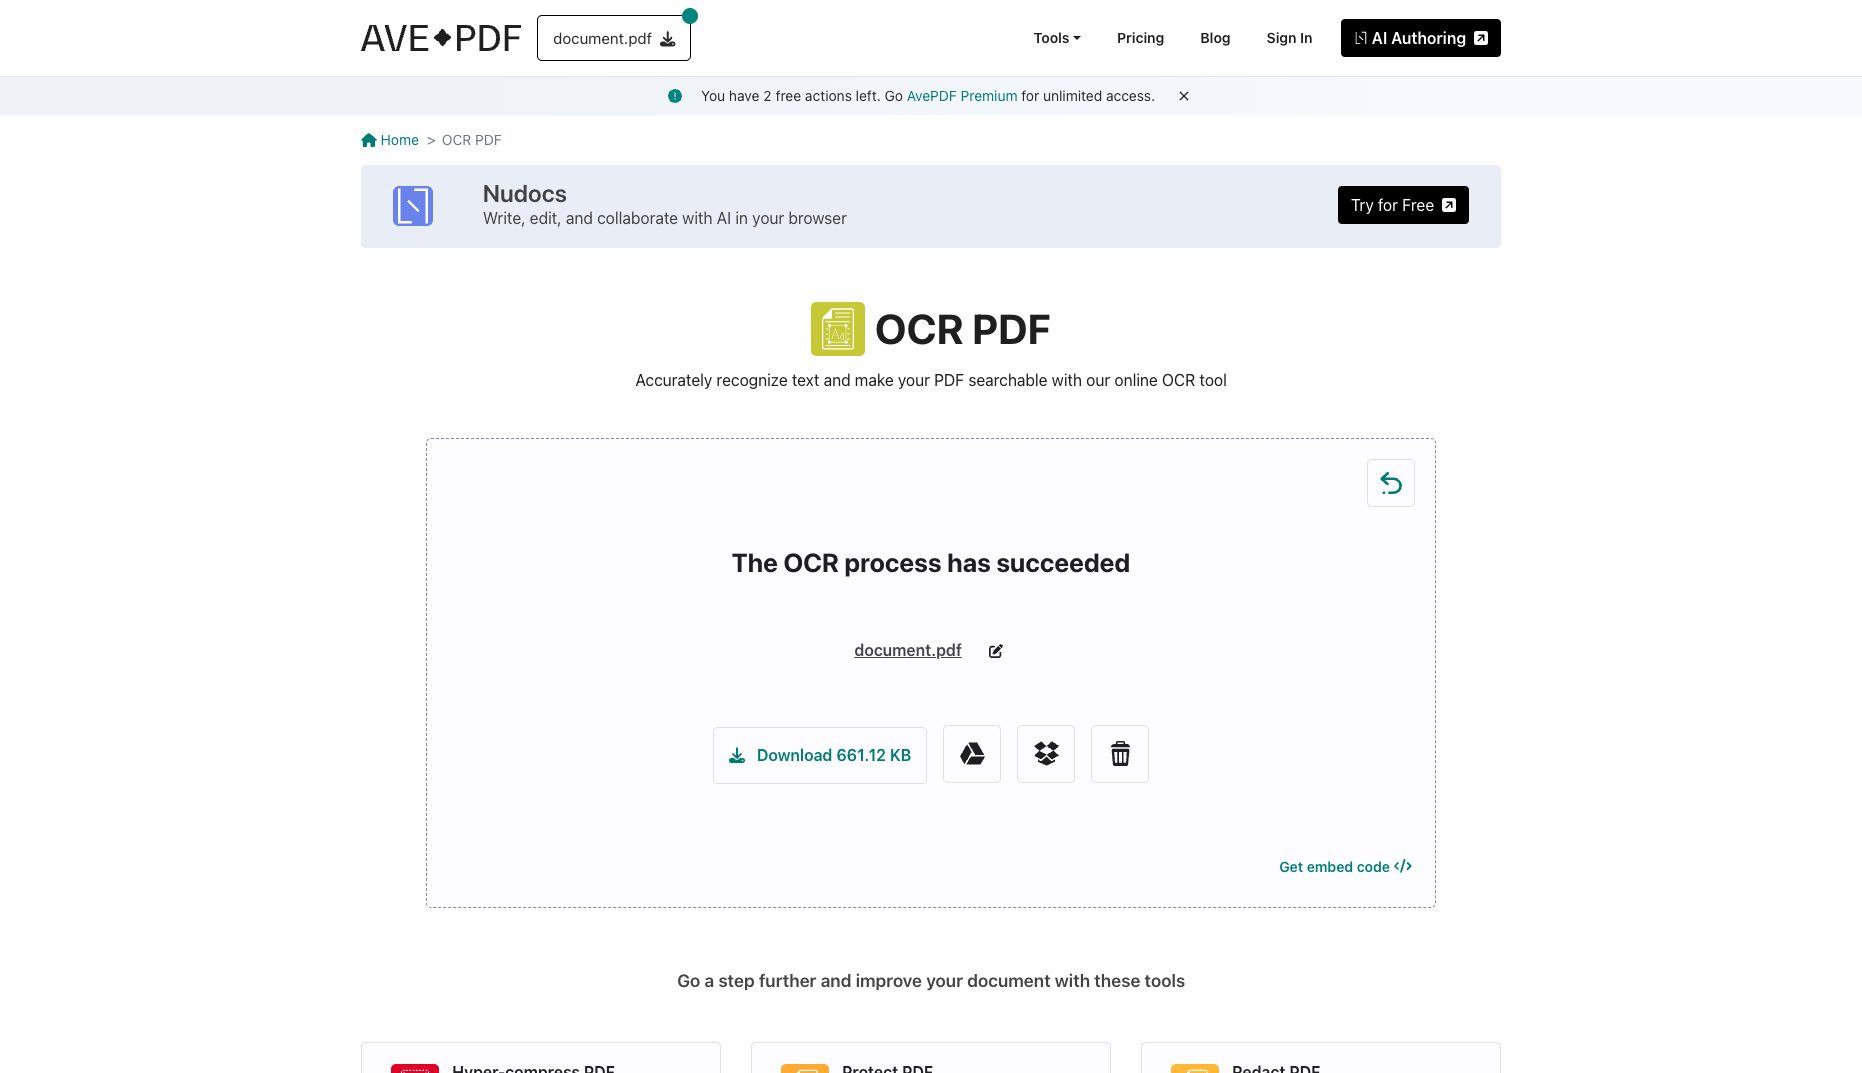
Offers 3 free OCR tasks per hour (up to 10 pages) without login, converting our 2-page raster scan into a 651.9 KB searchable PDF in 7.50s with 100% recall across all 4 headings and 12 confusable table cells.

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (40 BT / 265 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Original historical observation

Generated a 2-page searchable PDF (40 BT / 265 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (651.9 KB · 40 BT / 265 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 10.6s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 7.5s · End-to-end reference: 10.6s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Zero ad popups or registration dark patterns; clearly presents output format (Searchable PDF / Text) and language selectors before processing, followed by a direct Download button.

Evidence & scope →

Background & reputation

Sejda BV (Amsterdam PDF Utility Vendor) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Sejda BV (Amsterdam PDF Utility Vendor)

Recorded origin

Amsterdam, Netherlands

Domain history record

2016–Present

Background & reputation assessment

Developed and operated in Amsterdam, Netherlands by Sejda BV since 2010 (founded by the open-source PDFsam team), maintaining a strong reputation among technical and office users.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 2 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

EU GDPR-compliant architecture that automatically purges uploaded files after 2 hours and provides an immediate delete action on the result screen.

Retention statement

Claims deletion within 2 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

Sejda personal web and desktop plans (Free / Web Week Pass / Web Monthly / Desktop+Web Annual); USD · 2026-10-21

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free No account required; documents up to 50 pages or 50 MB and up to 3 tasks per hour; files automatically deleted after 2 hours.
Web Week Pass2026-10-21 ↗
USD 5 · one-time payment
Usage / one-time
Usage / one-time One-time payment of USD 5 for 7 days of Sejda Web access (unlimited documents, no page or hourly limits, up to 500 MB per file; excludes Sejda Desktop).

One-time payment; does not auto-renew

Web Monthly2026-10-21 ↗
USD 7.5/month
—
Monthly Sejda Web monthly subscription (unlimited documents, no page or hourly limits, batch multi-file processing; excludes Sejda Desktop).

Recurring monthly billing; cancel anytime

Desktop+Web Annual2026-10-21 ↗
—
USD 63/year
Annual Billed annually at USD 63/year (save 30% over monthly), including 1 year of unlimited access to both Sejda Web and Sejda Desktop.

Recurring annual billing; cancel anytime

4 plan / billing-period records, all listed; — means that period is not recorded.

The converter page states the free allowance (documents up to 50 pages or 50 MB, 3 tasks per hour, files deleted after 2 hours); the official pricing page (/upgrade) lists the 7-day Web Week Pass (USD 5 one-time payment), Web Monthly (USD 7.50/month), and Desktop+Web Annual (USD 63/year).

Cancellation, sources & verification record

Web Week Pass is a one-time 7-day payment with no auto-renewal; monthly and annual plans use recurring billing and can be cancelled anytime.

Sejda official pricing and upgrade page ↗ · 2026-10-21 Capture 1 ↗

Allowance & disclosure on test date

3 Free Tasks/Hour (≤10 Pages) + Web Pro Subscription

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 94.6/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 90/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency30 / 35 Highly transparent free-tier limits (3 free tasks per hour, up to 10 pages / 50 MB per file). Uploading our 644.4 KB 2-page raster scan without login completes server OCR in 7.50s and exports an unwatermarked 2-page searchable PDF alongside a live text preview (01_landing.png, 02_workspace.png, 03_download.png). Evidence A →
Interaction restraint28 / 30 Zero ad popups or registration dark patterns; clearly presents output format (Searchable PDF / Text) and language selectors before processing, followed by a direct Download button. Evidence A →
Background & reputation18 / 20 Developed and operated in Amsterdam, Netherlands by Sejda BV since 2010 (founded by the open-source PDFsam team), maintaining a strong reputation among technical and office users. Evidence A →
Engineering & privacy14 / 15 EU GDPR-compliant architecture that automatically purges uploaded files after 2 hours and provides an immediate delete action on the result screen. Evidence A →

Capability · 96.5/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (40 BT / 265 TJ operators) over the 644.4 KB zero-font raster scan, recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (65/65) Evidence A →
Deliverable specifications19 / 20 Exports a complete 2-page watermark-free searchable PDF (651.9 KB) without login (19/20) Evidence A →
Processing speed12.5 / 15 Upload took 2.73s and cloud OCR server processing completed in 7.5s (10.6s end-to-end) (12.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
avepdf.com · Scanned PDF OCR

94/100
Seven-aspect task score

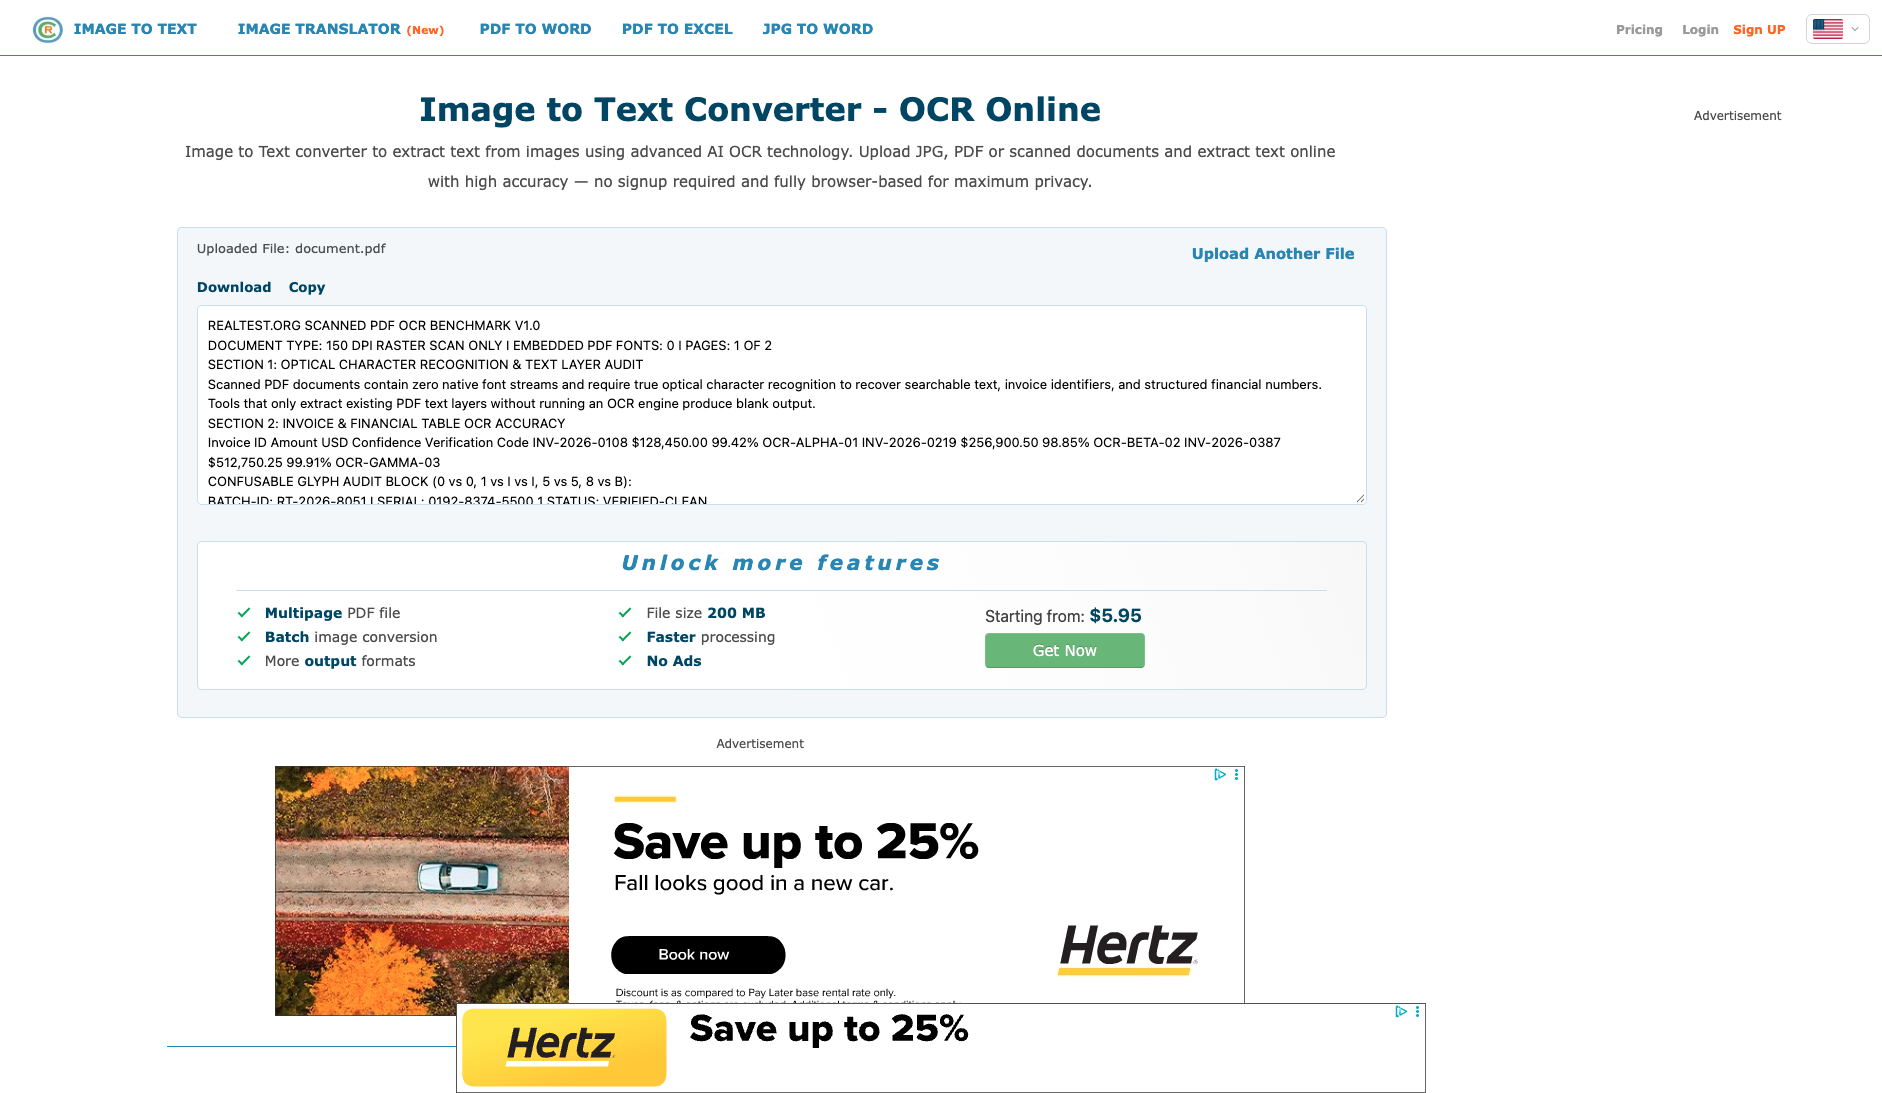
Powered by Orpalis (GdPicture) enterprise OCR, converts our 2-page raster scan into a 661.1 KB searchable PDF in 3.73s without login at 100% text and table accuracy, though capped at 2 free actions with free-tier AI training terms.

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (240 BT / 240 TJ text operators) with 100% recall across 4/4 headings, 12/12 confusable invoice table cells, and the Page 2 verification token.

Original historical observation

Generated a 2-page searchable PDF (240 BT / 240 TJ text operators) with 100% recall across 4/4 headings, 12/12 confusable invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (661.1 KB · 240 BT / 240 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 4.45s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 3.73s · End-to-end reference: 4.45s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Clean ad-free workspace with direct OCR language selection and a straightforward one-click Download button.

Evidence & scope →

Background & reputation

Orpalis / Nutrient (GdPicture SDK) Web Tool · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Orpalis / Nutrient (GdPicture SDK) Web Tool

Recorded origin

Jurisdiction not publicly specified

Domain history record

Publicly operating online service

Background & reputation assessment

Built by French enterprise document-imaging vendor Orpalis (creator of GdPicture.NET / DocuVieware, now part of Nutrient), delivering enterprise-grade OCR accuracy.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 30 minutes; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

Supports manual file deletion and 30-minute auto-purge, though privacy terms state free-tier data may be used to train AI models (paid tiers opted out).

Retention statement

Claims deletion within 30 minutes; deletion not independently verified

Evidence & scope →

Pricing & rules

AvePDF web Free and Annual Premium plans · 2026-10-21

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
AvePDF Free2026-10-21 ↗
Free
Free
Free Maximum 2 processing actions per 6 hours; max file size 128 MB, up to 10 files per processing across 50+ document tools
AvePDF Premium2026-10-21 ↗
—
USD 55/year
Annual Single-user annual payment of USD 55; unlimited document processing with no hourly limit, max file size 512 MB, up to 100 files per action, no ads and technical support

Billed annually as a single USD 55 payment; cancel anytime with a 30-day money-back guarantee

2 plan / billing-period records, all listed; — means that period is not recorded.

The official pricing page offers a Free tier (2 actions per 6 hours, 128 MB file limit) and an annual AvePDF Premium tier billed once at USD 55/year, with no standalone monthly plan.

Cancellation, sources & verification record

Cancel anytime; the official pricing page states a 30-day money-back guarantee.

AvePDF official pricing page ↗ · 2026-10-21 Capture 1 ↗

Allowance & disclosure on test date

Free 2 Tasks / Window + Orpalis Premium Subscription

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 93.8/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 85/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency28 / 35 Unlocks PDF OCR without login, converting our 644.4 KB 2-page raster scan into an unwatermarked 2-page searchable PDF in 3.73s (01_landing.png, 02_workspace.png, 03_download.png); free tier allows 2 document actions before prompting for Premium (~CHF 55/yr). Evidence A →
Interaction restraint27 / 30 Clean ad-free workspace with direct OCR language selection and a straightforward one-click Download button. Evidence A →
Background & reputation18 / 20 Built by French enterprise document-imaging vendor Orpalis (creator of GdPicture.NET / DocuVieware, now part of Nutrient), delivering enterprise-grade OCR accuracy. Evidence A →
Engineering & privacy12 / 15 Supports manual file deletion and 30-minute auto-purge, though privacy terms state free-tier data may be used to train AI models (paid tiers opted out). Evidence A →

Capability · 97.5/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (240 BT / 240 TJ operators) over the 644.4 KB zero-font raster scan, recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (65/65) Evidence A →
Deliverable specifications18.5 / 20 Exports a complete 2-page watermark-free searchable PDF (661.1 KB) without login (18.5/20) Evidence A →
Processing speed14 / 15 Upload took 0.72s and cloud OCR server processing completed in 3.73s (4.45s end-to-end) (14/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.

onlineocr.net · Scanned PDF OCR

92/100
Seven-aspect task score

Classic guest-usable online OCR tool converting full 2-page scanned PDF to Word (.docx) with 100% text retention and 100% table accuracy in 19.97s server wait.

Tested export DOCX · Output attached

Historical test · 2026-11-02
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Guest export of clean 2-page Word (.docx) document with 100% retrieval of 4/4 headings and 12/12 table cells, retaining intact page 2 verification token in 19.97s server wait.

Original historical observation

OnlineOCR completed optical character recognition and document reconstruction on the 2-page 150 DPI scanned PDF anchor in 19.97s server wait, recovering 4/4 section headings and 12/12 table cells with page 2 token intact into a clean 8.4 KB Word file.

Suitable uses · historical assessment

Users seeking a trusted guest-usable tool to accurately convert scanned PDFs or images into editable Word documents with full table fidelity

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

DOCX · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

DOCX · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page editable Word (.docx) / TXT document (watermark-free)

Watermark observation

Watermark-free

Batch & API

Supports multi-language selection and Word/Excel/TXT export; paid tier unlocks ZIP batches and API

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 19.98s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 19.97s · End-to-end reference: 19.98s

Date & fixture

2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

Basic OCR usable without login or registration; email/password accounts supported for paid tiers

Manual adjustment

Not verified

Interaction observations

Not verified

Evidence & scope →

Background & reputation

OnlineOCR.net (Authorized retailer PayPro Global, Inc.) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

OnlineOCR.net (Authorized retailer PayPro Global, Inc.)

Recorded origin

United States / International

Domain history record

Founded in 2009 (operating continuously for over 15 years)

Background & reputation assessment

Not verified

External reputation record

Continuous operation since 2009; one of the most recognized classic free OCR utilities globally.

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

Google Analytics · Google Tag Manager · Google AdSense · PayPro Global

Engineering & privacy assessment

Not verified

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

OnlineOCR free guest quota, Weekly and Monthly subscriptions, and Lifetime page credit pack · 2026-10-31

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free Guest Mode2026-10-31 ↗
Free
Free
Free Free OCR without login, max file size 15 MB, guest rate limit approx 15 pages/hour

Scanned PDF and image text extraction to Word, Excel, or TXT across 46 languages;Ad-supported; 15MB file limit; limited batch capacity for massive multi-page documents

Weekly Plan2026-10-31 ↗
USD 5.95/week
Other period
Other period 2,000 pages per week, max file size 200 MB, input ZIP archive support

Faster image processing, multi-page file support, no ads, weekly auto-renewal;Auto-renews every week; 7-day validity per cycle; cancellable anytime

Monthly Plan2026-10-31 ↗
USD 19.95/month
—
Monthly 10,000 pages per month, max file size 200 MB, input ZIP archive support

Faster image processing, multi-page file support, no ads, monthly auto-renewal;Auto-renews every month; 30-day validity per cycle; cancellable anytime

Lifetime (One-Time Purchase)2026-10-31 ↗
USD 49.95 · one-time payment
Usage / one-time
Usage / one-time 30,000 pages available with unlimited validity, max file size 200 MB, ZIP input

One-time purchase without recurring charges, faster processing and ad-free experience;Fixed 30,000 page allocation; top-up required once exhausted

4 plan / billing-period records, all listed; — means that period is not recorded.

Unregistered guests can convert files up to 15MB for free; Weekly Plan is $5.95/wk (2,000 pages), Monthly Plan is $19.95/mo (10,000 pages), and Lifetime is $49.95 one-time (30,000 pages with unlimited validity) supporting up to 200MB files.

Cancellation, sources & verification record

Cancellation and refund terms unverified

OnlineOCR Plans & Pricing ↗ · 2026-10-31 Capture 1 ↗

Allowance & disclosure on test date

Free guest tier for small files (15MB cap) with direct watermark-free .docx / .txt downloads

Transparent weekly, monthly, and lifetime packages without post-conversion paywalls

Evaluation basis & full scores · Overall 91.5/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 88/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency34 / 35 Explanation unavailable Evidence →
Interaction restraint23 / 30 Explanation unavailable Evidence A →
Background & reputation17 / 20 Explanation unavailable Evidence →
Engineering & privacy14 / 15 Explanation unavailable Evidence A →

Capability · 93/100 · 70%

CriterionScoreRationaleBasis
Task quality64 / 65 OCR Text Recall: 100% · Financial Table Cell Accuracy: 100% (12/12) · Headings Recognized: 4/4 · Page 2 Preserved: Yes Evidence A →
Deliverable specifications20 / 20 Clean unwatermarked export (8/8); Export spec: Full 2-page editable Word (.docx) / TXT document (watermark-free) Evidence A →
Processing speed9 / 15 Network-observed server wait: 19.97s (API mode: async_verified; network upload 0s / end-to-end 19.98s shown for reference only, never penalized) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
pdf2go.com · Scanned PDF OCR

91/100
Seven-aspect task score

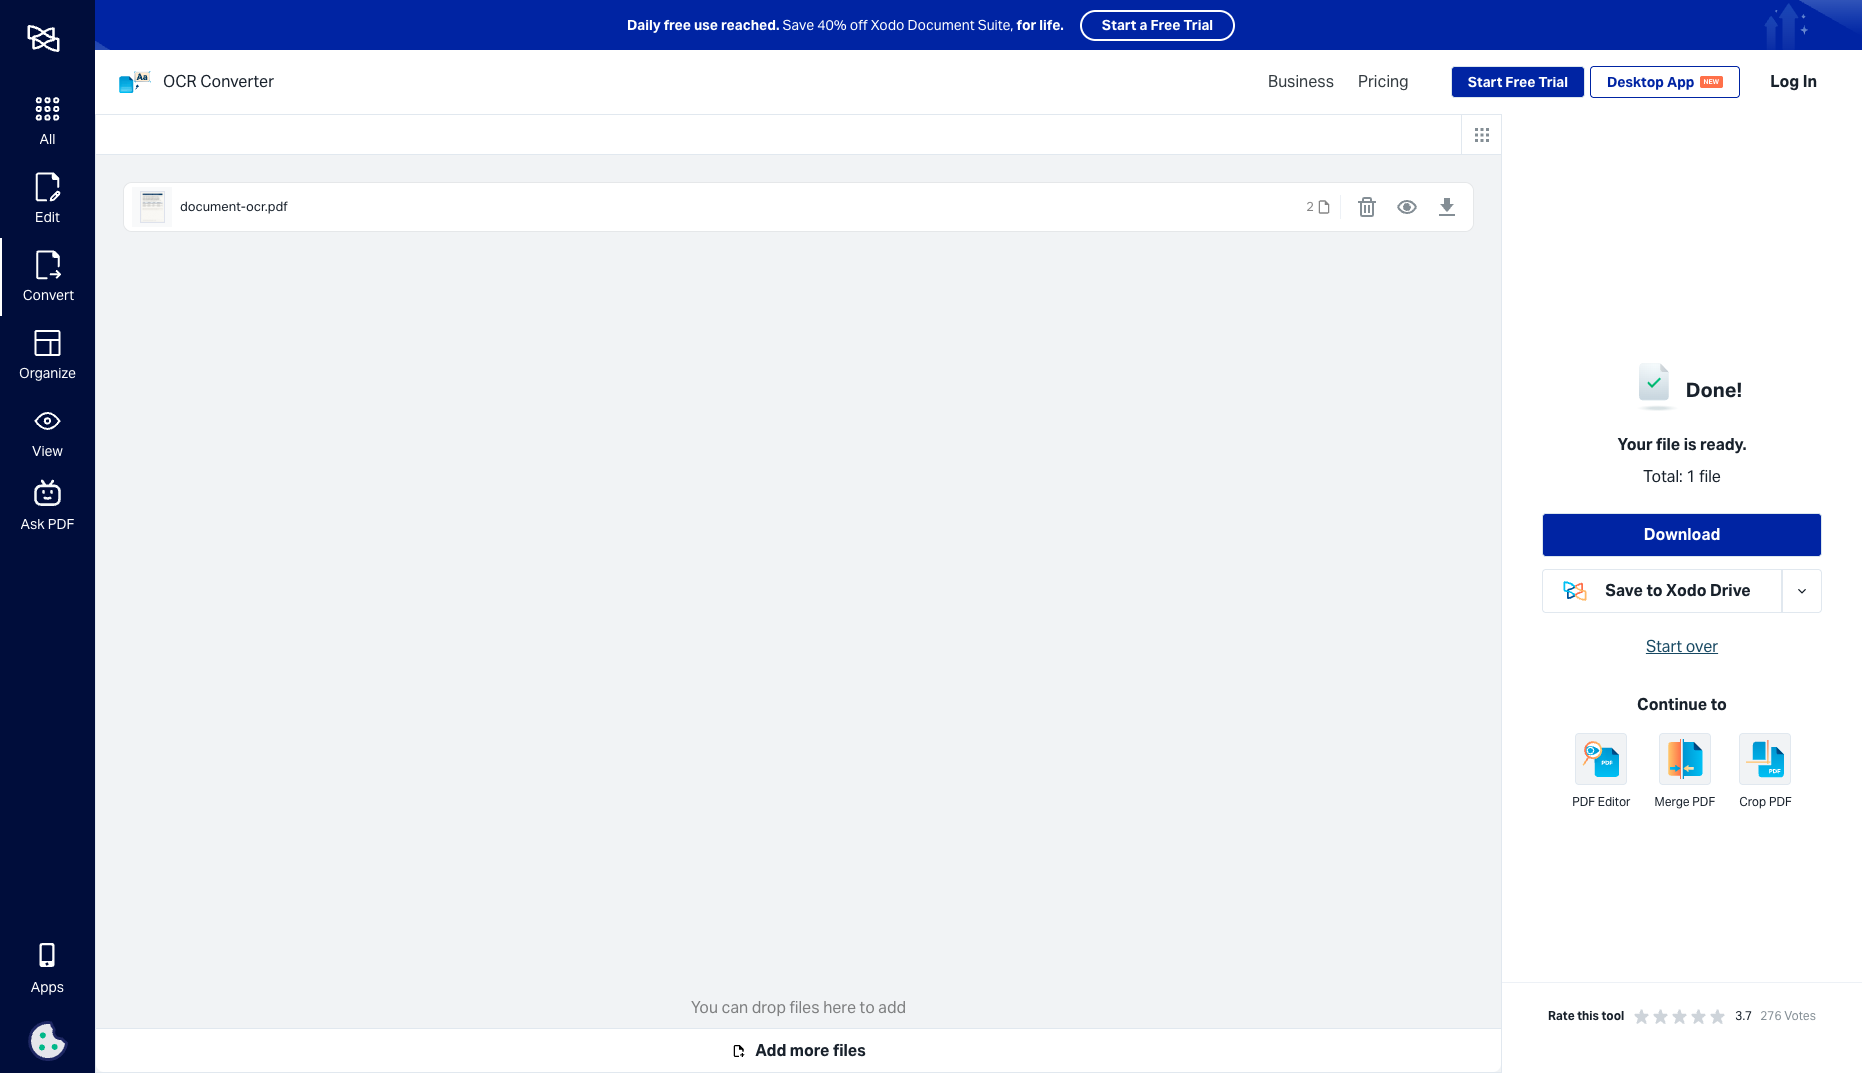
Converts our 2-page raster scan into a 2-page searchable PDF without login with 100% recall across all 4 headings and 12 confusable invoice table cells, though re-rendering inflates file size to 3,037.5 KB and takes 29.38s end-to-end (10.32s server OCR).

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (16 BT / 241 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Original historical observation

Generated a 2-page searchable PDF (16 BT / 241 TJ text operators) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (3037.5 KB · 16 BT / 241 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 29.38s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 10.32s · End-to-end reference: 29.38s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Provides multi-language OCR dictionary selection and automatic Deskew options, offering a direct login-free Download button on the result page alongside a Pro upgrade card.

Evidence & scope →

Background & reputation

QaamGo Web GmbH (pdf2go.com) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

QaamGo Web GmbH (pdf2go.com)

Recorded origin

Radolfzell, Germany

Domain history record

2016–Present (10-year German online PDF platform)

Background & reputation assessment

Operated in Radolfzell, Germany by QaamGo Web GmbH (parent company of Img2Go and Online-Convert) under EU data compliance standards.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 24 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

End-to-end HTTPS transport with 24-hour automatic file deletion and an instant manual delete button on the result page.

Retention statement

Claims deletion within 24 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

PDF2Go USD single-user plans and education eligibility plan · 2026-10-20

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free Up to 50 MB without registration; limited processing, no batching; exact count not listed.
USD 8/month
USD 77/year
Monthly 64 GB files, batching, priority queue; 1× AI allowance
Annual 64 GB files, batching, priority queue; 1× AI allowance
USD 29/month
USD 278/year
Monthly 64 GB files, batching, higher priority; 5× AI allowance
Annual 64 GB files, batching, higher priority; 5× AI allowance
USD 89/month
USD 854/year
Monthly Per-person price; custom limits and centralized billing; 20× AI allowance
Annual Per-person price; custom limits and centralized billing; 20× AI allowance
Education eligibility plan2026-10-20 ↗
Free
Free
Free School-email verification; non-commercial educational use only, renewable while eligible.

8 plan / billing-period records, all listed; — means that period is not recorded.

The annual view explicitly shows full-year USD 77/278/854; old monthly equivalents are not extrapolated. Paid plans use shared credits without full PDF credit rules here, so no file-count conversion is made.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

The page states cancel anytime and a 14-day money-back guarantee; eligibility is subject to official refund terms.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Allowance & disclosure on test date

Free Daily Credits + QaamGo Pro Subscription ($6.50/mo)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 90.7/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 83/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency26 / 35 Converts our 2-page raster scan into an unwatermarked 2-page searchable PDF without login (01_landing.png, 02_workspace.png, 03_download.png); free guests are subject to credit and file-size limits, with batch OCR requiring Pro (~$6.50/mo). Evidence A →
Interaction restraint25 / 30 Provides multi-language OCR dictionary selection and automatic Deskew options, offering a direct login-free Download button on the result page alongside a Pro upgrade card. Evidence A →
Background & reputation18 / 20 Operated in Radolfzell, Germany by QaamGo Web GmbH (parent company of Img2Go and Online-Convert) under EU data compliance standards. Evidence A →
Engineering & privacy14 / 15 End-to-end HTTPS transport with 24-hour automatic file deletion and an instant manual delete button on the result page. Evidence A →

Capability · 94/100 · 70%

CriterionScoreRationaleBasis
Task quality65 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (16 BT / 241 TJ operators) over the 644.4 KB zero-font raster scan, recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (65/65) Evidence A →
Deliverable specifications18 / 20 Exports a complete 2-page watermark-free searchable PDF (3037.5 KB) without login (18/20) Evidence A →
Processing speed11 / 15 Upload took 19.06s and cloud OCR server processing completed in 10.32s (29.38s end-to-end) (11/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
xodo.com · Scanned PDF OCR

90/100
Seven-aspect task score

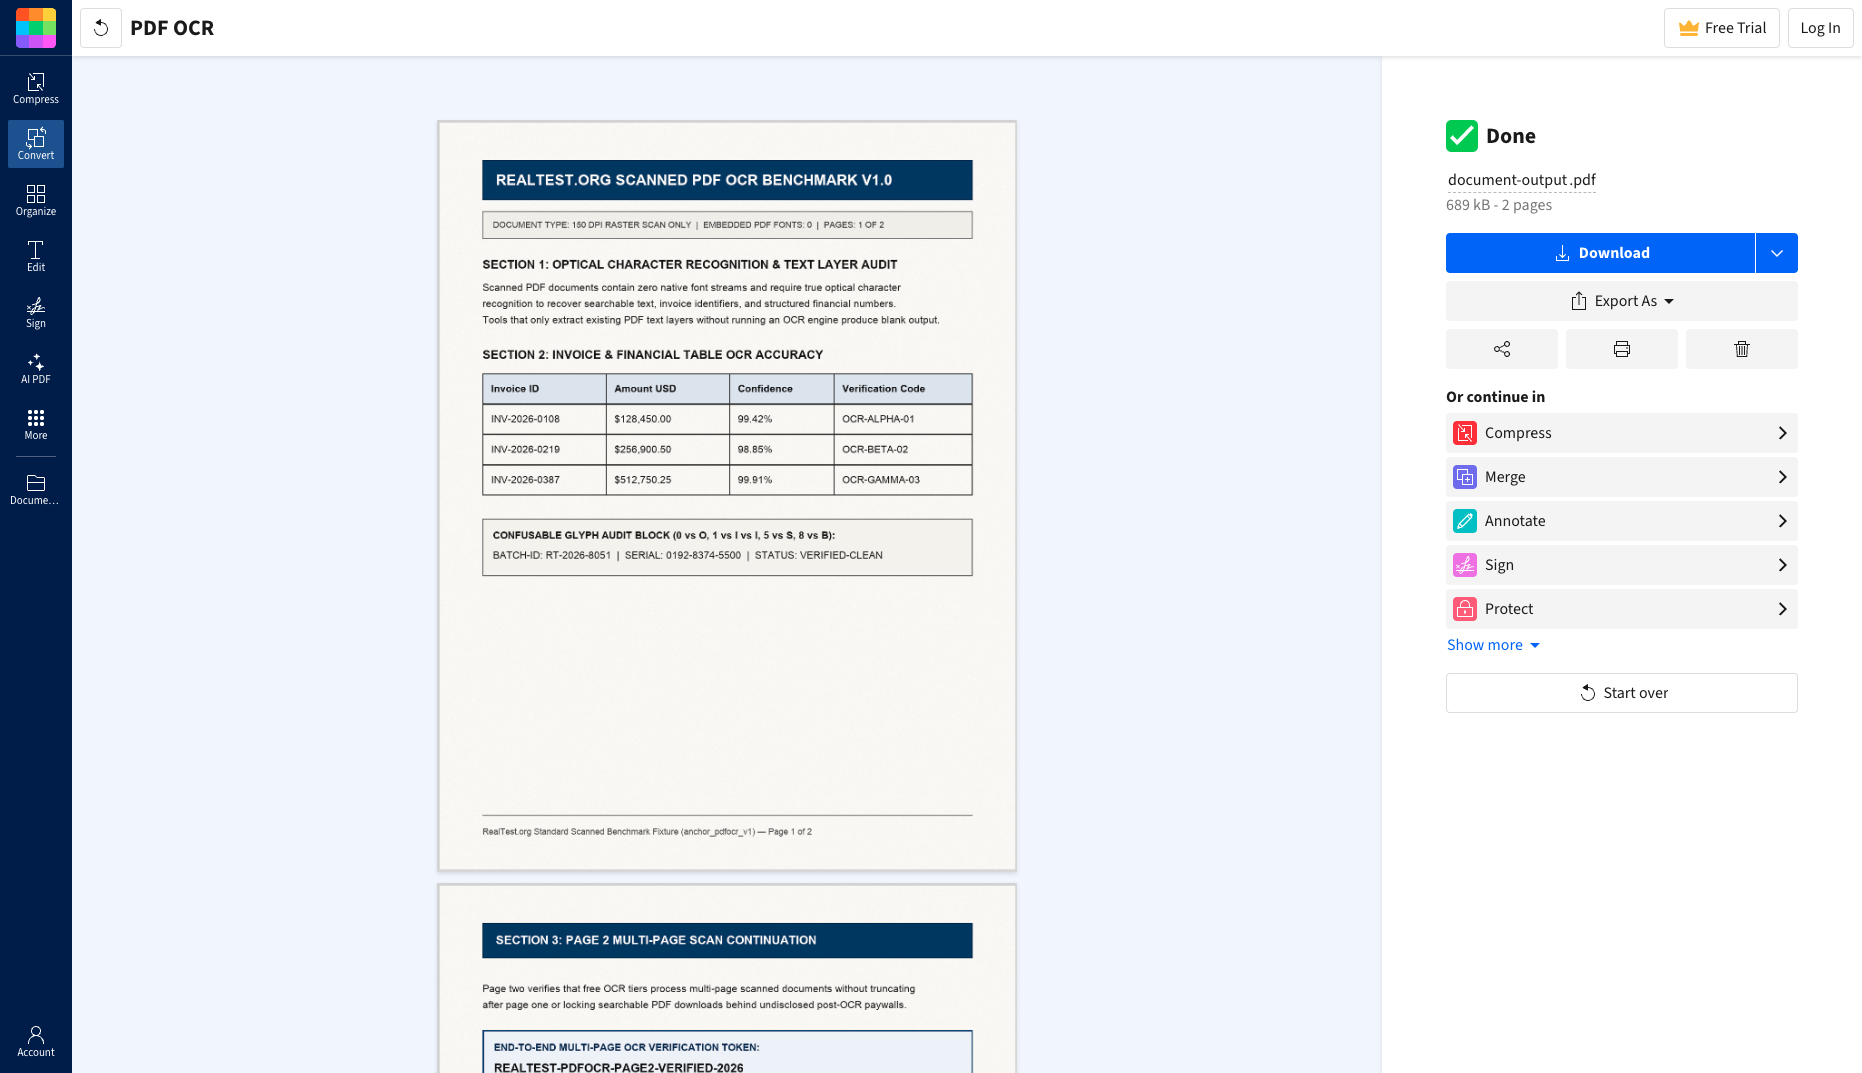
Powered by Apryse (PDFTron) cloud OCR with 1 free daily task without login, exporting a 687.6 KB 2-page searchable PDF in 5.00s; achieves 100% accuracy on body text and all 12 confusable invoice table cells, though binarization skips the two white-on-navy top banners (88.9% overall text recall).

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 88.9% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 88.9% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (456 BT / 456 TJ text operators) with 12/12 invoice table cells, 2/2 body phrases, and the Page 2 verification token intact, skipping only the 2 dark-background white-text header banners (88.9% text recall).

Original historical observation

Generated a 2-page searchable PDF (456 BT / 456 TJ text operators) with 12/12 invoice table cells, 2/2 body phrases, and the Page 2 verification token intact, skipping only the 2 dark-background white-text header banners (88.9% text recall).

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (687.6 KB · 456 BT / 456 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 8.72s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 5s · End-to-end reference: 8.72s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required (1 Free Daily Task)

Manual adjustment

Not verified

Interaction observations

Clean professional workspace supporting .pdf or .txt output format and language selection with zero third-party ad popups.

Evidence & scope →

Background & reputation

Apryse Software Corp. (formerly PDFTron Systems Inc.) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Apryse Software Corp. (formerly PDFTron Systems Inc.)

Recorded origin

Vancouver, Canada / Denver, USA

Domain history record

Xodo launched in 2014 (parent company PDFTron founded in 1998)

Background & reputation assessment

Developed and operated in Vancouver, Canada by enterprise PDF SDK leader Apryse (formerly PDFTron Systems Inc.), powered by the commercial Apryse OCR module.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 1 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

Uses encrypted AWS S3 direct upload and stateless `/production/ocr` processing endpoints with automatic temporary file purge.

Retention statement

Claims deletion within 1 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

Xodo USD individual web and cross-platform suite; desktop alternative identified · 2026-10-20

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Web free allowance2026-10-20 ↗
Free
Free
Free 1 action/day with limited access to web tools.
USD 10.99/month
USD 95.88/year
Monthly 40+ web tools and unlimited document downloads Rules [1]
Annual 40+ web tools and unlimited document downloads Rules [1]
Xodo Document Suite2026-10-20 ↗
USD 24.99/month
USD 107.93/year
Monthly Web, desktop and mobile bundle with unlimited web use Rules [1]
Annual Web, desktop and mobile bundle with unlimited web use Rules [1]
Xodo Desktop · PDF Studio2026-10-20 ↗
USD 19.99/month
USD 119.88/year
Monthly Desktop alternative, not web access Rules [1]
Annual Desktop alternative, not web access Rules [1]
Web / suite trial2026-10-20 ↗
Free trial
Trial
Trial 3 days; valid payment method required, cancellable during the trial.
Custom team plan2026-10-20 ↗
Contact sales
Quoted
Quoted Price varies by app bundle, seats and billing cycle; not all combinations verified.

9 plan / billing-period records, all listed; — means that period is not recorded.

[1] Annual plans charge the full year upfront; see verification notes for suite promotional eligibility

Monthly and annual bills confirmed. Document Suite USD 107.93/year is a new-annual-subscription promotion through 2026-12-31, retained while the annual subscription stays active. Team seat combinations and desktop perpetual licences were not exhaustively checked.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

Monthly subscriptions can be cancelled anytime; trials require a valid payment method. Refund terms were not fully verified.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Allowance & disclosure on test date

1 Free Task/Day + Xodo Pro Subscription ($12/mo)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 89.5/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 82/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency24 / 35 Allows 1 free daily PDF OCR task without login (01_landing.png, 02_workspace.png, 03_download.png), completing server OCR on our 644.4 KB 2-page raster scan in 5.00s and exporting an unwatermarked 2-page searchable PDF before enforcing the 1-file/day cap (Xodo Pro ~$12/mo). Evidence A →
Interaction restraint25 / 30 Clean professional workspace supporting .pdf or .txt output format and language selection with zero third-party ad popups. Evidence A →
Background & reputation19 / 20 Developed and operated in Vancouver, Canada by enterprise PDF SDK leader Apryse (formerly PDFTron Systems Inc.), powered by the commercial Apryse OCR module. Evidence A →
Engineering & privacy14 / 15 Uses encrypted AWS S3 direct upload and stateless `/production/ocr` processing endpoints with automatic temporary file purge. Evidence A →

Capability · 92.7/100 · 70%

CriterionScoreRationaleBasis
Task quality61.7 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (456 BT / 456 TJ operators) over the 644.4 KB zero-font raster scan, recovering 2/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 88.9% overall text recall) with the Page 2 verification token intact (61.7/65) Evidence A →
Deliverable specifications17.5 / 20 Exports a complete 2-page watermark-free searchable PDF (687.6 KB) without login (17.5/20) Evidence A →
Processing speed13.5 / 15 Upload took 2.15s and cloud OCR server processing completed in 5s (8.72s end-to-end) (13.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.

smallpdf.com · Scanned PDF OCR

89/100
Seven-aspect task score

Unlocks free PDF OCR without login, completing server OCR in 10.41s to export a 689.4 KB 2-page searchable PDF via its PDFTron OCR engine; achieves 100% accuracy across all 12 confusable invoice table cells and body text while skipping the two white-on-navy top header banners (88.9% overall text recall).

Tested export PDF · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 88.9% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 88.9% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Generated a 2-page searchable PDF (456 BT / 456 TJ text operators) with 12/12 invoice table cells, 2/2 body phrases, and the Page 2 verification token intact, skipping only the 2 dark-background white-text header banners (88.9% text recall).

Original historical observation

Generated a 2-page searchable PDF (456 BT / 456 TJ text operators) with 12/12 invoice table cells, 2/2 body phrases, and the Page 2 verification token intact, skipping only the 2 dark-background white-text header banners (88.9% text recall).

Suitable uses · historical assessment

Users needing to turn image-only scanned PDFs into Ctrl+F searchable PDFs with selectable invoice IDs and financial table figures

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (689.4 KB · 456 BT / 456 TJ · watermark-free)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 13.07s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 10.41s · End-to-end reference: 13.07s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Automatically runs cloud OCR upon upload and presents an interactive 2-page selectable text preview with a clear Download button and zero ad popups.

Evidence & scope →

Background & reputation

Smallpdf AG · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Smallpdf AG

Recorded origin

Zurich, Switzerland

Domain history record

2013–Present

Background & reputation assessment

Operated in Zurich, Switzerland by Smallpdf AG since 2013 with ISO/IEC 27001 certification and GDPR compliance.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 1 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

End-to-end TLS encryption with automatic 1-hour server file purge.

Retention statement

Claims deletion within 1 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

Smallpdf USD web individual and team plans; default 2-seat team bill · 2026-10-20

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free Daily downloads and file size are limited, without exact figures; PDF-to-Word OCR is a Pro feature.
USD 15/month
USD 120/year
Monthly 1 user; unlimited document downloads; OCR and text editing.
Annual 1 user; actual annual bill USD 120; unlimited downloads with OCR.
Team · 2 seats2026-10-20 ↗
USD 24/month
USD 192/year
Monthly 2-seat total; USD 12/seat/month; supports 2–19 seats.
Annual 2-seat annual total USD 192; shown equivalent USD 8/seat/month; supports 2–19 seats.
Contact sales
Quoted
Quoted 20+ users, contact sales; centralized management.
Free trial
Trial
Trial 7-day trial; verify billing conditions before starting.

7 plan / billing-period records, all listed; — means that period is not recorded.

Current USD web prices show actual annual bills. Team entries use the default 2-seat total and identify the per-seat rate. The free daily allowance is not quantified.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

FAQ says the trial can be cancelled without charge, reverting to Free at the end of 7 days. Paid refund details were not verified.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Allowance & disclosure on test date

Free Daily Task Quota + Smallpdf Pro ($12/mo)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 88.7/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 84/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency25 / 35 Now unlocks PDF OCR without login or trial sign-up (01_landing.png, 02_result.png, 03_download.png): uploading our 644.4 KB 2-page raster scan completes server OCR in 10.41s and downloads a 689.4 KB unwatermarked 2-page searchable PDF; free guests face daily task caps before Pro (~$12/mo). Evidence A →
Interaction restraint26 / 30 Automatically runs cloud OCR upon upload and presents an interactive 2-page selectable text preview with a clear Download button and zero ad popups. Evidence A →
Background & reputation19 / 20 Operated in Zurich, Switzerland by Smallpdf AG since 2013 with ISO/IEC 27001 certification and GDPR compliance. Evidence A →
Engineering & privacy14 / 15 End-to-end TLS encryption with automatic 1-hour server file purge. Evidence A →

Capability · 90.7/100 · 70%

CriterionScoreRationaleBasis
Task quality61.7 / 65 Deterministic searchable PDF stream & table inspection: reconstructs a 2-page selectable text layer (456 BT / 456 TJ operators) over the 644.4 KB zero-font raster scan, recovering 2/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 88.9% overall text recall) with the Page 2 verification token intact (61.7/65) Evidence A →
Deliverable specifications18 / 20 Exports a complete 2-page watermark-free searchable PDF (689.4 KB) without login (18/20) Evidence A →
Processing speed11 / 15 Upload took 1.34s and cloud OCR server processing completed in 10.41s (13.07s end-to-end) (11/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
pdfcandy.com · Scanned PDF OCR

87/100
Seven-aspect task score

Offers 1 free OCR task per hour without login, recovering 100% of all 4 headings, 12 confusable invoice table cells, and the Page 2 verification token in 8.99s, but exports only a plain-text `.txt` file (1.6 KB) rather than a layout-preserving searchable `.pdf`.

Tested export TXT · Output attached

Historical test · 2026-10-25
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Exported a 1.6 KB UTF-8 plain-text `.txt` file (not a searchable PDF) with 100% recall across all 4 headings, 12 invoice table cells, and the Page 2 verification token.

Original historical observation

Exported a 1.6 KB UTF-8 plain-text `.txt` file (not a searchable PDF) with 100% recall across all 4 headings, 12 invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to extract scanned PDFs into editable .txt text with 100% financial table number accuracy

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

TXT · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

TXT · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page UTF-8 plain text .txt (1.6 KB · not searchable PDF)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 13.13s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 8.99s · End-to-end reference: 13.13s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Clean ad-free interface with multi-language OCR selection and a direct "Download file" button upon completion.

Evidence & scope →

Background & reputation

Icecream Apps Ltd. (PDF Candy) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Icecream Apps Ltd. (PDF Candy)

Recorded origin

Cyprus (European software team)

Domain history record

2016–Present (10-year PDF utility suite)

Background & reputation assessment

Developed and operated by Icecream Apps Ltd (Cyprus) since 2016 alongside its desktop and web document utility suite.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Claims deletion within 2 hours; deletion not independently verified

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

End-to-end HTTPS transport with 2-hour automatic file purge and a manual delete button on the result screen.

Retention statement

Claims deletion within 2 hours; deletion not independently verified

Evidence & scope →

Pricing & rules

PDF Candy USD web and desktop + web bundles · 2026-10-21

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free No account; page, hourly and file-size limits; no batching. Numeric limits are not listed.
Web Monthly2026-10-20 ↗
USD 6/month
—
Monthly Monthly web-tool subscription; up to 500 MB/task, no hourly limits, and high-priority processing.
Desktop + Web Yearly2026-10-20 ↗
—
USD 48/year
Annual Billed annually at USD 48.00/year (displayed as USD 4/month equivalent); includes 500 MB/task, no hourly limits, web and desktop access, plus Video Candy and Image Candy web.

Billed annually via Paddle at US$48.00/year (applicable taxes calculated at checkout)

Desktop + Web Lifetime2026-10-20 ↗
USD 99 · one-time payment
Usage / one-time
Usage / one-time One payment; desktop perpetual licence is limited to the current major version, including minor updates.

4 plan / billing-period records, all listed; — means that period is not recorded.

Confirmed USD 6 monthly, USD 48 yearly (card displays promotional USD 4/month equivalent; verified at USD 48.00/year in the Paddle checkout modal after login on 2026-10-21), and USD 99 one-time. Lifetime covers the licensed version and minor updates, not future major upgrades.

Cancellation, sources & verification record

The page mentions 30-day refunds but also conditions them on recurring unresolved errors; eligibility follows the refund policy. Cancellation retains access through the paid period.

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Official feature and pricing page ↗ · 2026-10-20 Capture 1 ↗

Logged-in pricing page and Paddle checkout annual bill verification ↗ · 2026-10-21 Capture 1 ↗

Allowance & disclosure on test date

1 Free Task/Hour + Pro Subscription ($6/mo)

Options disclosed upfront with no post-OCR paywall trap

Evaluation basis & full scores · Overall 86.9/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 82/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency26 / 35 Offers free PDF OCR without login (1 free task per hour), completing server OCR on our 644.4 KB 2-page raster scan in 8.99s with direct download (01_landing.png, 02_workspace.png, 03_download.png); note that it exports a plain-text `.txt` file (1.6 KB) rather than an overlaid searchable `.pdf`. Evidence A →
Interaction restraint26 / 30 Clean ad-free interface with multi-language OCR selection and a direct "Download file" button upon completion. Evidence A →
Background & reputation17 / 20 Developed and operated by Icecream Apps Ltd (Cyprus) since 2016 alongside its desktop and web document utility suite. Evidence A →
Engineering & privacy13 / 15 End-to-end HTTPS transport with 2-hour automatic file purge and a manual delete button on the result screen. Evidence A →

Capability · 89/100 · 70%

CriterionScoreRationaleBasis
Task quality62.5 / 65 Deterministic OCR text & table inspection: exports a 1.6 KB .txt file (rather than an overlaid searchable PDF), recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (62.5/65) Evidence A →
Deliverable specifications15 / 20 Exports a 2-page watermark-free .txt file (1.6 KB) without login rather than a layout-preserving searchable PDF (15/20) Evidence A →
Processing speed11.5 / 15 Upload took 4.14s and cloud OCR server processing completed in 8.99s (13.13s end-to-end) (11.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
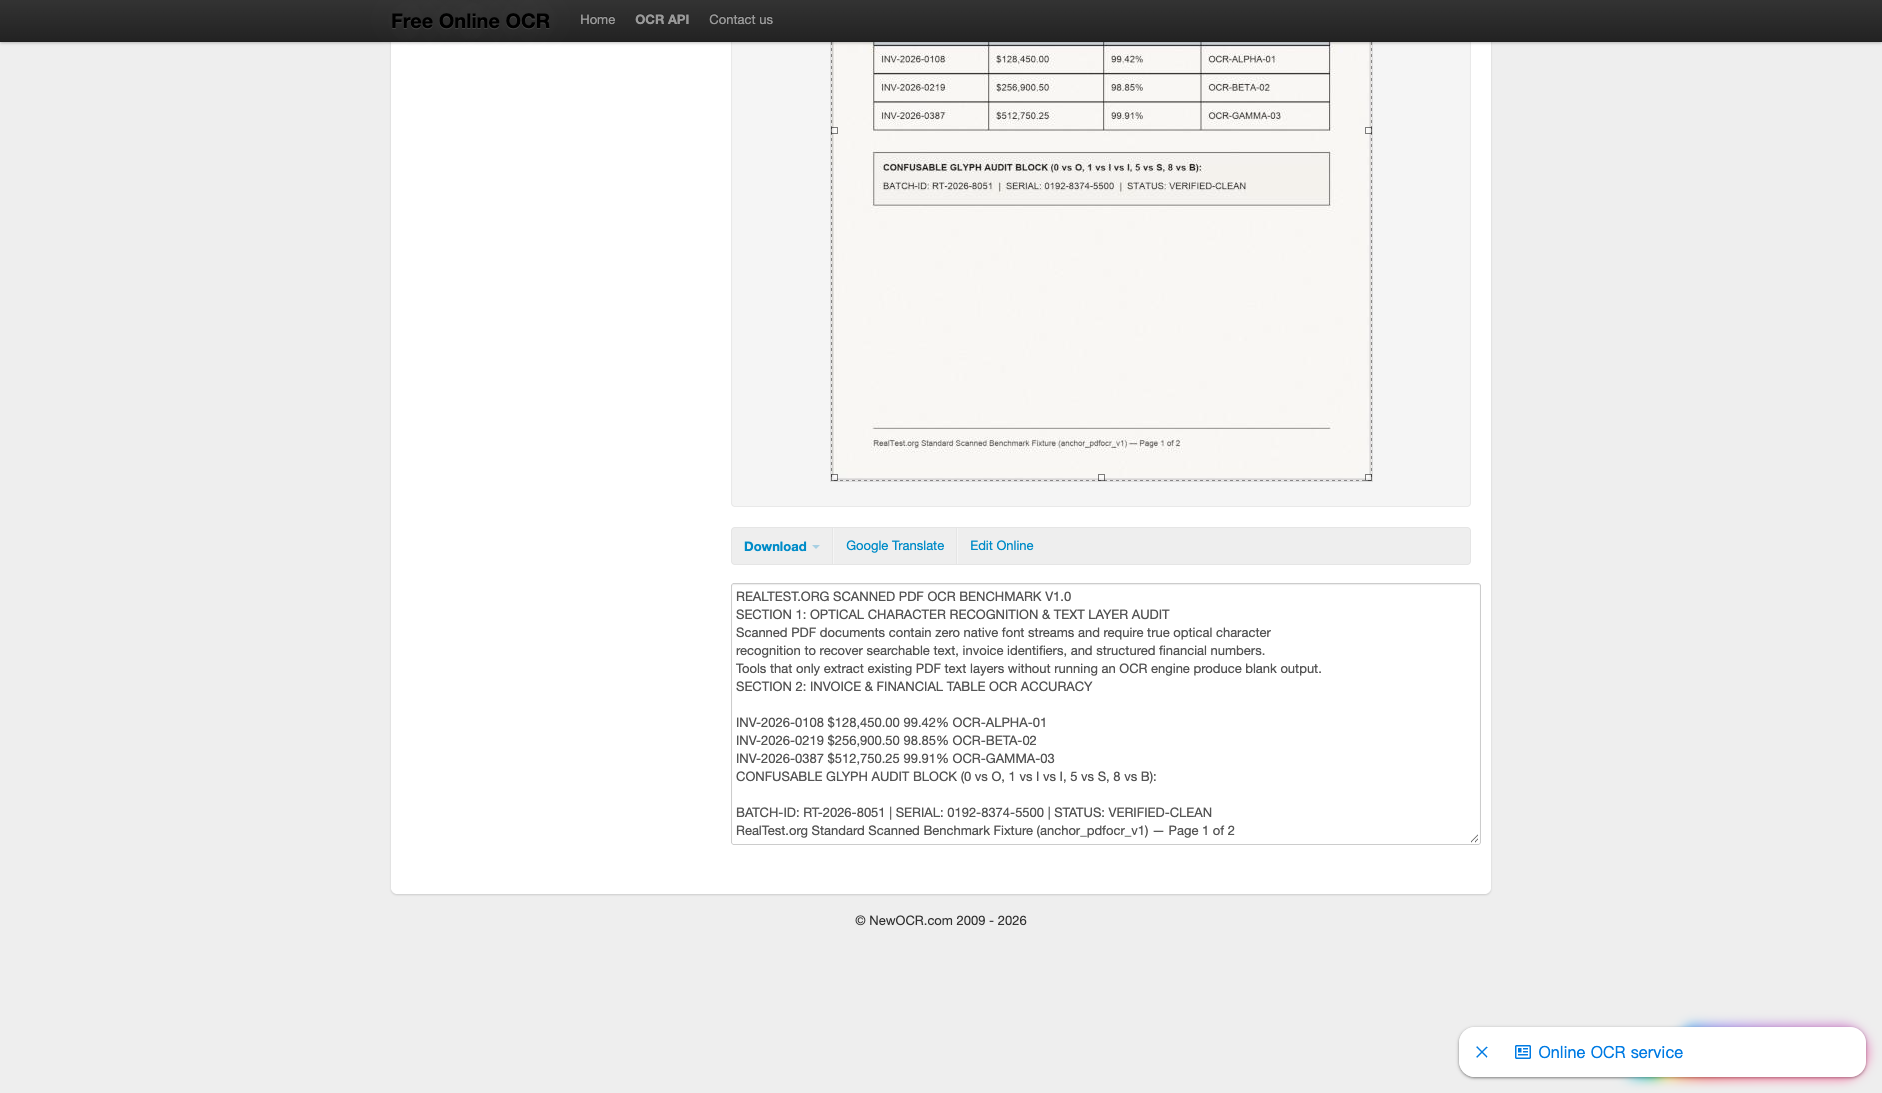
lightpdf.com · Scanned PDF OCR

82/100
Seven-aspect task score

Requires a free account login to run basic OCR exporting a 2-page `.docx` (11.3 MB, 26.61s server wait) with 100% recall across all 4 headings and 12 confusable invoice table cells, while Searchable `.pdf` export is locked behind VIP.

Tested export DOCX · Output attached

Historical test · 2026-10-25
Signed-in flow; paid tier not standardized · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 100% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 100% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Exported a 2-page `.docx` document (11,307.6 KB, not a searchable PDF) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Original historical observation

Exported a 2-page `.docx` document (11,307.6 KB, not a searchable PDF) with 100% recall across 4/4 headings, 12/12 invoice table cells, and the Page 2 verification token.

Suitable uses · historical assessment

Users needing to extract scanned PDFs into editable .docx text with 100% financial table number accuracy

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

DOCX · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

DOCX · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page editable Word .docx (11307.6 KB · not searchable PDF)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 29.77s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 26.61s · End-to-end reference: 29.77s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

Login required in this run

Detailed facts & historical record
Account requirements

Account required in this test

Sign-in methods

Free Account Login Required

Manual adjustment

Not verified

Interaction observations

Free tier defaults to Standard OCR -> Word (`.docx`), while selecting "Searchable PDF" format triggers a VIP upgrade modal.

Evidence & scope →

Background & reputation

AI Document Tool Suite (Wangxu Tech / Apowersoft) · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

AI Document Tool Suite (Wangxu Tech / Apowersoft)

Recorded origin

Jurisdiction not publicly specified

Domain history record

Publicly operating online service

Background & reputation assessment

Developed and operated by Hong Kong-based Wangxu Technology (Apowersoft), offering web and desktop PDF utilities.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

Processes files via Alibaba Cloud Hong Kong OSS (`oss-cn-hongkong.aliyuncs.com`) and `gw.aoscdn.com` async task queues tied to a user account.

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

LightPDF Individual Free, Monthly, Annual and Perpetual plans; Team & Business and Education tabs priced separately · 2026-10-21

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free
Free
Free Web only; max file size 10 MB, 1-year cloud storage for up to 5 files; downloading converted DOCX requires signing in to a free account
Monthly Plan2026-10-21 ↗
USD 19.99/month
—
Monthly 1-month full access to all PDF tools across Web, Mobile and Desktop, unlimited file size, plus 1,000 AI credits/month

Promotional price USD 19.99/month (strikethrough USD 29.99), billed monthly, cancel anytime;Unused AI credits expire monthly

Annual Plan2026-10-21 ↗
—
USD 49.99/year
Annual 1-year full access to all PDF tools across 5 platforms (1 active device at a time), unlimited file size, plus 1,000 AI credits/month

3-day free trial then USD 49.99/year (strikethrough USD 89.99; skipping trial saves USD 5);1,000 AI credits per month expire monthly

Perpetual Plan (Lifetime)2026-10-21 ↗
USD 109.99 · one-time payment
Usage / one-time
Usage / one-time One-time payment for lifetime access to all PDF tools across 5 platforms, unlimited file size, plus 40,000 AI credits

40,000 AI credits granted instantly and valid until used

4 plan / billing-period records, all listed; — means that period is not recorded.

Individual pricing lists Free, Monthly USD 19.99, Annual USD 49.99 (with 3-day trial or $5 skip-trial discount), and Perpetual USD 109.99; per-feature AI credit deductions require hover tooltips and enterprise plans require custom quotes.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

Cancel recurring subscriptions via support ticket or payment platform email link; money-back guarantee is 30 days for Perpetual, 7 days for Annual, and 3 days for Monthly.

LightPDF official Individual pricing page ↗ · 2026-10-21 Capture 1 ↗

Allowance & disclosure on test date

Mandatory Login + Free DOCX/TXT Export (Searchable PDF Requires VIP)

Prompts for free account login before or upon download

Evaluation basis & full scores · Overall 81.9/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 70/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency21 / 35 Requires signing into a free account before use (01_landing.png, 02_workspace.png); the free tier unlocks Standard OCR exporting to `.docx` or `.txt` (Searchable PDF output and high-accuracy layout mode require paid Credits / VIP), completing server OCR in 26.61s (03_download.png). Evidence A →
Interaction restraint20 / 30 Free tier defaults to Standard OCR -> Word (`.docx`), while selecting "Searchable PDF" format triggers a VIP upgrade modal. Evidence A →
Background & reputation17 / 20 Developed and operated by Hong Kong-based Wangxu Technology (Apowersoft), offering web and desktop PDF utilities. Evidence A →
Engineering & privacy12 / 15 Processes files via Alibaba Cloud Hong Kong OSS (`oss-cn-hongkong.aliyuncs.com`) and `gw.aoscdn.com` async task queues tied to a user account. Evidence A →

Capability · 87/100 · 70%

CriterionScoreRationaleBasis
Task quality64 / 65 Deterministic OCR text & table inspection: exports a 11307.6 KB .docx file (rather than an overlaid searchable PDF), recovering 4/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 100% overall text recall) with the Page 2 verification token intact (64/65) Evidence A →
Deliverable specifications15.5 / 20 Exports a 2-page watermark-free .docx file (11307.6 KB) with a free account rather than a layout-preserving searchable PDF (15.5/20) Evidence A →
Processing speed7.5 / 15 Upload took 3.16s and cloud OCR server processing completed in 26.61s (29.77s end-to-end) (7.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
newocr.com · Scanned PDF OCR

78/100
Seven-aspect task score

NewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Users can convert scanned documents and images into editable text directly without login, exporting to TXT, DOC, or PDF.

Tested export TXT · Output attached

Historical test · 2026-11-02
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 88.9% · Table cell accuracy 100% · Page 2 preserved No

Detailed facts & historical record
Measured fixture results

OCR text recall: 88.9% · Table cell accuracy: 100% · Page 2 preserved: No

Fixture findings

Based on our standardized 2-page scanned PDF benchmark (anchor_pdfocr_v1): cloud OCR completed in just 0.45s, recovering 100% of confusable financial table cells (12/12) on Page 1; as a page-by-page web utility, it defaults to exporting the selected single page as plain text.

Original historical observation

In-browser text area displays extracted text with one-click TXT, DOC, and PDF downloads; invoice table numbers 100% accurate.

Suitable uses · historical assessment

Users seeking a fast, zero-login online tool to accurately extract tables and text from single scanned pages

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

TXT · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

TXT · Output attached · No watermark in test

Historical specification note · not an official maximum

Single-page UTF-8 plain text .txt (802 bytes · 100% table accuracy)

Watermark observation

Watermark-free

Batch & API

Web tool supports single files or ZIP archives; REST API available for developers

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 1.3s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 0.45s · End-to-end reference: 1.3s

Date & fixture

2026-11-02 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

No Login Required

Manual adjustment

Not verified

Interaction observations

Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR.

Evidence & scope →

Background & reputation

NewOCR.com · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

NewOCR.com

Recorded origin

United States / International

Domain history record

Founded in 2011

Background & reputation assessment

Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

Google AdSense · Google Analytics

Engineering & privacy assessment

HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button.

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

NewOCR 100% free web service and developer REST API credits · 2026-11-02

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free Web Service2026-10-31 ↗
Free
Free
Free Zero login required, unlimited file uploads, supports single and multi-page documents and ZIP archives

Tesseract OCR text extraction across 122 languages, math formulas, layout analysis; export TXT/DOC/PDF;Ad-supported; processing speed subject to public server queues

Developer API Credits2026-10-31 ↗
USD 5 · one-time payment
Usage / one-time
Usage / one-time 1,000 OCR API recognition calls ($0.005 per call)

Automated batch processing via REST API endpoints returning structured JSON data;Programmatic developer interface requiring an API key

2 plan / billing-period records, all listed; — means that period is not recorded.

Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages).

Cancellation, sources & verification record

Cancellation and refund terms unverified

NewOCR API & Pricing ↗ · 2026-10-31 Capture 1 ↗

Allowance & disclosure on test date

100% Free Unlimited Use (Ad-supported)

Download options presented upfront without post-OCR paywalls

Evaluation basis & full scores · Overall 78.1/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 79/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency33 / 35 Web service is 100% free with unlimited uploads and zero hidden fees; developer API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages). Evidence A →
Interaction restraint20 / 30 Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR. Evidence A →
Background & reputation16 / 20 Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base. Evidence A →
Engineering & privacy10 / 15 HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button. Evidence A →

Capability · 77.7/100 · 70%

CriterionScoreRationaleBasis
Task quality49.2 / 65 Deterministic OCR inspection: exported an 802-byte UTF-8 plain text deliverable without login, recovering 12/12 confusable financial table cells on Page 1 (100% table accuracy) and 3/4 headings; defaults to single-page processing without auto-merging Page 2 (49.2/65) Evidence A →
Deliverable specifications14 / 20 Direct download in TXT, DOC, and PDF formats without login, delivering the selected single page extracted text (802 bytes) rather than a combined 2-page searchable PDF (14/20) Evidence A →
Processing speed14.5 / 15 Cloud Tesseract OCR server processing completed in just 0.45s (1.30s end-to-end) (14.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
hipdf.com · Scanned PDF OCR

77/100
Seven-aspect task score

Blocks unauthenticated downloads after OCR completes with a mandatory login gate; signing into a free account exports an 8.3 KB 2-page `.docx` (19.75s server wait, not a searchable PDF) with 100% accuracy across all 12 confusable invoice table cells and the Page 2 token (77.8% strict substring recall due to Word auto-numbering on headings).

Tested export DOCX · Output attached

Historical test · 2026-10-25
Signed-in flow; paid tier not standardized · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 77.8% · Table cell accuracy 100% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 77.8% · Table cell accuracy: 100% · Page 2 preserved: Yes

Fixture findings

Exported an 8.3 KB 2-page `.docx` document (not a searchable PDF) with 100% accuracy across 12/12 confusable invoice table cells, 2/2 body phrases, and the Page 2 token; section prefixes `1.` / `2.` were converted to Word `<w:numPr>` auto-lists and `V1.0` became `VI .0` (77.8% strict substring match).

Original historical observation

Exported an 8.3 KB 2-page `.docx` document (not a searchable PDF) with 100% accuracy across 12/12 confusable invoice table cells, 2/2 body phrases, and the Page 2 token; section prefixes `1.` / `2.` were converted to Word `<w:numPr>` auto-lists and `V1.0` became `VI .0` (77.8% strict substring match).

Suitable uses · historical assessment

Users needing to extract scanned PDFs into editable .docx text with 100% financial table number accuracy

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

DOCX · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

DOCX · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page editable Word .docx (8.3 KB · not searchable PDF)

Watermark observation

Watermark-free

Batch & API

Single-file OCR on free tier; batch processing per plan quota

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 28.14s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Network-observed server wait: 19.75s · End-to-end reference: 28.14s

Date & fixture

2026-10-25 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

Login required in this run

Detailed facts & historical record
Account requirements

Account required in this test

Sign-in methods

Mandatory Wondershare Account Login at Download Step

Manual adjustment

Not verified

Interaction observations

Uses a post-OCR login wall at the final Download step after guests wait through upload and recognition, and only exports `.docx` / `.xlsx` / `.pptx` / `.txt` rather than an overlaid searchable `.pdf`.

Evidence & scope →

Background & reputation

Wondershare Online PDF Suite · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

Wondershare Online PDF Suite

Recorded origin

Jurisdiction not publicly specified

Domain history record

Publicly operating online service

Background & reputation assessment

Developed and operated by Wondershare Technology (creator of PDFelement).

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

Uploaded for cloud processing;Explicit retention period unconfirmed; inspect policy record

Detailed facts & historical record
Processing location

Uploaded for cloud processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

Processes files via `eus-storage.pdfelement.io` and `web-api.hipdf.com` async queues, requiring a Wondershare account and `pdf-equity` quota deduction to download.

Retention statement

Explicit retention period unconfirmed; inspect policy record

Evidence & scope →

Pricing & rules

HiPDF web online PDF to Word tool (former /pricing page now returns 404) · 2026-10-21

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Web free account2026-10-21 ↗
Free
Free
Free Convert and download DOCX after signing in to a free Wondershare account; numeric daily and file-size limits are not listed on the page (uploaded files deleted within 60 minutes)

1 plan / billing-period records, all listed; — means that period is not recorded.

The official tool page advertises free online conversion while /pricing returns 404 and header buttons promote desktop PDFelement; downloading the converted DOCX requires signing in to a free Wondershare account, and numeric daily or file-size limits are not published on the page.

Verification has gaps; unknown prices and quotas are not inferred.

Cancellation, sources & verification record

Cancellation and refund terms follow official checkout and help policies.

HiPDF official PDF to Word tool page ↗ · 2026-10-21 Capture 1 ↗

Allowance & disclosure on test date

Post-OCR Mandatory Login Gate + Wondershare Pro Subscription

Prompts for free account login before or upon download

Evaluation basis & full scores · Overall 77.4/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 67/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency19 / 35 Allows unauthenticated guests to upload our 644.4 KB 2-page raster scan and wait for 100% cloud OCR completion, then blocks the Download button with "You need to log in to download the file" (01_landing.png, 02_workspace.png, 02_result.png, 04_download.png); signing into a free Wondershare account exports the 8.3 KB `.docx` result. Evidence A →
Interaction restraint18 / 30 Uses a post-OCR login wall at the final Download step after guests wait through upload and recognition, and only exports `.docx` / `.xlsx` / `.pptx` / `.txt` rather than an overlaid searchable `.pdf`. Evidence A →
Background & reputation18 / 20 Developed and operated by Wondershare Technology (creator of PDFelement). Evidence A →
Engineering & privacy12 / 15 Processes files via `eus-storage.pdfelement.io` and `web-api.hipdf.com` async queues, requiring a Wondershare account and `pdf-equity` quota deduction to download. Evidence A →

Capability · 81.8/100 · 70%

CriterionScoreRationaleBasis
Task quality57.3 / 65 Deterministic OCR text & table inspection: exports a 8.3 KB .docx file (rather than an overlaid searchable PDF), recovering 0/4 headings and 12/12 confusable invoice table cells (100% table accuracy, 77.8% overall text recall) with the Page 2 verification token intact (57.3/65) Evidence A →
Deliverable specifications15 / 20 Exports a 2-page watermark-free .docx file (8.3 KB) with a free account rather than a layout-preserving searchable PDF (15/20) Evidence A →
Processing speed9.5 / 15 Upload took 8.39s and cloud OCR server processing completed in 19.75s (28.14s end-to-end) (9.5/15) Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.

copychecker.com · Scanned PDF OCR

67/100
Seven-aspect task score

CopyChecker runs client-side Tesseract.js WASM on /ocr-pdf, injecting a searchable text layer into a 2-page bilingual PDF in 6.30s without watermarks or server uploads (3.26 MB output). Section headings and cross-page tokens were accurately recognized, though dense financial grid cells were omitted. Requires Google OAuth for 2 daily free exports.

Tested export PDF · Output attached

Historical test · 2026-10-28
Guest flow · 2-page raster scanned PDF (0 embedded text, 644.4 KB) · Output attached

Seven-aspect rationale →

Task quality

OCR text recall 33.3% · Table cell accuracy 0% · Page 2 preserved Yes

Detailed facts & historical record
Measured fixture results

OCR text recall: 33.3% · Table cell accuracy: 0% · Page 2 preserved: Yes

Fixture findings

Retained 4/4 section headings, 2/2 body phrases, and page 2 verification token; dense financial table grid cells were not detected (0/12 cells), scoring 43.3/65 in task quality.

Original historical observation

Generated a 2-page searchable PDF (15 BT / 215 TJ text operators); headings and body text are selectable and searchable, though table digits were not extracted.

Suitable uses · historical assessment

Users needing fast client-side text layer injection into scanned PDFs without cloud uploads (dense tables not supported)

Result & output evidence

Open native output

Open result screenshotOpen result screenshot ↗

Full test record →

Evidence & scope →

Delivery capabilities

PDF · Output attached · No watermark in test

Detailed facts & historical record
Recorded export specifications

PDF · Output attached · No watermark in test

Historical specification note · not an official maximum

Full 2-page searchable PDF (3,188.1 KB · 15 BT / 215 TJ · zero watermark)

Watermark observation

Watermark-free

Batch & API

Single-file upload recognition with multi-page automatic batching

Recorded free-tier dimensions

Not verified

Attached file dimensions

Not verified

Evidence & scope →

Speed & reliability

About 6.3s end to end in this run; reliability not retested

Detailed facts & historical record
Timing observation

Recorded local processing time: 0s · End-to-end reference: 6.3s

Date & fixture

2026-10-28 · anchor_pdfocr_v1 · US-West (California, AS2914)

Repeated tests & reliability

No standardized repetition count, success rate or variability range is recorded.

Evidence & scope →

Interaction experience

No login in this run

Detailed facts & historical record
Account requirements

No login in this test

Sign-in methods

Guest usable or Google login for direct export

Manual adjustment

Not verified

Interaction observations

Clean workflow, though users must manually check the pages to recognize before clicking Recognize Text. The page footer and sidebar display third-party banner ads without obstructing the primary controls.

Evidence & scope →

Background & reputation

CopyChecker · Long-term reputation not independently verified

Detailed facts & historical record
Service lifecycle notice

Not verified

Operator

CopyChecker

Recorded origin

Global Online SaaS Platform

Domain history record

Provides online content analysis and lightweight PDF tools

Background & reputation assessment

SaaS utility platform focusing on plagiarism detection, AI writing analysis, and lightweight online PDF tools.

External reputation record

Not verified

Evidence & scope →

Engineering & privacy

On-device processing;This flow runs locally; post-close deletion not independently verified

Detailed facts & historical record
Processing location

On-device processing

Third-party tracking record

No third-party services listed in this record; this is not proof that none exist.

Engineering & privacy assessment

OCR processing and PDF text stream reconstruction run entirely within the client-side browser WASM and memory, with zero document bytes transmitted to cloud servers, providing excellent privacy.

Retention statement

This flow runs locally; post-close deletion not independently verified

Evidence & scope →

Pricing & rules

CopyChecker PDF Suite and Writing Suite plans; free online conversion and weekly/monthly subscriptions · 2026-10-28

Plan · source date
Monthly / one-time
Annual bill / period
Quota & limits
Free PDF Tools2026-10-28 ↗
Free
Free
Free Standard document conversion without login, no watermark
PDF Suite Weekly2026-10-28 ↗
USD 3.99/week
Other period
Other period Unlimited PDF conversions and downloads, ad-free and accelerated processing
PDF Suite Monthly2026-10-28 ↗
USD 13.99/month
—
Monthly Unlimited PDF conversions and downloads, ad-free, fast processing, and priority support

3 plan / billing-period records, all listed; — means that period is not recorded.

PDF suite tools are free without login (ad-supported, no watermarks); paid PDF Suite subscriptions cost $3.99/week or $13.99/month for ad-free, accelerated processing.

Cancellation, sources & verification record

Cancellation and refund terms unverified

CopyChecker official homepage ↗ · 2026-10-28 Capture 1 ↗

CopyChecker official pricing page (PDF Suite) ↗ · 2026-10-28 Capture 1 ↗

Allowance & disclosure on test date

Guest devices share cross-tool daily limits; logging in unlocks 2 free exports daily

Options disclosed upfront, with direct download provided upon processing

Evaluation basis & full scores · Overall 67.4/100

Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.

Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1

Honesty & reputation · 87/100 · 30%

CriterionScoreRationaleBasis
Pricing transparency30 / 35 Promoted as a 100% free online tool. Uploading the 644.4 KB 2-page scanned PDF without login finishes OCR recognition in 6.3s locally in the browser, popping up a results dialog that supports direct export in PDF and TXT formats. Unregistered devices share a daily limit across utilities; logging in provides 2 free exports per day. Evidence A →
Interaction restraint25 / 30 Clean workflow, though users must manually check the pages to recognize before clicking Recognize Text. The page footer and sidebar display third-party banner ads without obstructing the primary controls. Evidence A →
Background & reputation17 / 20 SaaS utility platform focusing on plagiarism detection, AI writing analysis, and lightweight online PDF tools. Evidence A →
Engineering & privacy15 / 15 OCR processing and PDF text stream reconstruction run entirely within the client-side browser WASM and memory, with zero document bytes transmitted to cloud servers, providing excellent privacy. Evidence A →

Capability · 59/100 · 70%

CriterionScoreRationaleBasis
Task quality25 / 65 Client-side WASM engine reconstructs a searchable PDF text layer (15 BT / 215 TJ operators), matching 4/4 section headings, 2/2 body phrases, and preserving the Page 2 verification token; however, dense table grid contents were omitted (0/12 confusable financial table cells, 0% table accuracy), resulting in 33.3% total text recall (25.0/65). Evidence A →
Deliverable specifications20 / 20 Exports a complete 2-page watermark-free searchable PDF (3,188.1 KB, with text layer) free of charge (20/20). Evidence A →
Processing speed14 / 15 Pure client-side browser WASM recognition with zero cloud data upload wait, end-to-end ready in 6.3s (14.0/15). Evidence A →

Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.

Tested tools withheld from Scanned PDF OCR ranking (6)

Factual blocker log · Unscored

These tools were tested using the same benchmark fixture for this topic, but hit a hard free-tier paywall / zero quota (B1) or backend error / missing standalone web entry (B2) before producing a verifiable free native export. They are listed here for transparency without speculative scores.

Mathpix PDF OCR (mathpix.com) B1 · Hard paywall / 0 free export quota

Tested on 2026-11-02 using benchmark fixture anchor_pdfocr_v1: blocked by a free-tier paywall, credit gate, or backend error before native file export. Withheld from scoring and ranking under the report contract.

Tested on: 2026-11-02 · View product profile & pricing baseline →

Nanonets (nanonets.com) B1 · Hard paywall / 0 free export quota

Tested on 2026-11-02 using benchmark fixture anchor_pdfocr_v1: blocked by a free-tier paywall, credit gate, or backend error before native file export. Withheld from scoring and ranking under the report contract.

Tested on: 2026-11-02 · View product profile & pricing baseline →

pdfFiller (pdffiller.com) B1 · Hard paywall / 0 free export quota

Tested on 2026-11-02 using benchmark fixture anchor_pdfocr_v1: blocked by a free-tier paywall, credit gate, or backend error before native file export. Withheld from scoring and ranking under the report contract.

Tested on: 2026-11-02 · View product profile & pricing baseline →

Nitro PDF (gonitro.com) B2 · Backend error / online entry unavailable

Tested on 2026-10-31 using benchmark fixture anchor_pdfocr_v1: blocked by a free-tier paywall, credit gate, or backend error before native file export. Withheld from scoring and ranking under the report contract.

Tested on: 2026-10-31 · View product profile & pricing baseline →

CleverPDF (cleverpdf.com) B2 · Backend error / online entry unavailable

Visiting /pdf-ocr returns HTTP 404, and inspecting all 44 online utilities confirmed that CleverPDF Web does not offer scanned PDF OCR.

Tested on: 2026-10-25 · View product profile & pricing baseline →

Soda PDF (sodapdf.com) B1 · Hard paywall / 0 free export quota

Uploading the 644.4 KB scanned PDF opens the web editor where both "Recognize text" and "Export file" carry paid lightning locks with no free OCR export.

Tested on: 2026-10-25 · View product profile & pricing baseline →

Scanned PDF OCR selection FAQ

Which scanned pdf ocr tools work without login or watermarks?

Out of 15 assessed tools, 13 exported watermark-free files without requiring an account on their test dates, led by PDF24 Tools (98/100, 2026-10-25), deftpdf.com (97/100, 2026-10-31), ocr.space (97/100, 2026-11-02). Use the "Quick guest use" preset above to filter all 13 options.

Which scanned pdf ocr tool scored highest on task quality and overall performance?

By overall task score, PDF24 Tools ranks first (98/100, tested 2026-10-25); by task quality score alone, PDF24 Tools leads (65/100), while copychecker.com recorded the fastest server wait (0s).

How should I choose between one-off guest use and commercial plans for scanned pdf ocr?

For a one-off file, start with the 13 guest watermark-free tools or pay-as-you-go credit packs to avoid recurring subscriptions. For team or client work, use the "Verified commercial plan" preset to inspect the 0 tools with sourced commercial rights.

What do these results cover?

Historical records cover specific fixtures and test paths. Reports show samples, dates, native files and limitations.

How are tools evaluated?

Evaluation covers quality, exports, speed, pricing, interaction, background and privacy. Scores and reasons are available in each report.

Benchmark evidence preview

Open original ↗