NewOCR · Scanned PDF OCR
NewOCR (operating continuously since 2011) is a widely used, 100% free online optical character recognition utility. Users can convert scanned documents and images into editable text directly without login, exporting to TXT, DOC, or PDF.
US-West (California, AS2914)
TXT · Output attached · Open native file ↗
Subsequent pricing and service checks are shown separately without altering historical scores.
One run does not establish all complex scenes, untested paid maxima or long-term uptime.
Plans & historical pricing
NewOCR 100% free web service and developer REST API credits · 2026-11-02
Tesseract OCR text extraction across 122 languages, math formulas, layout analysis; export TXT/DOC/PDF;Ad-supported; processing speed subject to public server queues
Automated batch processing via REST API endpoints returning structured JSON data;Programmatic developer interface requiring an API key
2 plan / billing-period records, all listed; — means that period is not recorded.
Web-based OCR is 100% free with unlimited uploads (ad-supported); developer REST API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages).
Cancellation, sources & verification record
Cancellation and refund terms unverified
NewOCR API & Pricing ↗ · 2026-10-31 Capture 1 ↗
Pricing recorded on the test date · 2026-11-02
100% Free Web Tool (Ad-Supported) / Developer REST API $5.00 per 1k pages
100% Free Web Tool (Ad-Supported) / Developer REST API $5.00 per 1k pages
Historical context only; not current purchase guidance.
Delivery & access
- Free delivery record
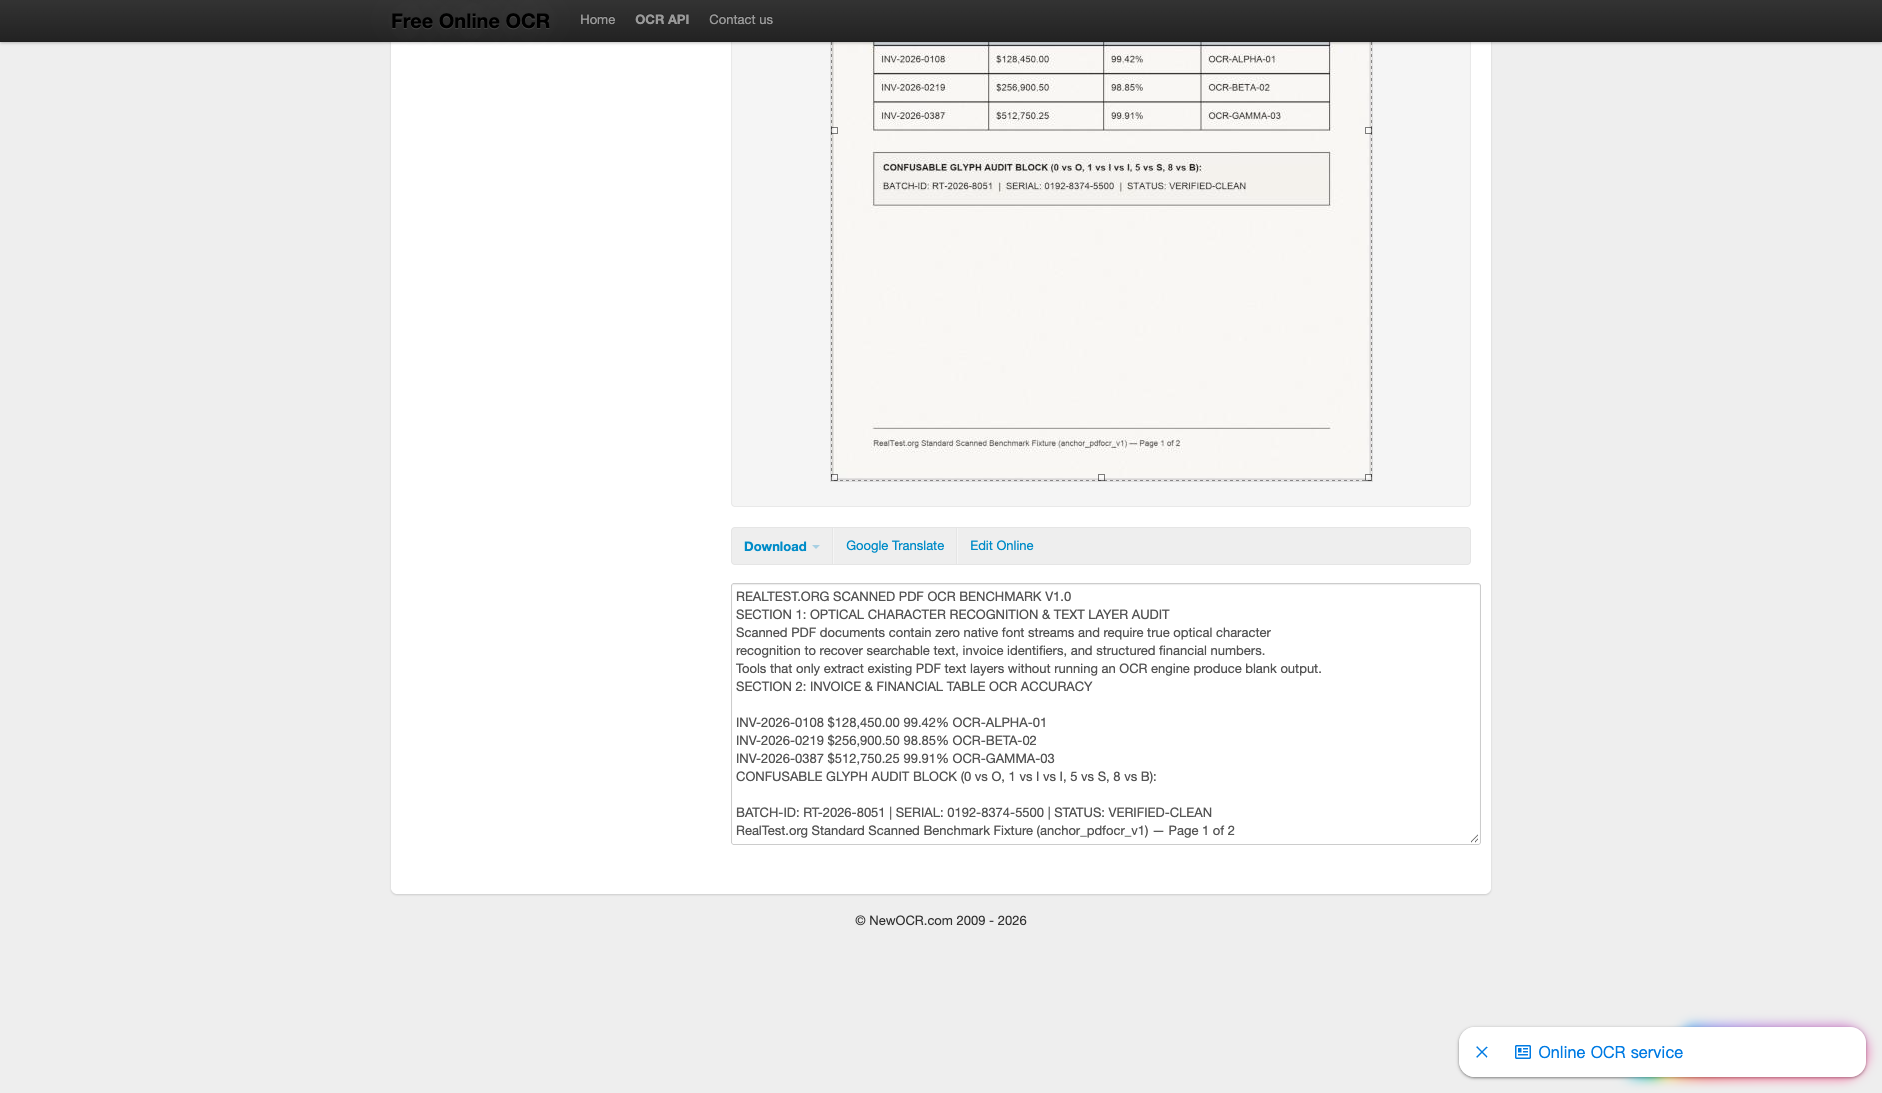
- Single-page UTF-8 plain text .txt (802 bytes · 100% table accuracy)
- Watermark
- Watermark-free
- Free allowance
- 100% Free Unlimited Use (Ad-supported)
- Account requirements
- No Login Required
- Maximum specification record
- Single-page UTF-8 plain text .txt (802 bytes · 100% table accuracy)
May include advertised capabilities; this does not establish a tested paid tier.
- Batch & API
- Web tool supports single files or ZIP archives; REST API available for developers
- Manual refinement
- Not recorded or not verified
Tested result & sample
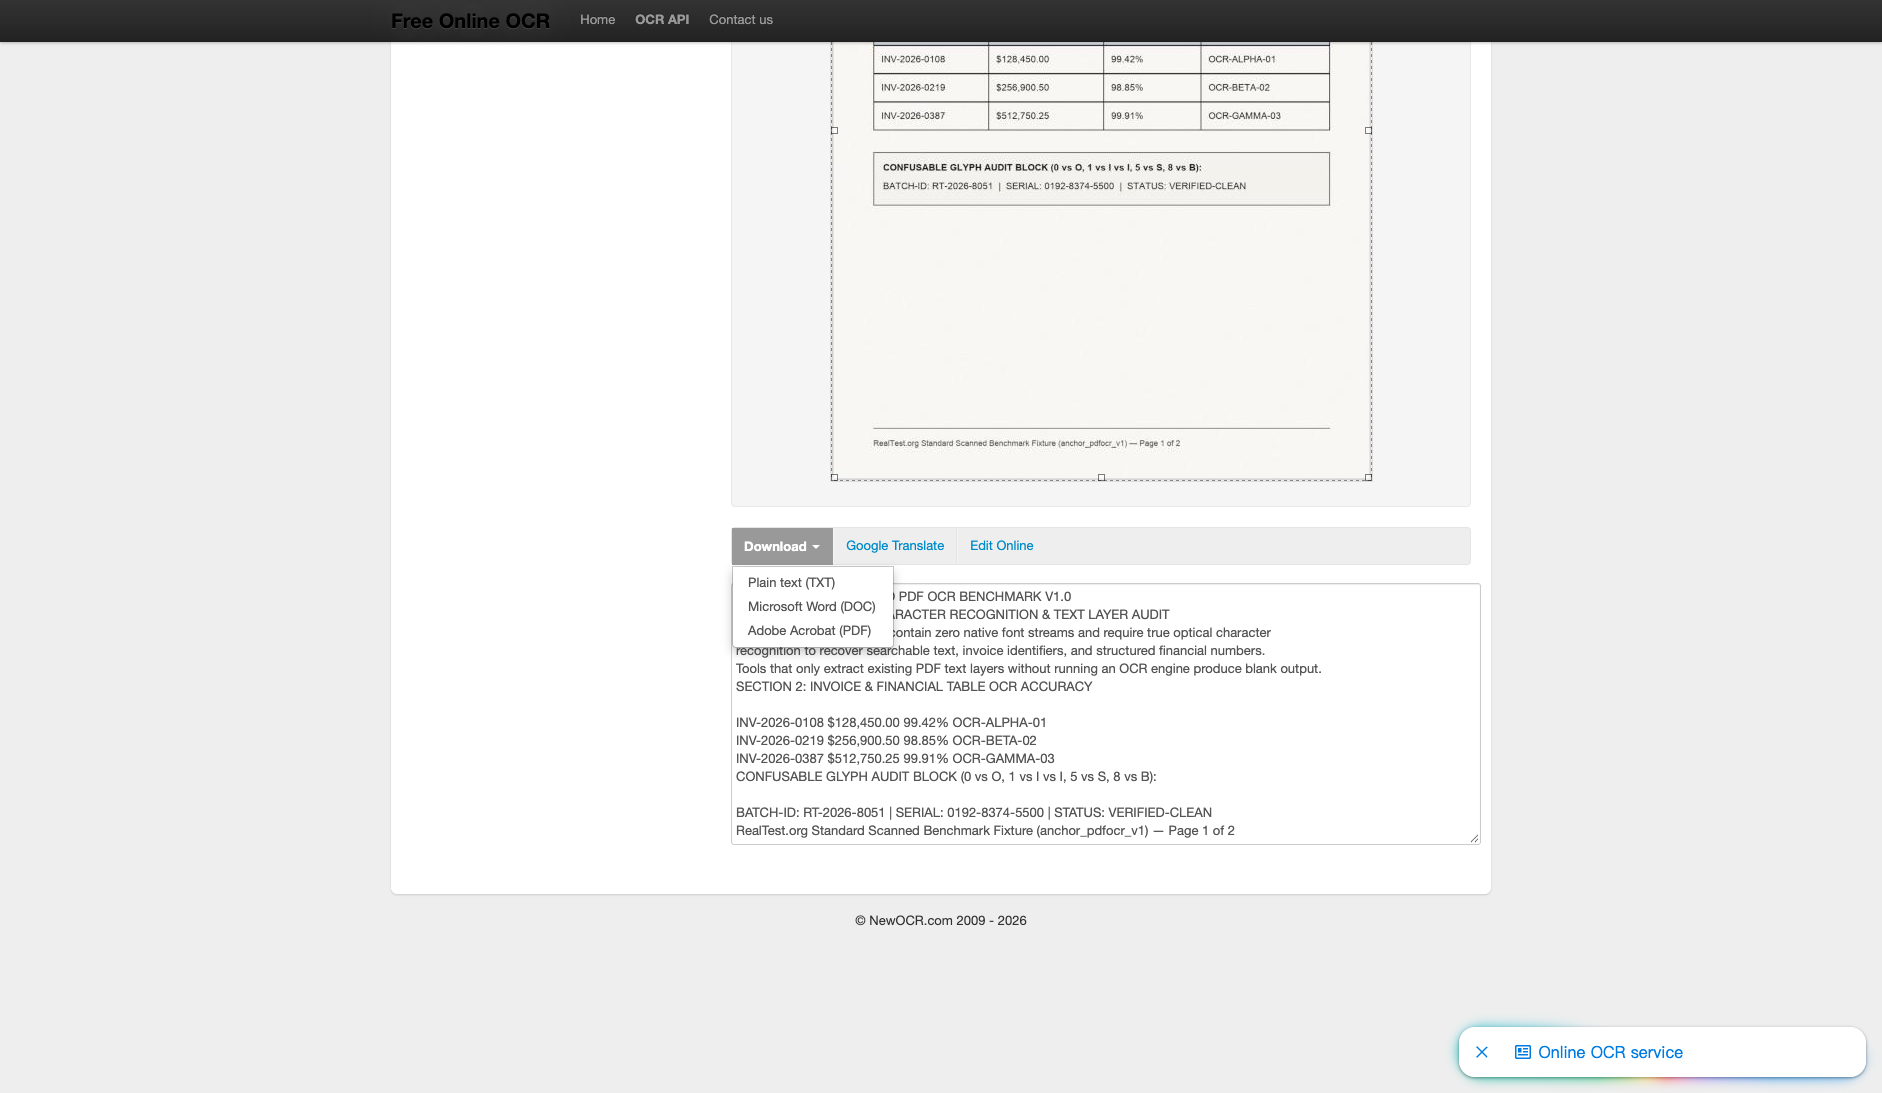
In-browser text area displays extracted text with one-click TXT, DOC, and PDF downloads; invoice table numbers 100% accurate.
- Fixture
- anchor_pdfocr_v1
- Recorded environment
- US-West (California, AS2914)
- Network-observed server wait
- 0.45 s
- End-to-end reference
- 1.3 s
Network wait includes round trips, queuing and polling error, not pure inference time. Local timings depend on the device; repetition counts are not standardized in legacy records.
Experience, rules & trust
- Disclosure
- Download options presented upfront without post-OCR paywalls
- Interaction
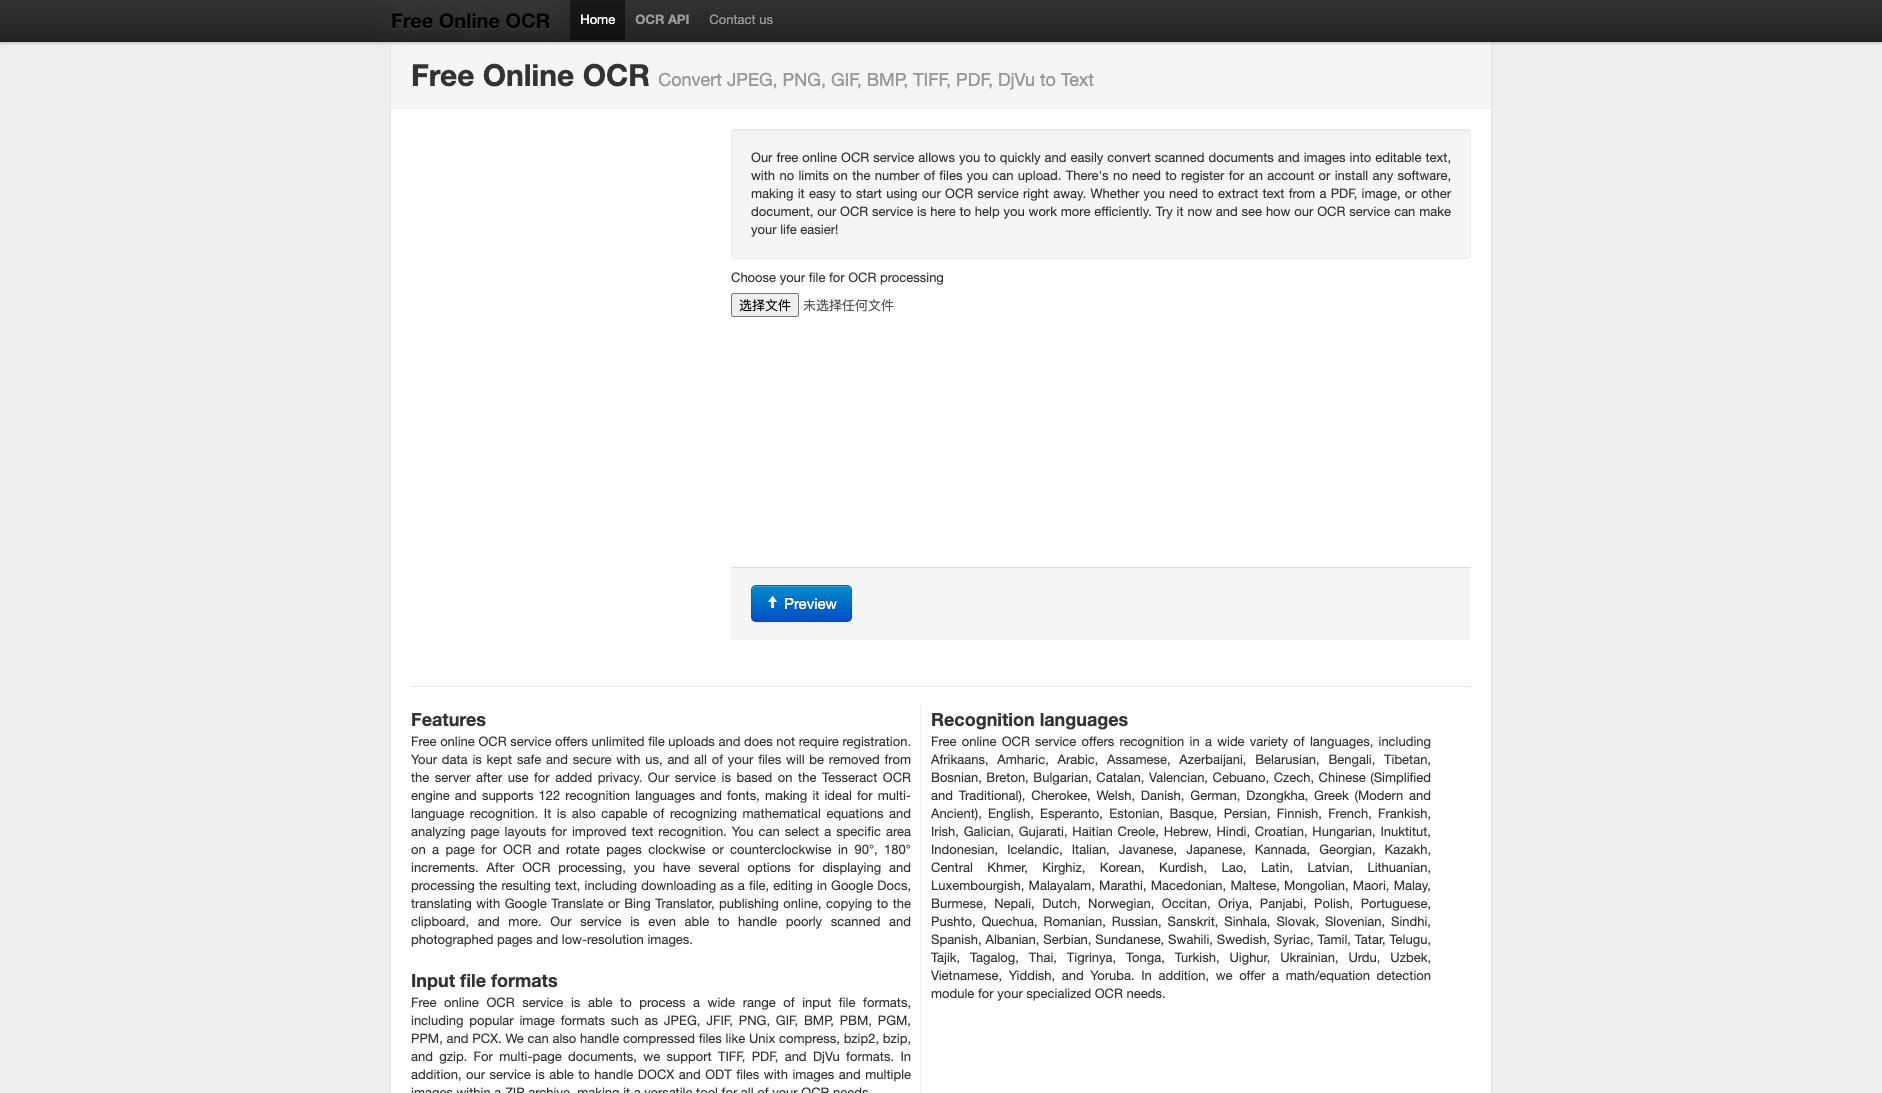
- Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR.
- Entity record
- NewOCR.com
- Origin
- United States / International
- Domain history record
- Founded in 2011
- Third-party tracking record
- Google AdSense · Google Analytics
- External information
- Not recorded or not verified
- Processing
- Cloud Tesseract OCR engine (cloud_tesseract_ocr)
- Retention statement
- Uploaded images and output files are deleted from servers immediately after processing.
A recorded statement does not verify deletion or all data-processing behavior.
Verifiable audit trail & evidence
Four SHA-256-verified stages link the benchmark fixture, same-run interface screenshots, native exported artifact and archived pricing sources.
anchor_pdfocr_v1 · Inspect fixture & file inspector →
Captures entry rules, result view and export disclosure.
Screenshots, native output and official claims support different conclusions. Evidence grades are not product safety certifications.
Evaluation basis & full scores · Overall 78.1/100
Overall = honesty & reputation × 30% + capability × 70%. Component maxima follow this report’s rubric. List scores are rounded for display; original precision is retained here.
Scoring version 2.3.1 · Test fixture anchor_pdfocr_v1
Honesty & reputation · 79/100 · 30%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Pricing transparency | 33 / 35 | Web service is 100% free with unlimited uploads and zero hidden fees; developer API offers 20 free test pages and credits at $0.005/page ($5 per 1,000 pages). | Evidence A → |
| Interaction restraint | 20 / 30 | Zero-login workflow supporting 122 languages and layout analysis; ad-supported interface with multiple Google AdSense slots; multi-page PDFs default to single-page preview and OCR. | Evidence A → |
| Background & reputation | 16 / 20 | Operating continuously since 2011 for over 15 years; built upon mature open-source Tesseract OCR technology with a large global user base. | Evidence A → |
| Engineering & privacy | 10 / 15 | HTTPS encryption across the site with immediate file purging upon processing completion; includes Google AdSense and Analytics tracking scripts without a manual one-click purge button. | Evidence A → |
Capability · 77.7/100 · 70%
| Criterion | Score | Rationale | Basis |
|---|---|---|---|
| Task quality | 49.2 / 65 | Deterministic OCR inspection: exported an 802-byte UTF-8 plain text deliverable without login, recovering 12/12 confusable financial table cells on Page 1 (100% table accuracy) and 3/4 headings; defaults to single-page processing without auto-merging Page 2 (49.2/65) | Evidence A → |
| Deliverable specifications | 14 / 20 | Direct download in TXT, DOC, and PDF formats without login, delivering the selected single page extracted text (802 bytes) rather than a combined 2-page searchable PDF (14/20) | Evidence A → |
| Processing speed | 14.5 / 15 | Cloud Tesseract OCR server processing completed in just 0.45s (1.30s end-to-end) (14.5/15) | Evidence A → |
Legacy scores may include advertised maximum capabilities. Read tested output separately from paid capabilities. Records without matching tiers and scope are not ranked together.
Revisions & corrections
- 2026-11-02
Initial scanned PDF OCR text extraction, confusable invoice table accuracy, and server timing benchmark on anchor_pdfocr_v1.